
In-App Annotation#
Managing an annotation team?
Learn how Voxel51 can help you organize and coordinate annotation work across your team with FiftyOne Projects!
Overview#
This guide will walk you through the basics of FiftyOne’s in-App annotation features.
Currently in-App annotation is designed for ad hoc, sample-by-sample metadata editing. The features and controls extend FiftyOne’s existing data visualization UI. Once you have samples loaded into a FiftyOne dataset, you can begin defining your Annotation Schema and labeling your data in the App.
Basics#
Supported Media and Label Types#
In-App annotation within FiftyOne supports datasets containing the following media and label types:
-
image, including ordered dynamic groups played as videovideo3D
-
ClassificationRegressionDetectionsInstance segmentations2D Polylines and Polygons3D Polylines3D CuboidsEvents (Temporal Detections)
Annotation UI: Sample Visualizer#
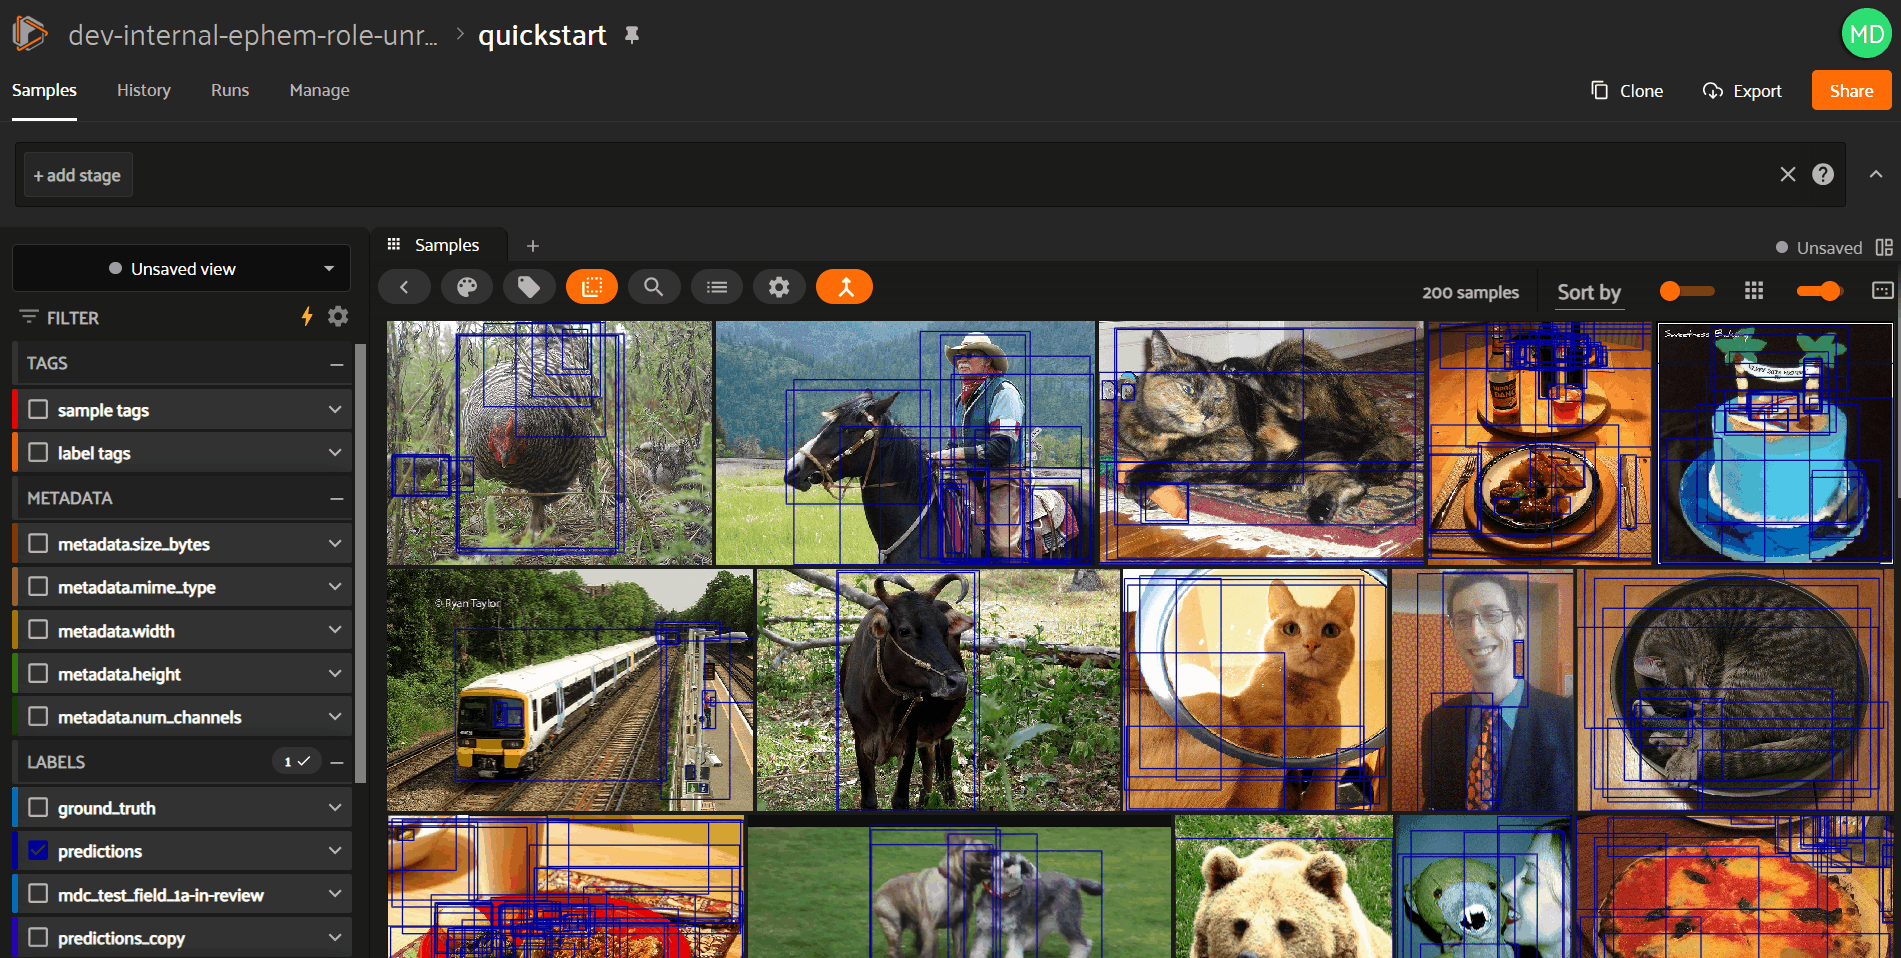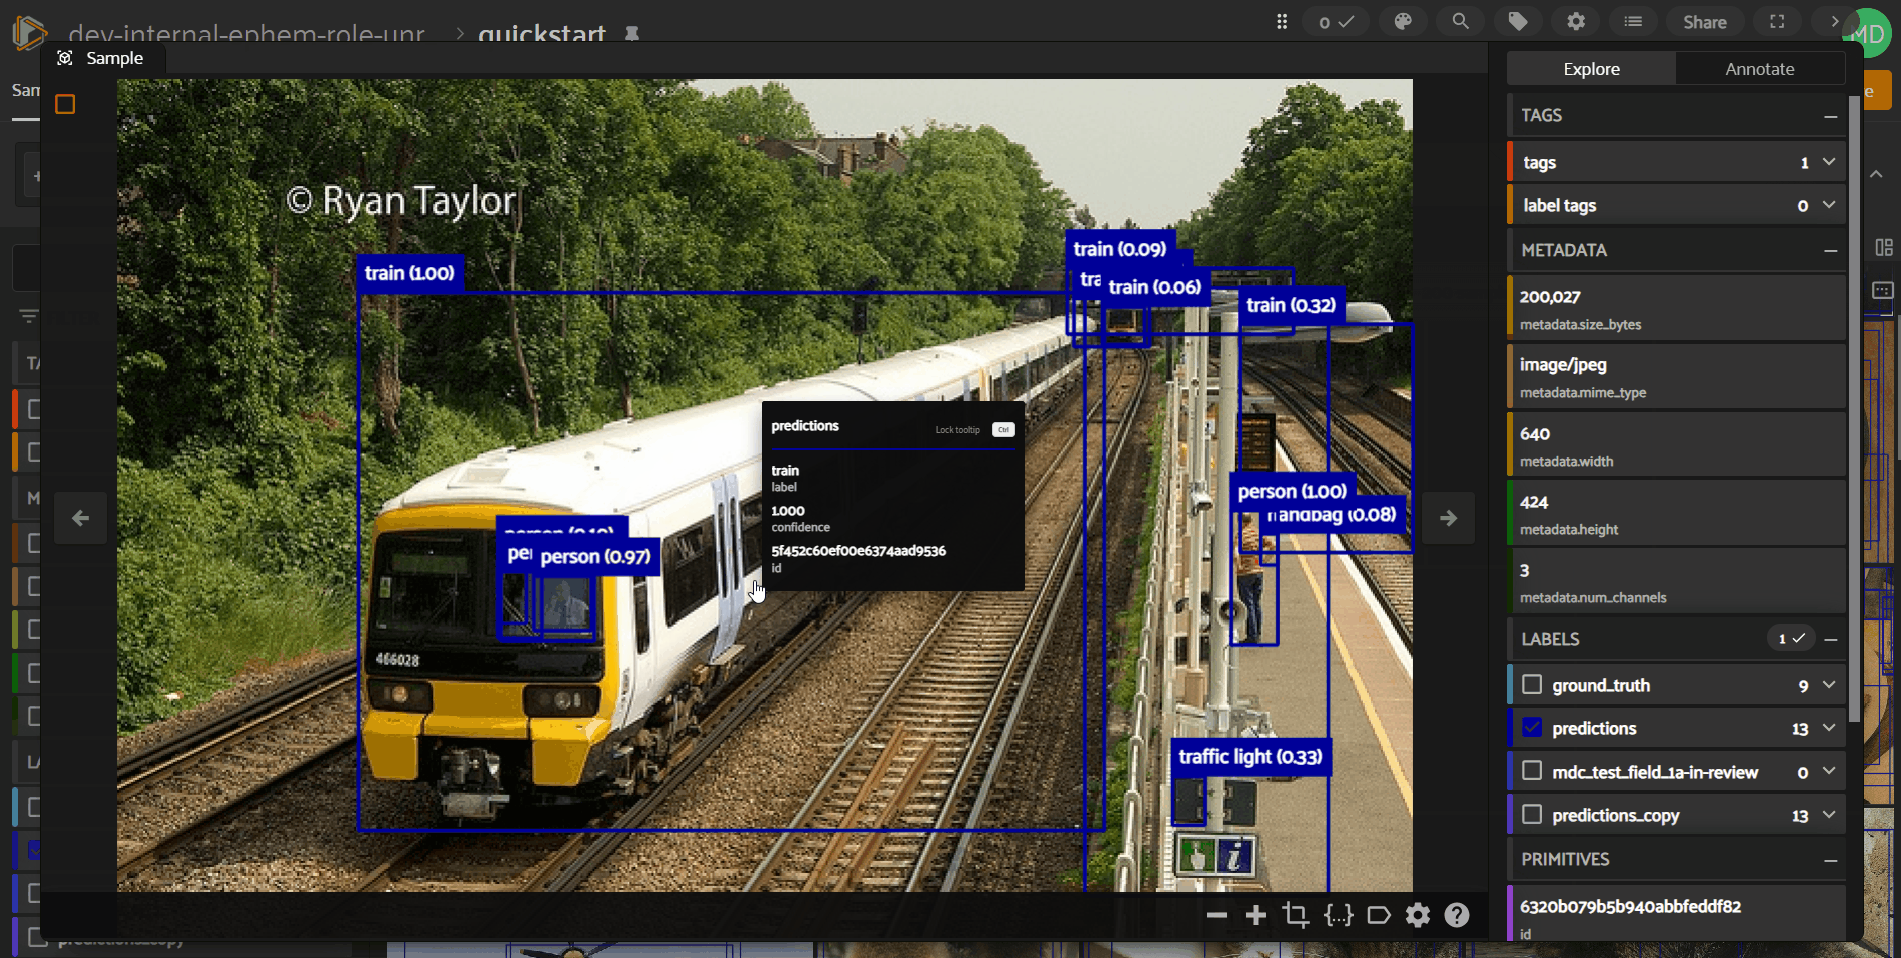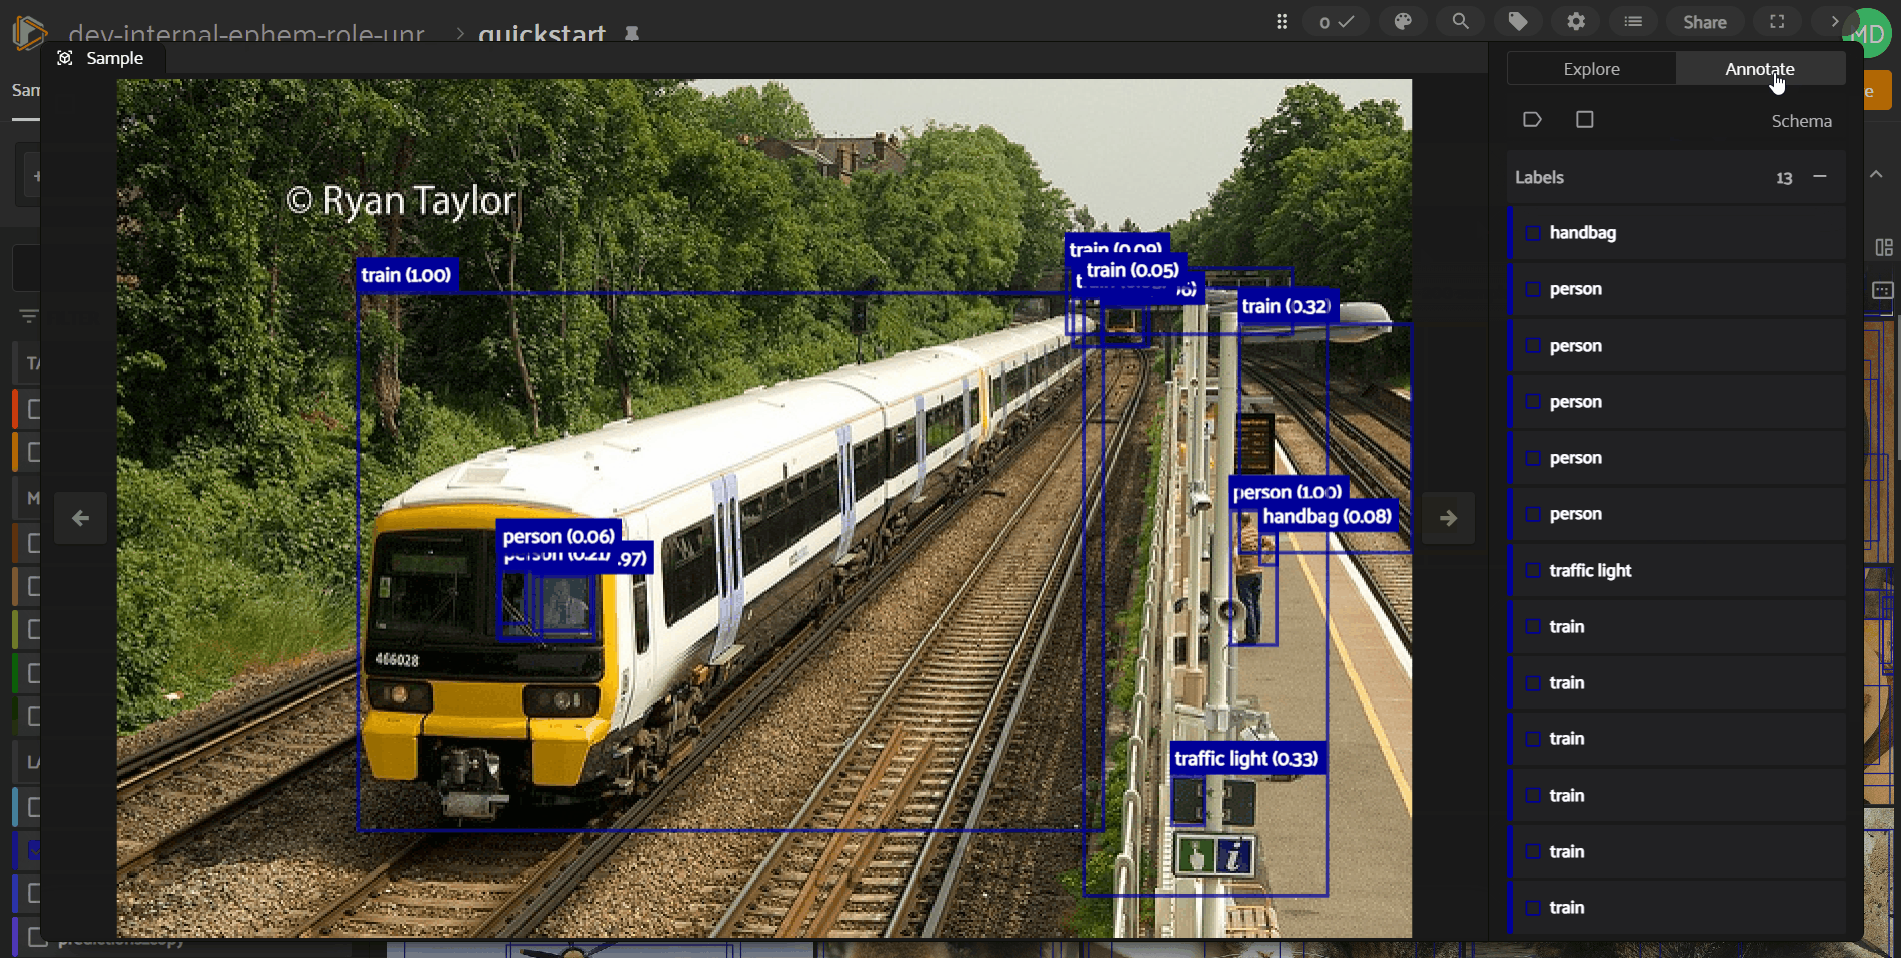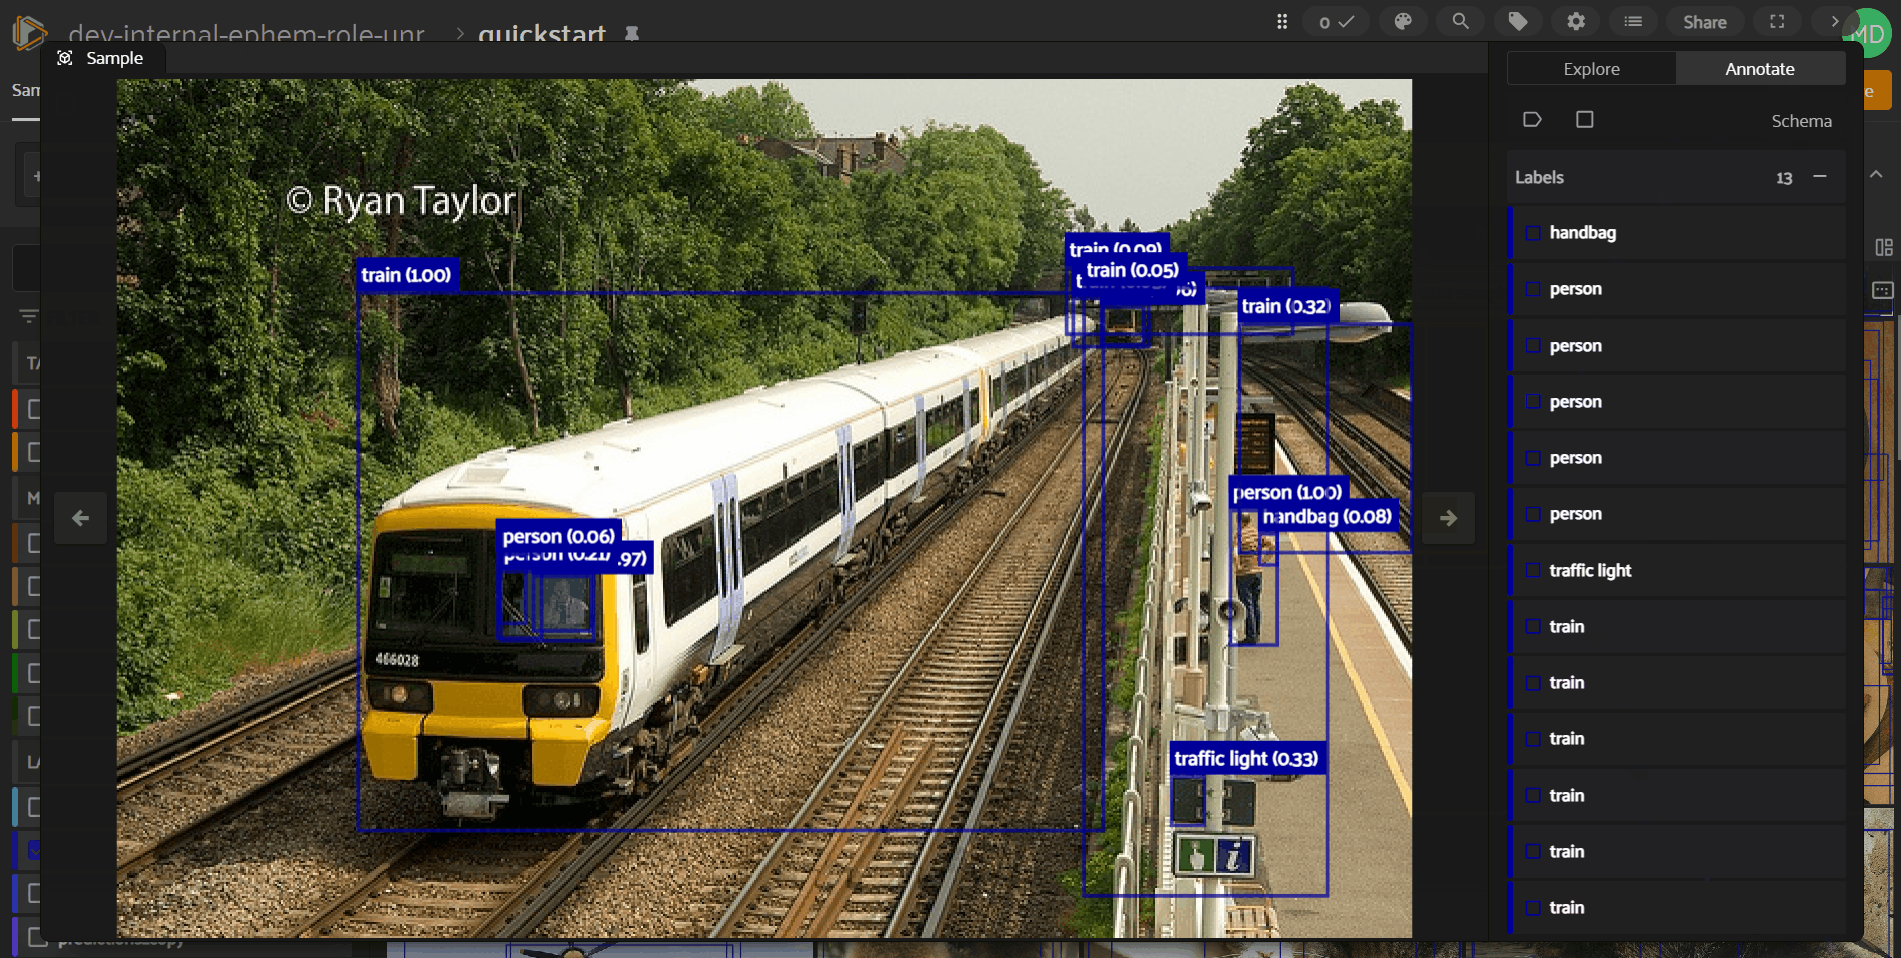
All in-App annotation controls now live in the expanded view for samples. Open a sample in the expanded view, and find the new “Annotate” tab in the right sidebar.
Saving and Reverting Changes#
When you make changes to sample metadata with FiftyOne’s in-App annotation, your changes automatically save to the database. The auto-save functionality triggers either explicitly after an action (e.g., deleting a label) or after a short period of time (e.g., updating the spatial properties of a bounding box multiple times in succession), depending on the action.
You can tell whether your changes are saved or are in the process of being saved thanks to this indicator:
Undo/Redo#
While editing metadata, you can undo and redo actions using the buttons in the upper-right corner of the “Annotate” panel, or via Cmd+Z to undo and Cmd+Shift+Z or Cmd+Y to redo. On Windows and Linux, use Ctrl+Z and Ctrl+Shift+Z. Your changes included in the undo stack are limited to your active annotation session, i.e., while the expanded view remains open.
User Guide#
Schema Import / Management#
To perform in-App annotation, your dataset must first have an “Annotation Schema”. For a field, attribute, or value to be available in in-App annotation, it must be present in the Annotation Schema. Currently, you may only have one Annotation Schema per dataset, and your Annotation Schema applies across all samples and views on the dataset.
Warning
Only users with “Can manage” access to a dataset may import and manage the Annotation Schema on that dataset.
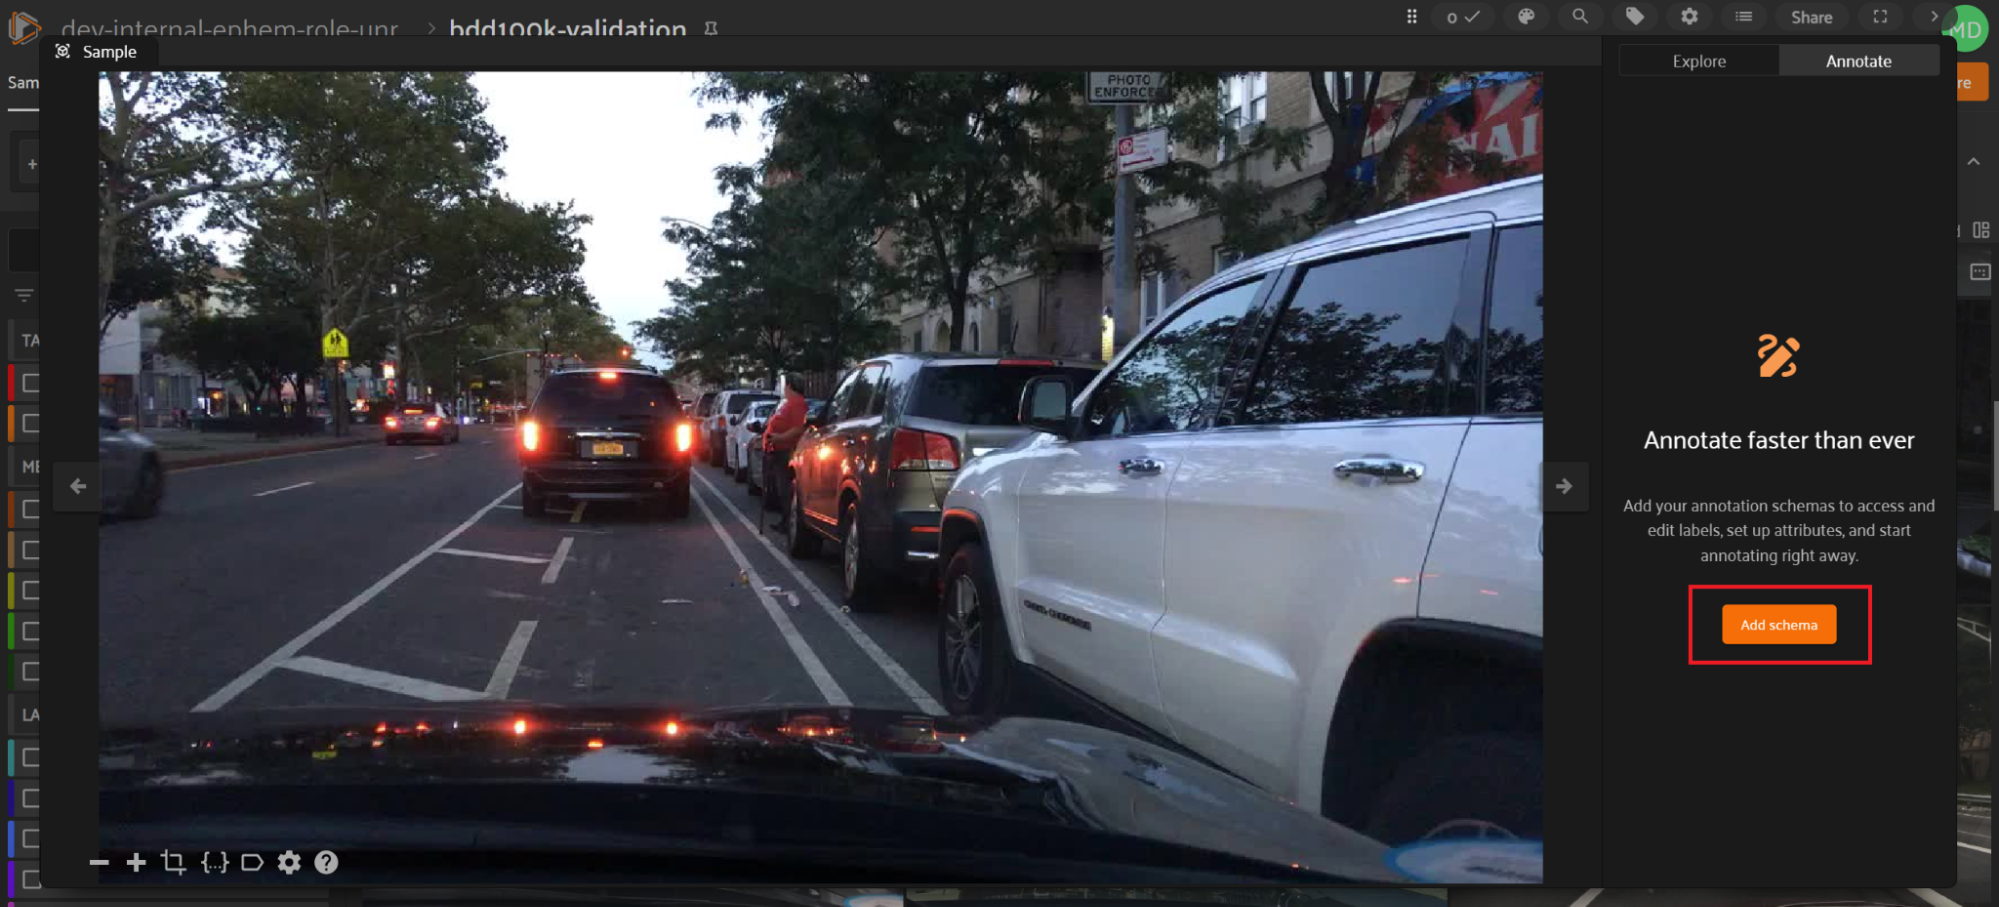
When accessing the “Annotate” tab in the expanded view on a dataset for the first time, you’ll see a button to create the Annotation Schema. By default, no fields in the dataset schema are included automatically in the Annotation Schema; you’ll need to explicitly add fields, attributes, and values.
Supported Field Types#
FiftyOne’s in-App annotation supports two groups of field types: label-type fields (e.g., Detections or Classification) and non-label-type primitive fields (e.g., StringFields or IntFields). Your Annotation Schema can be a mix of fields within these groups. The parameters available for configuring fields’ schemas in your Annotation Schema will depend on the type of field (see: Annotation Schema Format).
Schema Manager#
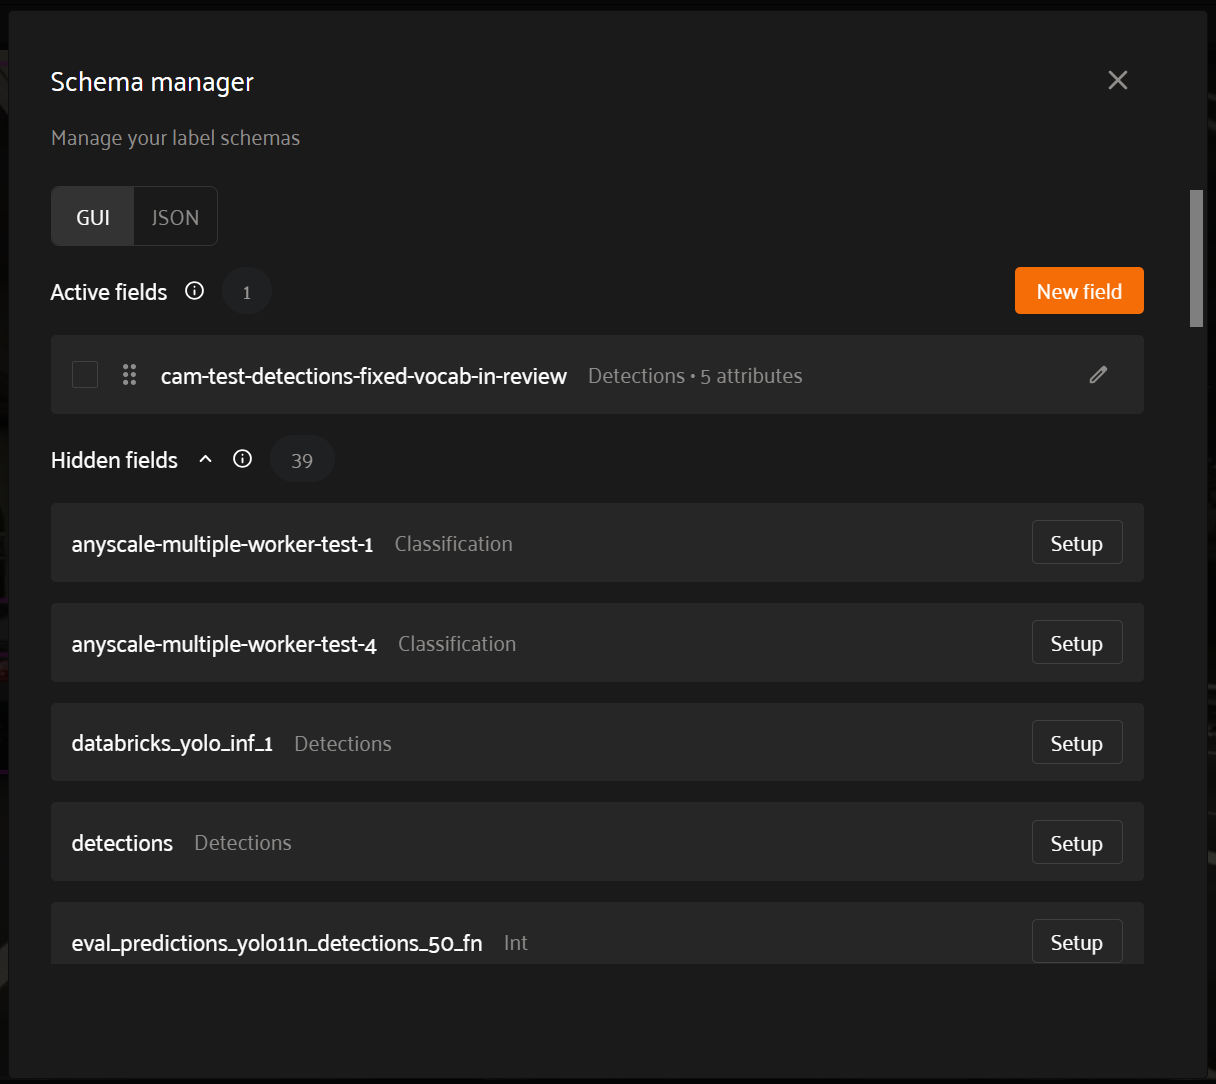
The “Schema Manager” user interface defines the Annotation Schema for the dataset. Open it from the gear icon at the top of the “Annotate” panel. The main page features a schema picker, a search box, and two sections: “Active fields” and “Hidden fields”.
“Active fields” are the fields available in the “Inspect” and “Annotate” sidebars. A field that has been set up, that is, one with a label schema, is annotatable. A field that has not been set up yet is unscanned: you can inspect it but not edit it until you click “Set up” and configure its schema.
“Hidden fields” are fields that never reach anyone viewing through the selected schema, whether in the grid, the sidebars or the sample data. The default schema has no hidden fields. To hide fields, create a custom schema, select the fields you want under “Active fields”, and move them to “Hidden fields”.
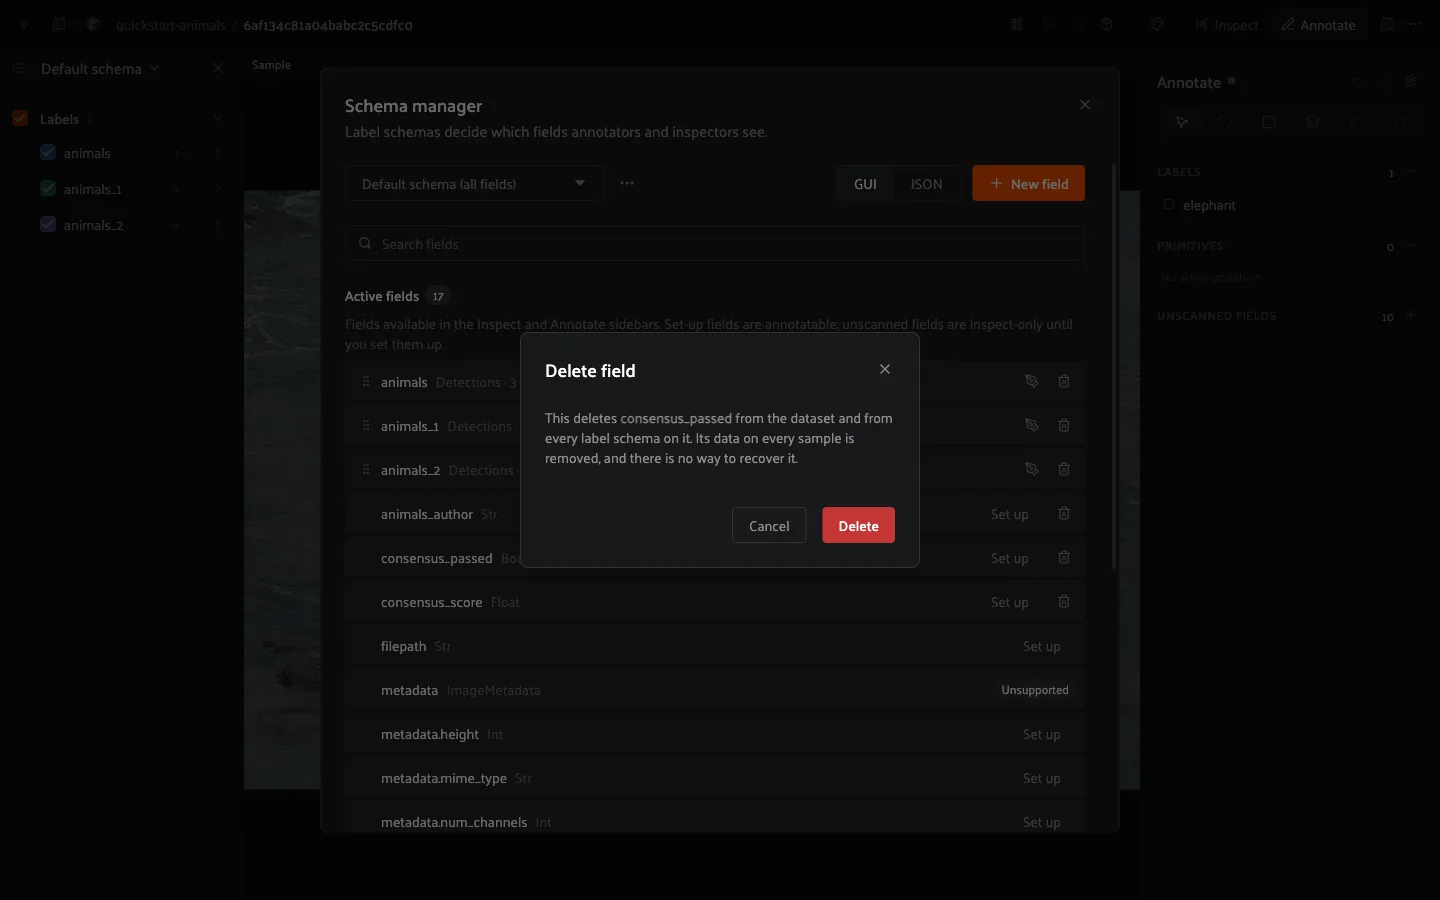
To delete a field, click the 🗑️ icon next to it in “Active fields” and confirm. This deletes the field from the dataset and from every label schema on it, and removes its data from every sample.
Warning
Deleting a field also deletes its data, and there is no way to recover it.
Custom schemas#
The schema picker at the top of the Schema Manager switches between the dataset’s schemas:
Default schema (all fields) is the dataset’s own annotation schema. Every field is visible and nothing is hidden. It is not stored as a separate schema.
Custom schemas are named schemas that you create from the picker’s menu. Each one decides, field by field, who can see and edit what.
In a custom schema every field is either active or hidden:
Active fields are visible to anyone viewing through the schema. Each active field can also be configured separately, for example as read-only so that a model’s predictions stay as context.
Hidden fields are removed from the grid, the sidebars and the sample data, for example ground truth that annotators should not see.
Do not delete a custom schema while a batch uses it. The batch’s stages stop applying it, so fields you hid may become visible to annotators.
Attributes of an active field can be set the same way, so you can make an attribute read-only or hide it. To check what someone viewing through a custom schema will see, choose it in the schema lens, the dropdown at the top of the left sidebar. The grid, the sidebars and the sample data apply it right away.
Note
FiftyOne Enterprise can enforce a custom schema on an annotation task. When a stage of a batch’s workflow references a schema, everyone who opens that stage’s tasks sees only what the schema allows.
Ordering in the Annotation Schema#
Across the Schema Manager you’ll see handles to drag-and-drop fields, classes, attributes, and values within sections. You can reorder this information to update how values appear in the “Annotate” tab of the sample expanded view.
For example, reordering a primitive field foo above another primitive field bar will cause foo to appear above bar in the list of primitives in the “Annotate” tab.
Configuring a Field Schema#
Before you can add a field to the Annotation Schema, you must first configure its schema. Click the ✏️ icon on any field in the Schema Manager (including both the “Active fields” and “Hidden fields” sections) to open the “Edit field schema” page and configure that field’s schema.
You can compose a field’s schema from scratch, or scan all samples across the dataset to import metadata. If you choose to scan the dataset, you may edit the results of that scan before saving the schema.
Warning
Because scanning for metadata looks at samples across your entire dataset, it could take a few seconds or minutes.
The “Edit field schema” page includes two ways for you to configure the field’s schema: GUI or JSON. Both interfaces represent the same data model, and any updates you make in one interface should update the data model’s representation in the other interface in realtime.
Annotation Schema Format#
The in-App Annotation Schema format is borrowed from FiftyOne’s existing label_schema format (historically supported for requesting annotations from third-party backends).
For label-type fields, classes are a first-order list of classes available for selection on all instances of your label across samples in your dataset. Label-type fields also have attributes, which are optional semantic properties whose values may also be edited across samples on your dataset.
For both primitive fields and attributes, the following properties apply:
type: the data type (e.g.,int,str).component: the UI component through which values are edited on the “Annotate” tab. Availablecomponents include:text: a free text field. Applicable whentypeisstr,int,float, orlist.dropdown: an autocomplete dropdown menu. Applicable whentypeisstr,int,float, orlist.valuesis required.radio: a radio button group. Applicable whentypeisstr,intorfloat.valuesis required.slider: a numeric slider and numeric input boxes. Applicable whentypeisintorfloat.rangeis required.toggle: a toggle where one and only one of two possible options must be selected. Applicable whentypeisbool.datepicker: a calendar date picker component. Applicable whentypeisdateordatetime.json: an editable JSON code block. Applicable whentypeislistordict.
values: the list of allowed values available for selection in theattributeor primitive.range: the[min, max]values available for numerictypes, used in theslider. Whenrangeis defined,valuesmust be omitted.default: the default value assigned to the attribute on new label instances. Not applicable to primitive fields.
Reserved attribute names
When configuring your field’s schema, you may not use any of the following reserved key names:
coloridisNewpathselectedsampleIdtype
Configuring with GUI#
Here you’ll see different sections depending on whether your field is a label-type, or a non-label primitive field.
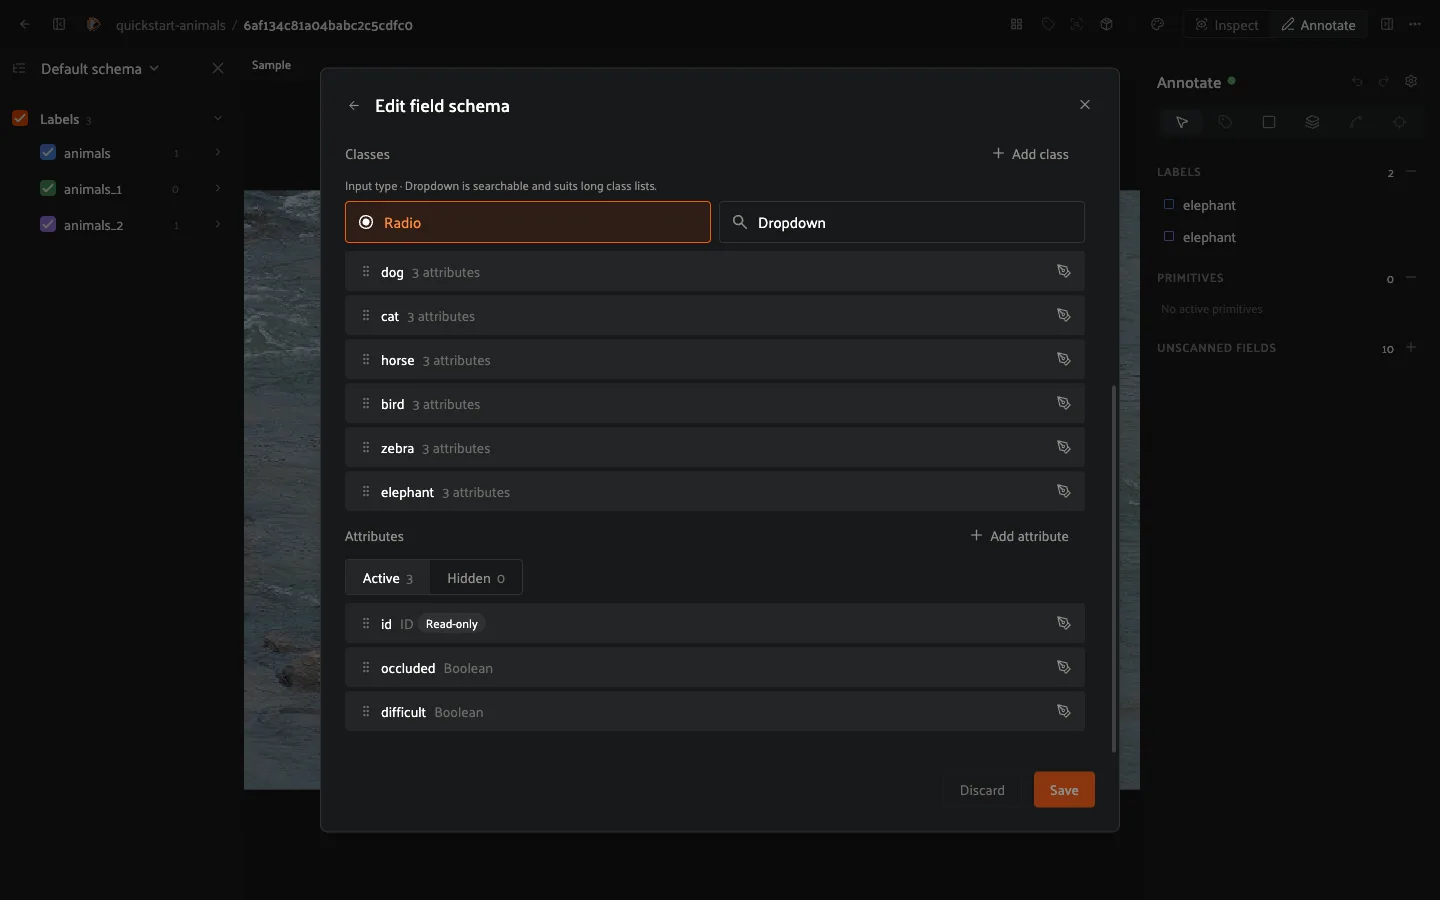
For label fields, you’ll see sections for adding and editing label classes and attributes. Click the “+Add class” or “+Add attribute” buttons to create new classes and attributes, respectively.
For each class and attribute in the GUI:
Click the ✏️ icon to edit its properties.
Click the 🗑️ icon to delete.
Drag and drop
classesorattributeswithin sections to reorder within the Annotation Schema (see: Ordering in the Annotation Schema).
For primitives, depending on your field’s data type, you’ll see optional and/or required properties to configure for your field’s schema.
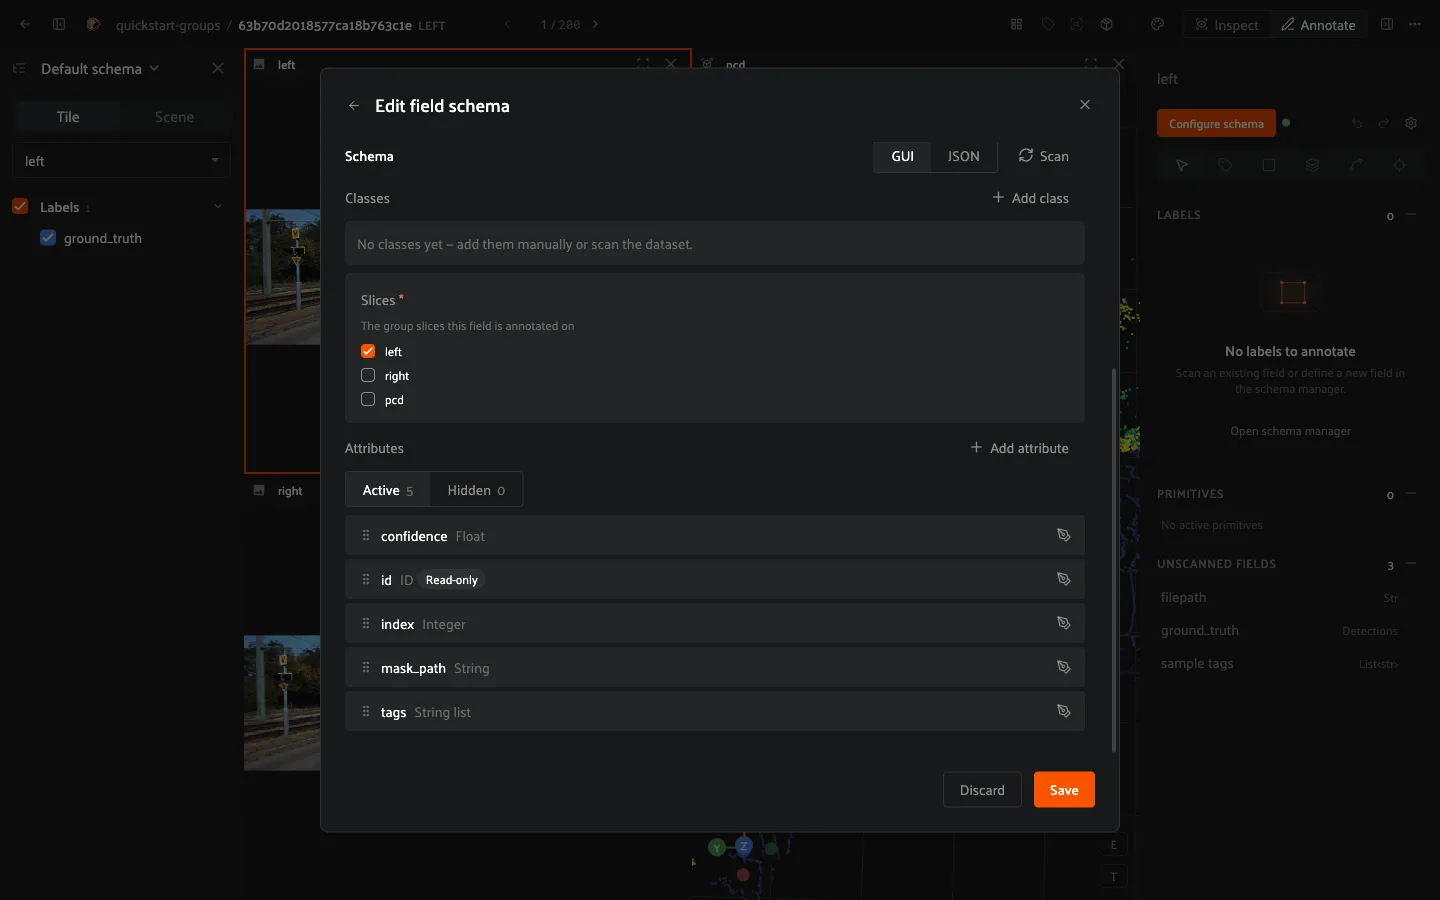
On a grouped dataset, label fields also have a “Slices” section. Check the group slices the field is annotated on: the field applies only to those slices, and you must choose at least one.
Creating New Fields#
Click the “New field” button in the Schema Manager to begin creating a new field on your dataset.
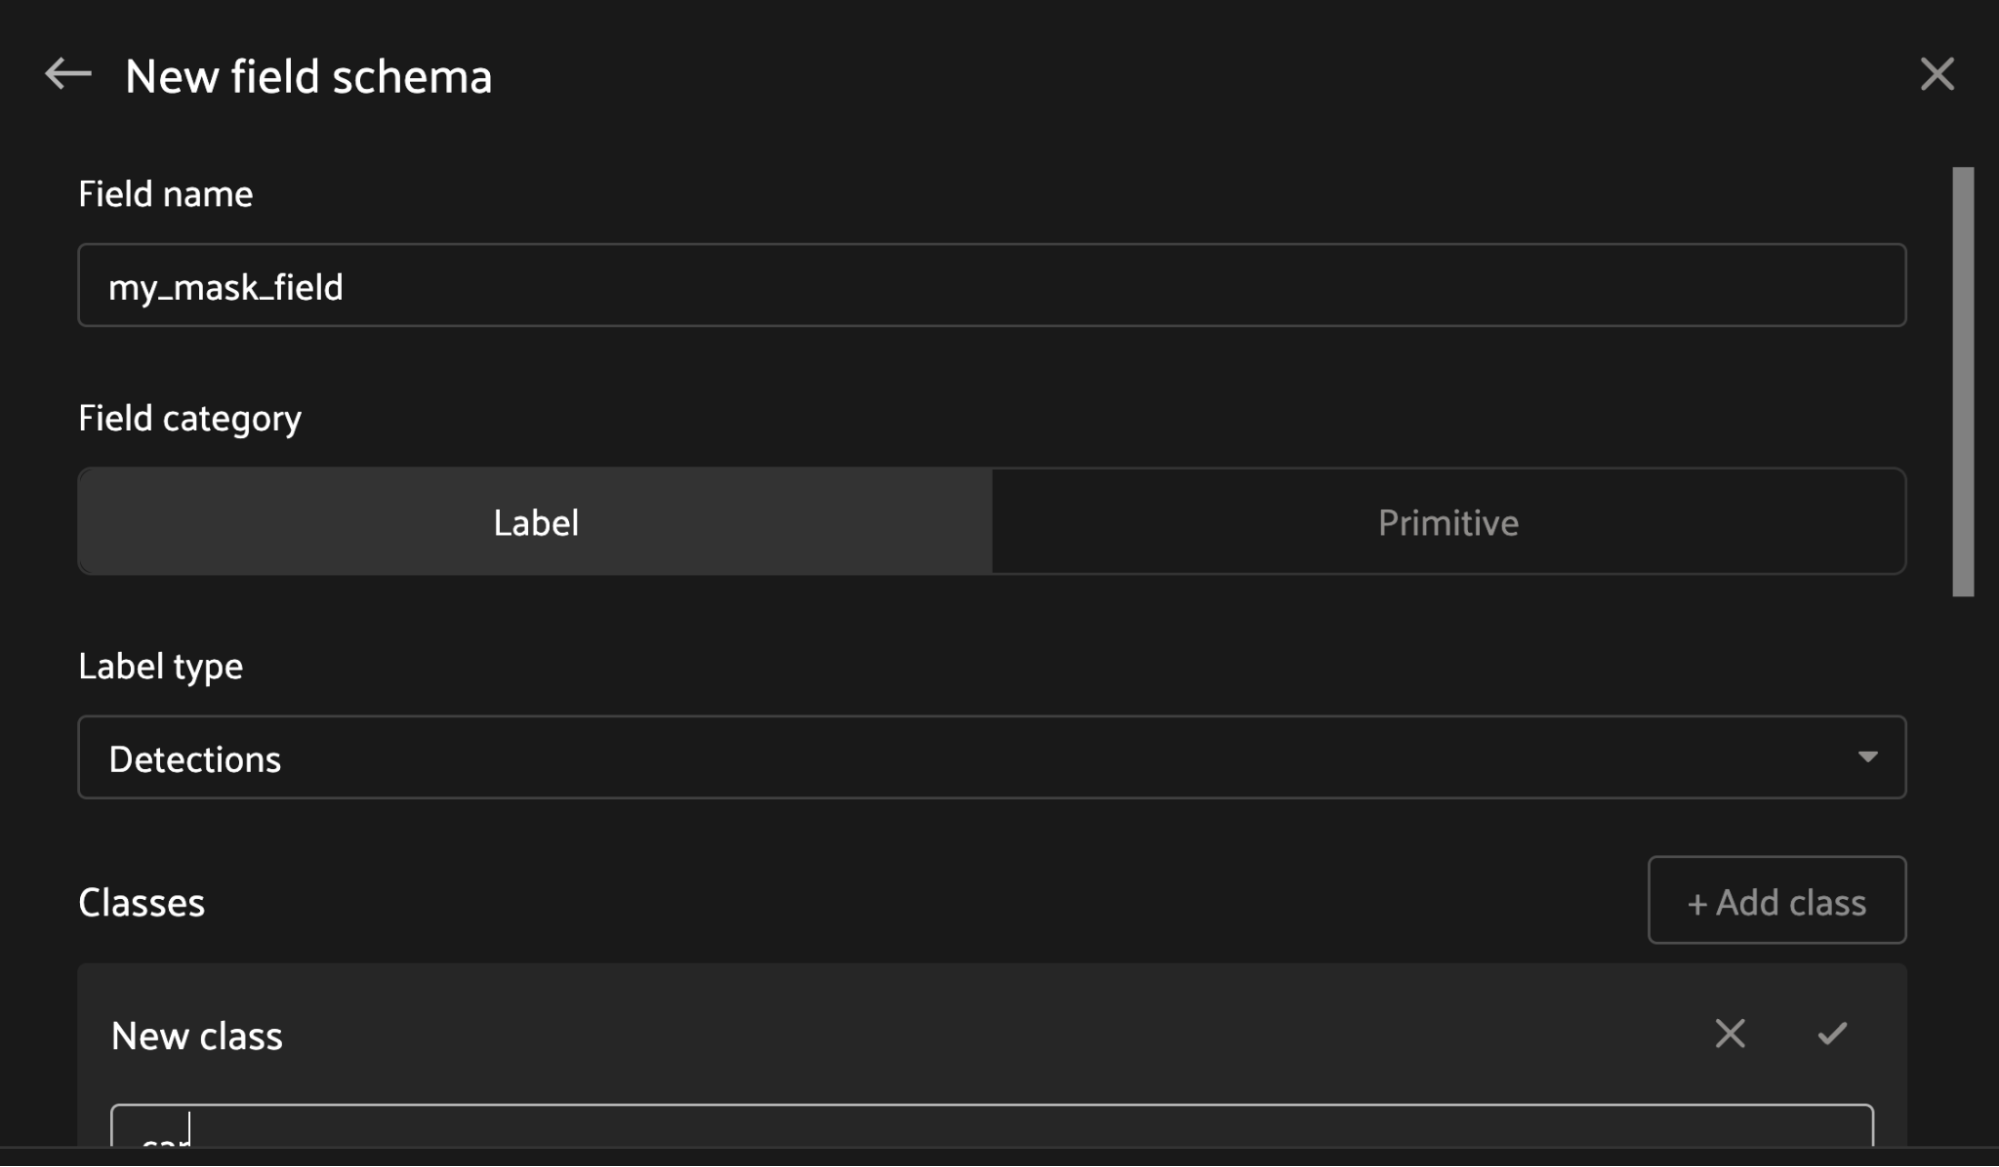
On the next screen, you’ll need to provide a unique name for your new field. Next, choose whether your new field should be a label-type field, or primitive. In either case, open the “Field type” dropdown menu to choose a data type for your new field.
You’ll then see different sections depending on your choices. Once you are satisfied with your new field’s configuration, click the “Save” button, and two things happen:
Your new field immediately gets written to the database
Your new field is added as an “Active field” in the Annotation Schema
To cancel at any time while configuring your new field, click the “Discard” button.
Ontologies#
An Annotation Ontology is a global, named, versioned resource that bundles a reusable set of typed attributes — with optional conditional display logic — into a single document that can be attached to a label schema field. Ontologies live outside any dataset, so multiple datasets and fields can reference the same ontology by name.
Create and save an ontology with the SDK:
import fiftyone as fo

ontology = fo.AnnotationOntology(
    name="vehicle_damage_ontology",
    attributes=[
        fo.AttributeSpec(name="damage_present", type="bool", component="toggle"),
    ],
)
ontology.save()
Attach the ontology to a field on a dataset’s label schema:
import fiftyone as fo

dataset = fo.load_dataset("my_dataset")
label_schemas = fo.apply_ontology(
    dataset.label_schemas,
    field_name="detections",
    ontology_name="vehicle_damage_ontology",
)
dataset.set_label_schemas(label_schemas)
Pass ontology_name=None to apply_ontology() to unset an existing
reference on a field.
Conditional Attributes#
Attributes in an Annotation Ontology can be shown
conditionally based on other values on the same label. Pass a when
condition to AttributeSpec — the field may reference any attribute on
the parent, including label itself.
import fiftyone as fo

fo.AnnotationOntology(
    name="vehicles",
    attributes=[
        fo.AttributeSpec(
            name="num_doors",
            type="int",
            component="text",
            when=fo.WhenEquals(field="label", value="car"),
        ),
        fo.AttributeSpec(
            name="cargo_capacity",
            type="float",
            component="text",
            when=fo.WhenEquals(field="label", value="truck"),
        ),
    ],
).save()
num_doors is editable only when the label’s class is car, and
cargo_capacity only when it is truck. Hidden attributes are not
written to the label.
Once this ontology is attached to a label field, annotators will see these conditional attributes in the right sidebar of the in-App annotation UI as they annotate.
You can also set a condition from the GUI. When you add or edit an attribute
in the “Edit field schema” page, set its “Visibility” to “Show only when…” and
add a condition: pick a field of the label, such as label, an operator, and
a value. For example, to ask for a breed only on dogs, add a string
attribute named breed and show it when label is dog. Add more rules to a condition and choose whether “all” or “any” of
them must be true. Conditions are checked from top to bottom and the first
match is used, and “Add condition” adds another one. The attribute is hidden
when no condition matches, unless you turn on “Else” to show it anyway. The
form also lists the classes the attribute is not asked for.
Getting Started with Annotation#
A field appears in the “Annotate” tab once it is in the Annotation Schema. Add it with the Schema Manager. The checkbox next to a field in the sidebar shows or hides its labels, in both the “Inspect” and “Annotate” tabs.
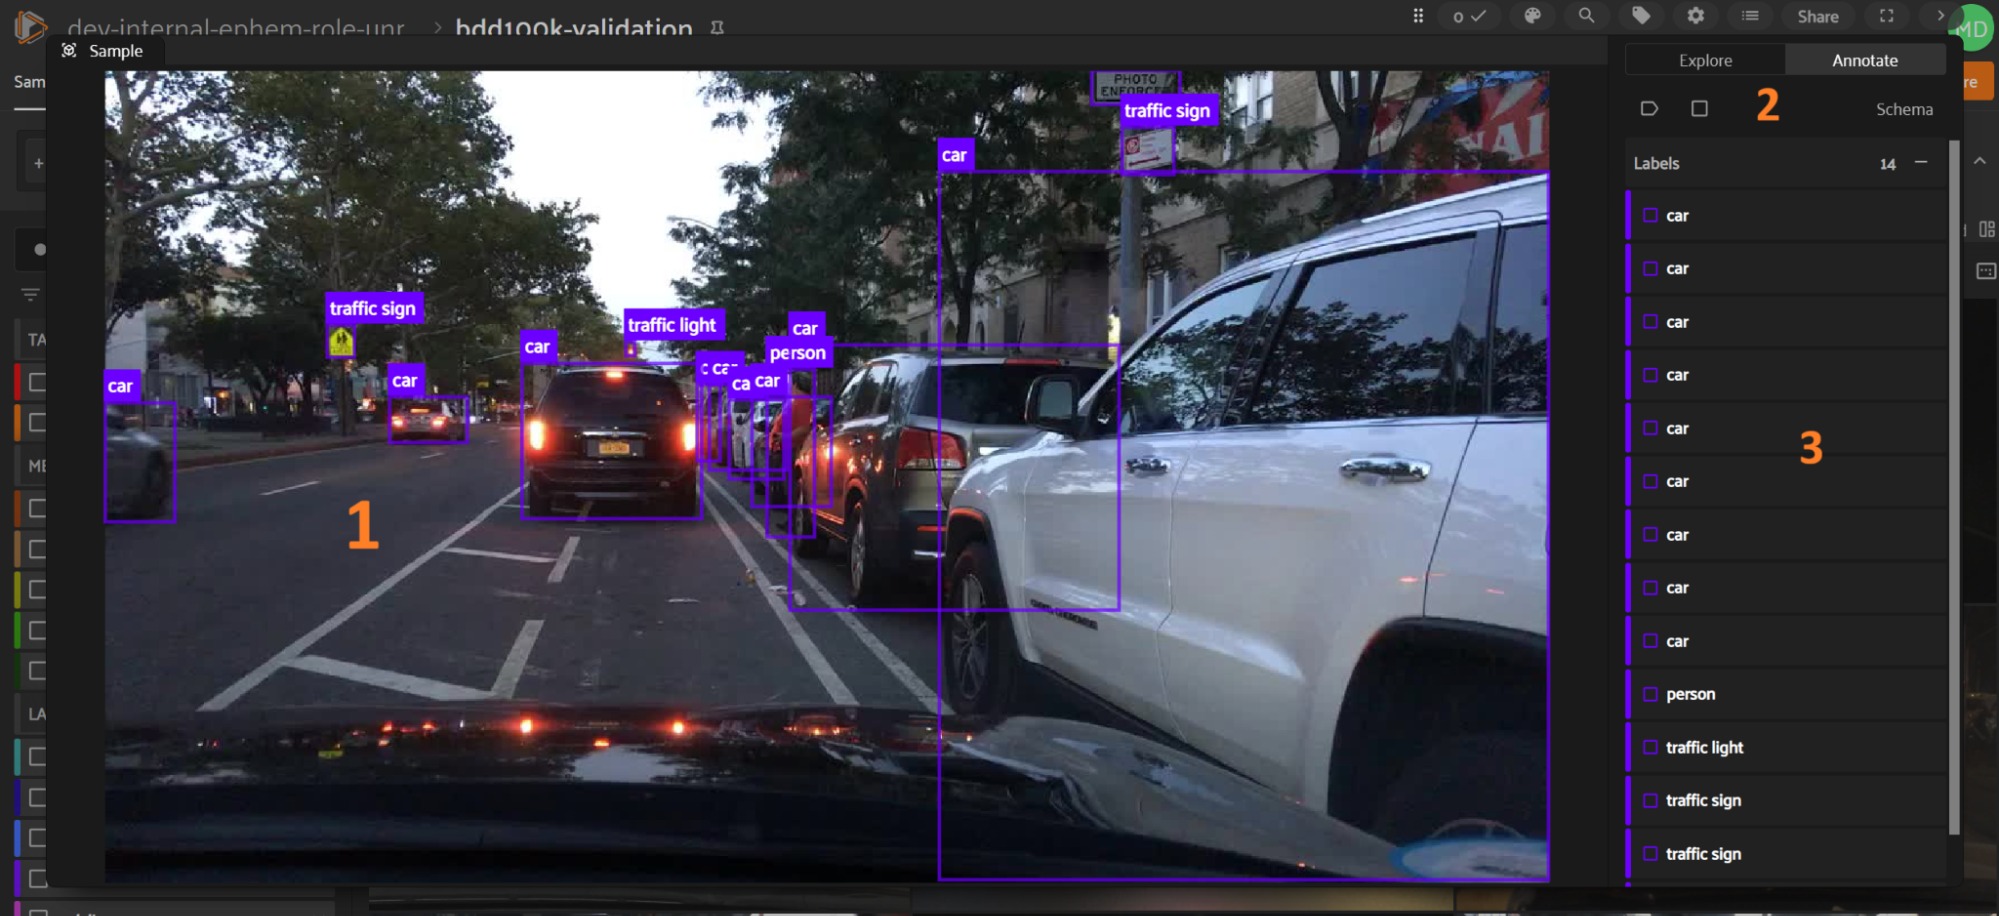
While in the “Annotate” tab, the sample expanded view consists of three parts:
The “Annotation Canvas”
Annotation actions toolbar
List of label instances
Annotation Canvas#
The Annotation Canvas is where you visualize your sample and interact directly with label instances using mouse and keyboard actions. We refer to the Annotation Canvas below when describing 3D and 2D label creations and edits in more detail.
You can edit an existing label instance by clicking on that label instance on the Annotation Canvas.
Annotation Actions Toolbar#
The annotation actions toolbar is where you can create a new label instance or (if you are a user with “Can manage” access on the dataset; see above) access the Schema Manager and Annotation Schema.
List of Label Instances#
Under the “Labels” header, you’ll see a flattened list of all label instances in the fields checked in the sidebar. You can edit an existing label instance by clicking on that label instance within the “Labels” list.
Hidden labels, and labels on fields that the sample’s tiles hide, are left out of the list until you show them again.
For label types with spatial properties (e.g., 2D bounding boxes), you’ll notice a visual indicator highlighting label instances in both the Annotation Canvas and “Labels” list as you hover over either part of the user interface.
List of Primitives#
Labels are not the only type of metadata available for edits in FiftyOne’s in-App annotation functionality. Primitive fields (e.g., StringFields or IntFields) on the dataset may also be made available in the Annotation Schema via the Schema Manager interface. When primitives exist in the Annotation Schema, you’ll see a flattened list of all such fields under the “Primitives” header.
How to: 2D Label Annotation#
Label faster with AI
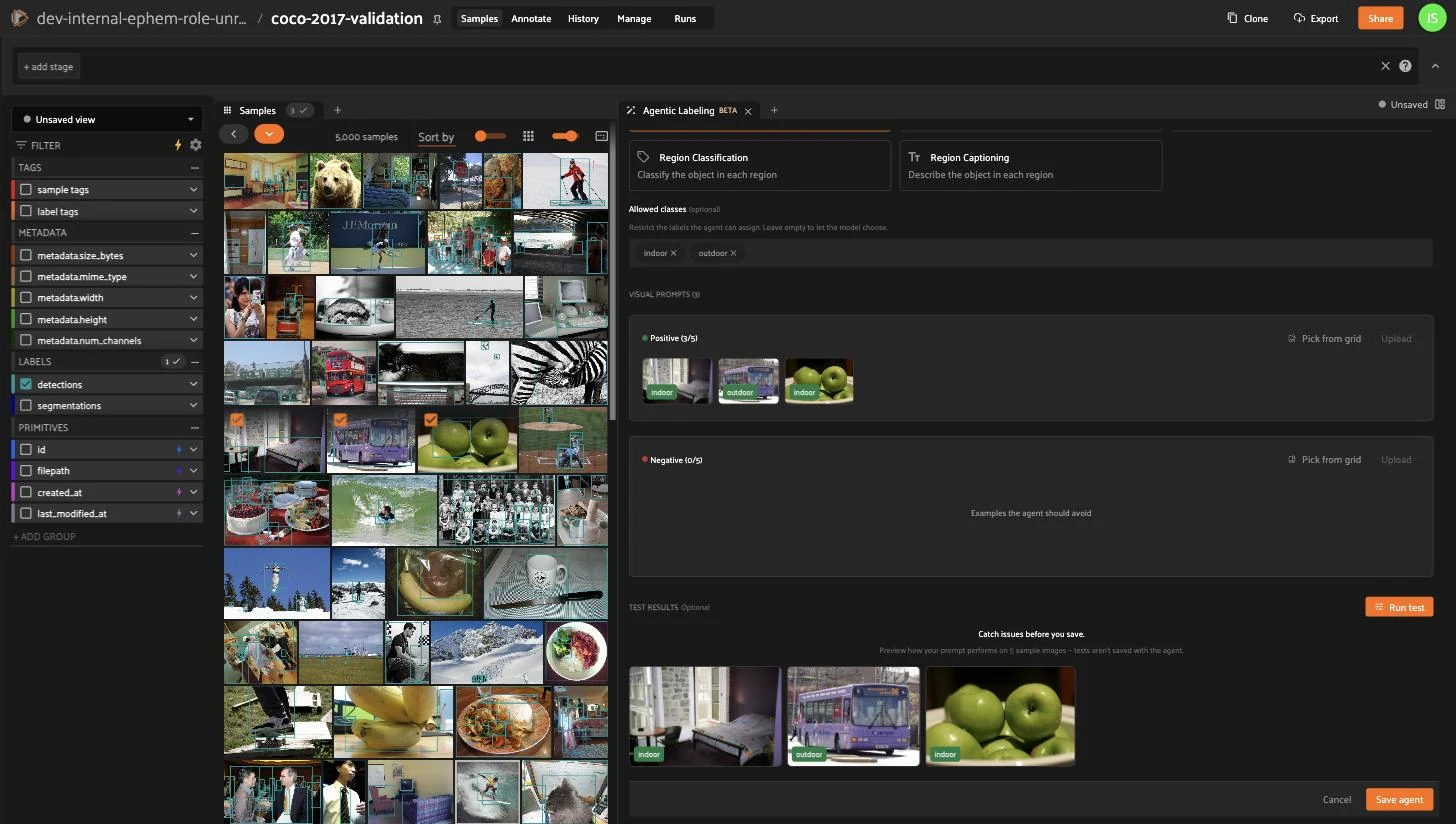
FiftyOne can help you label images with AI: prompt masks with AI-assisted segmentation, or auto-label a whole dataset from a few examples with Agentic Labeling.
Creating a Classification label#
Click the “Create new classification” icon in the annotation actions toolbar to display the classification editor in the right sidebar. A field and label are required to save the new classification label. Only fields available in your schema will be displayed as options in the dropdown boxes.
Creating a Detection label#
Click the “Create new detection” icon in the annotation actions toolbar to enable the crosshair mouse cursor on the Annotation Canvas and display the detection editor in the right sidebar. Position the cursor at one corner of the new detection, then click and hold the mouse button while dragging diagonally to create a bounding box.
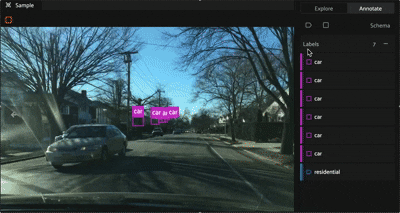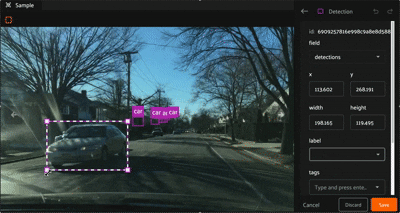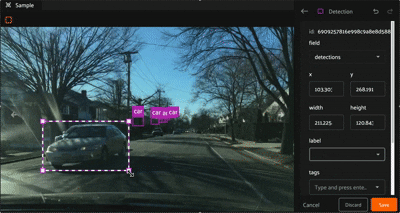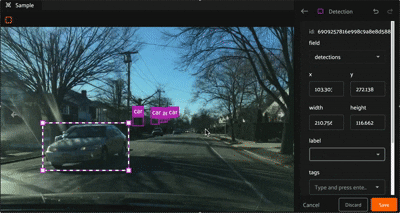
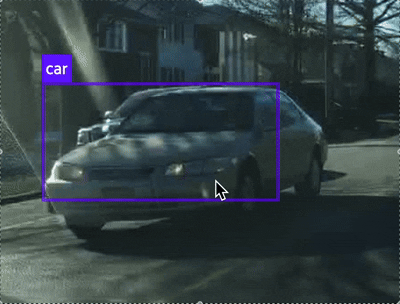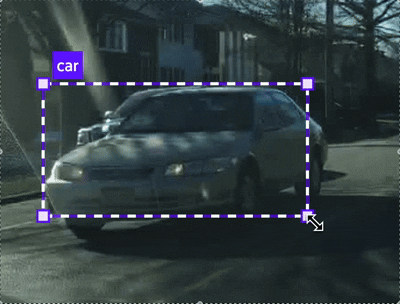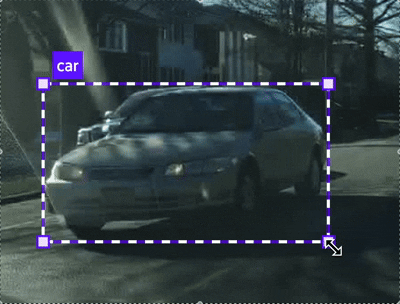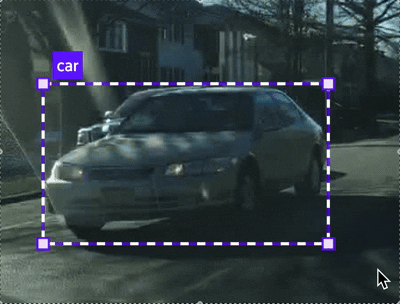
Once a bounding box has been created, it can be resized and repositioned as desired by clicking and holding any edge or corner drag handle while moving the mouse cursor. For finer adjustments, first zoom in on the image. To maintain the aspect ratio of the selection, hold down the shift key while dragging.
A field and label are required to save the new detection label. Only fields available in your schema will be displayed as options in the dropdown boxes.
A detection label’s size and shape can be adjusted directly in the annotation canvas by clicking on the detection to select it, then dragging an edge or corner drag handle:
Creating a Segmentation label#
Prompt masks with AI
Rather than painting a mask by hand, you can prompt one with a model using the AI assistance tool — see AI-assisted image segmentation.
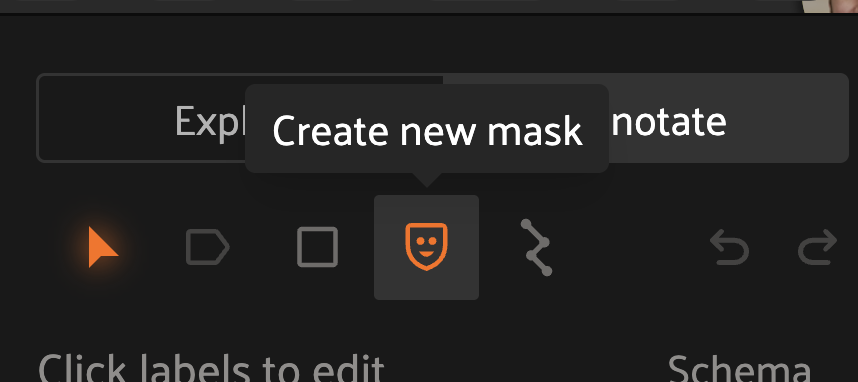
Click the “Create new mask” icon in the annotation actions toolbar to enable the mask annotation toolbar displayed on the left side of the Annotation Canvas. Select the paintbrush, polyline, or AI tool to begin drawing masks.
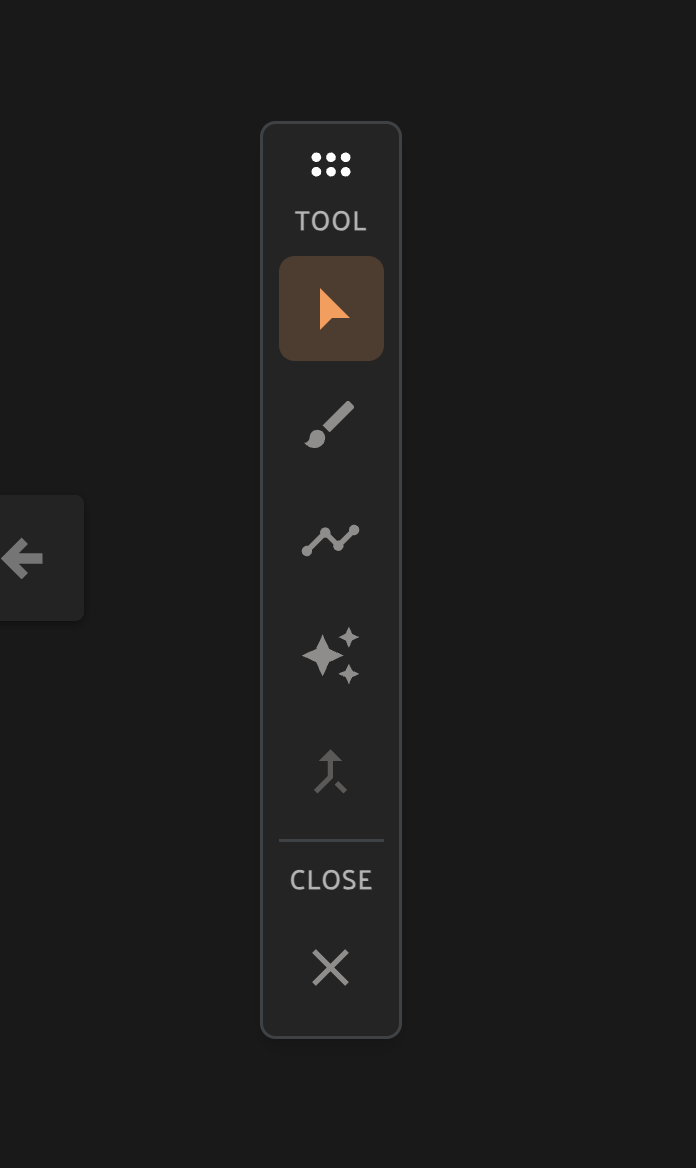
When drawing segmentation masks, the mask toolbar is shown on the left of the Annotation Canvas. From top to bottom of the image above, the icons depict the Selection tool to select specific label instances, the Brush tool, Polygon tool, or AI assistance tool for drawing new masks, the Merge tool to combine mask instances, and Close to stop editing the current label instance.
A field and label are required to save new mask labels. Only fields available in your schema will be displayed as options in the dropdown boxes. Instance segmentations fall under the Detections label field type, allowing for detection labels either with or without masks.
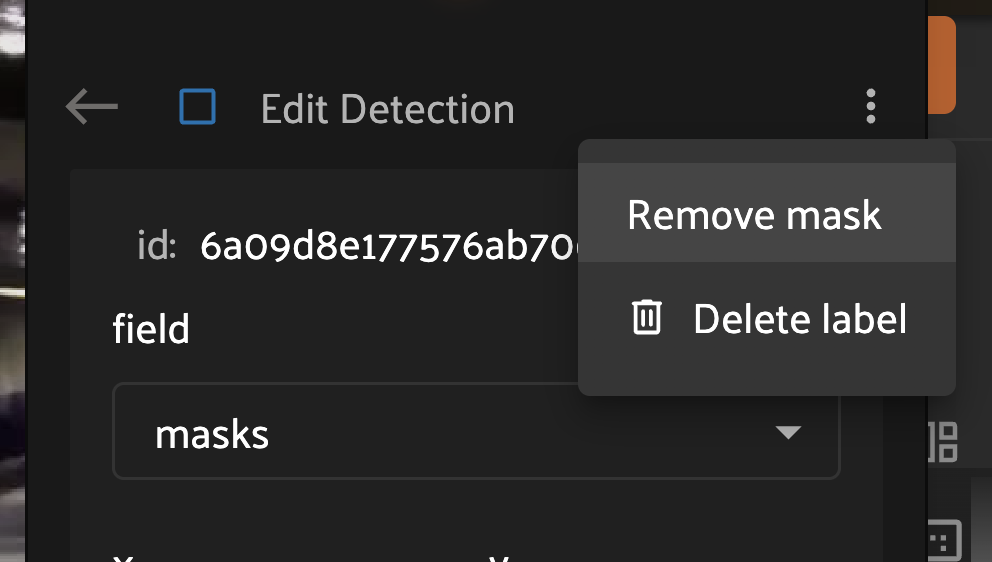
The kebab menu on an existing detection label in the right sidebar allows you to either add or remove the mask from that label instance.
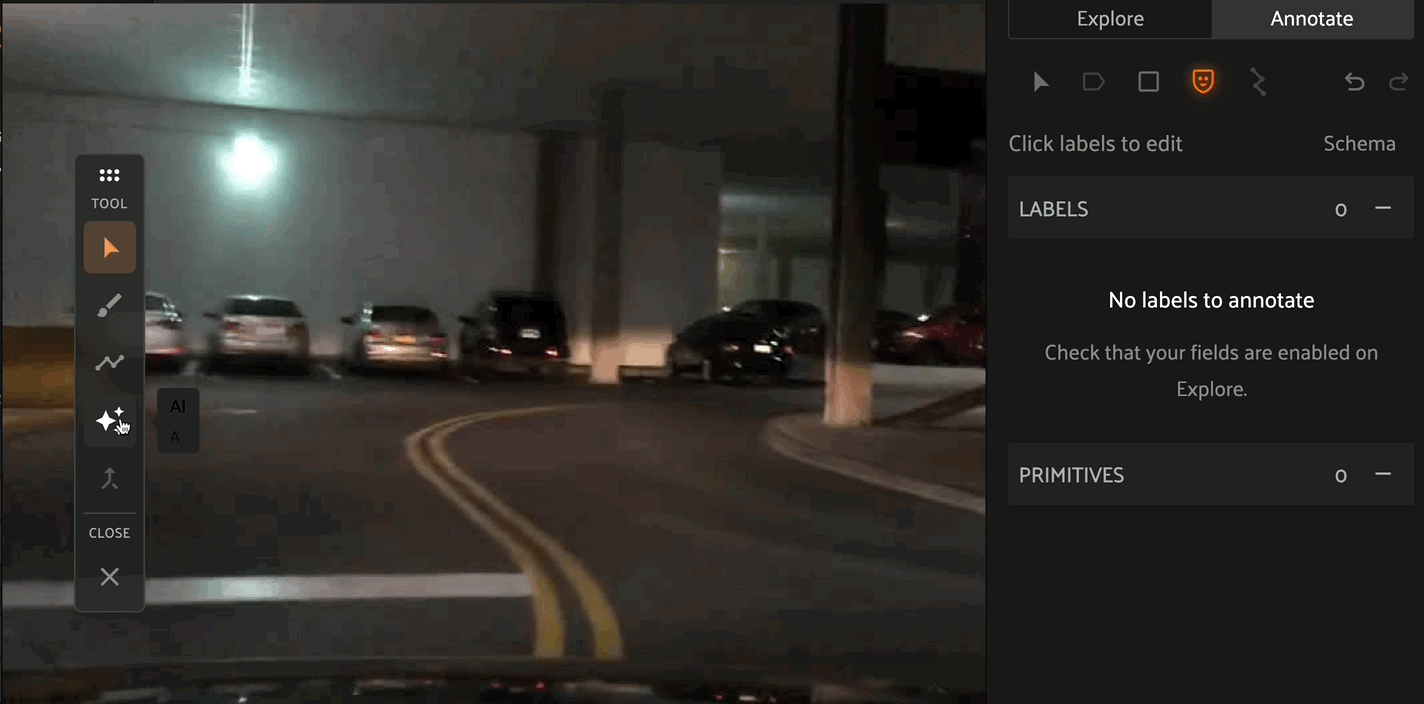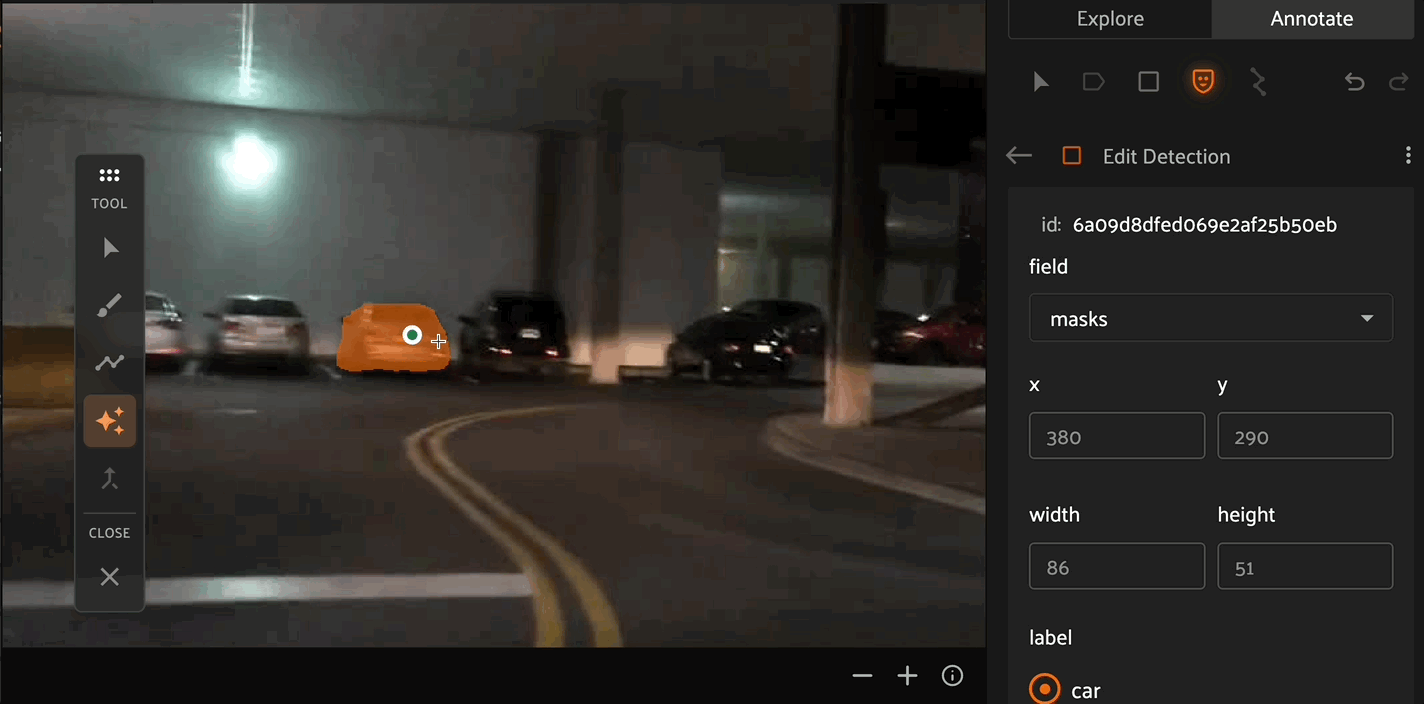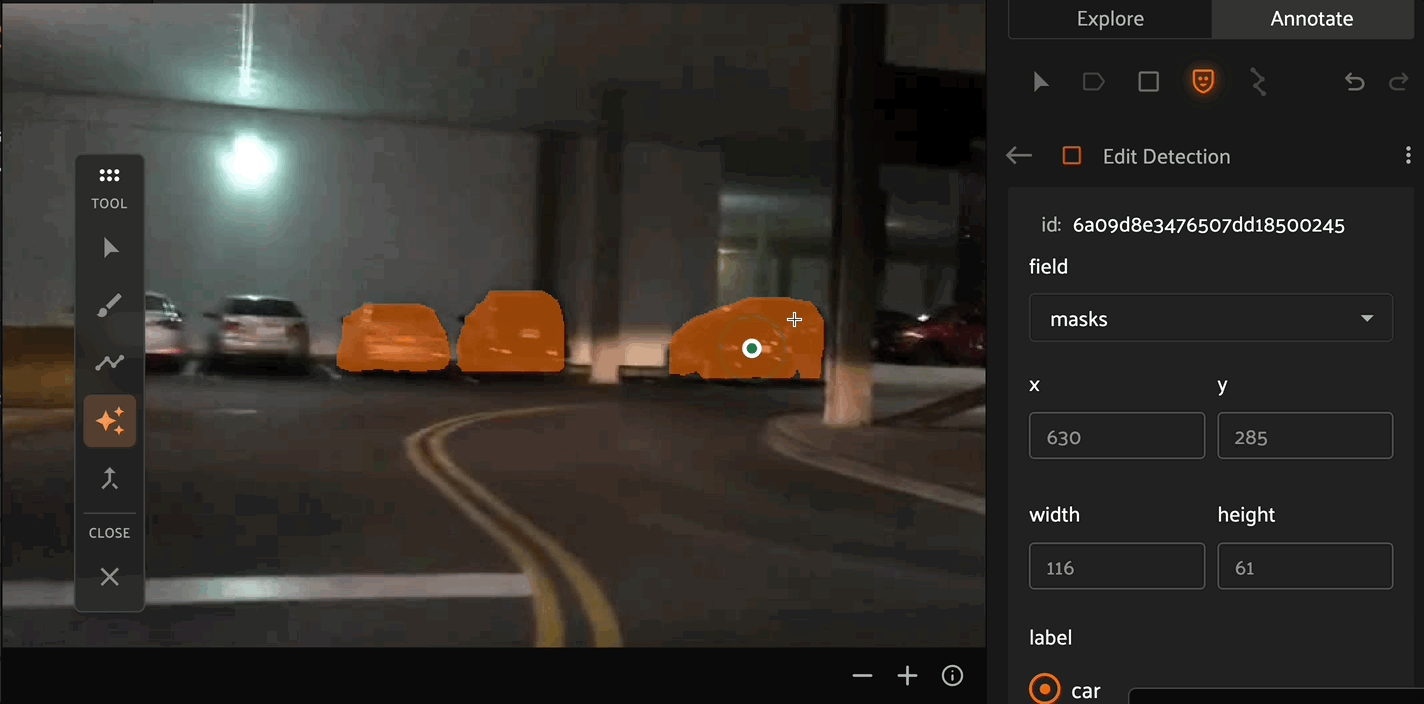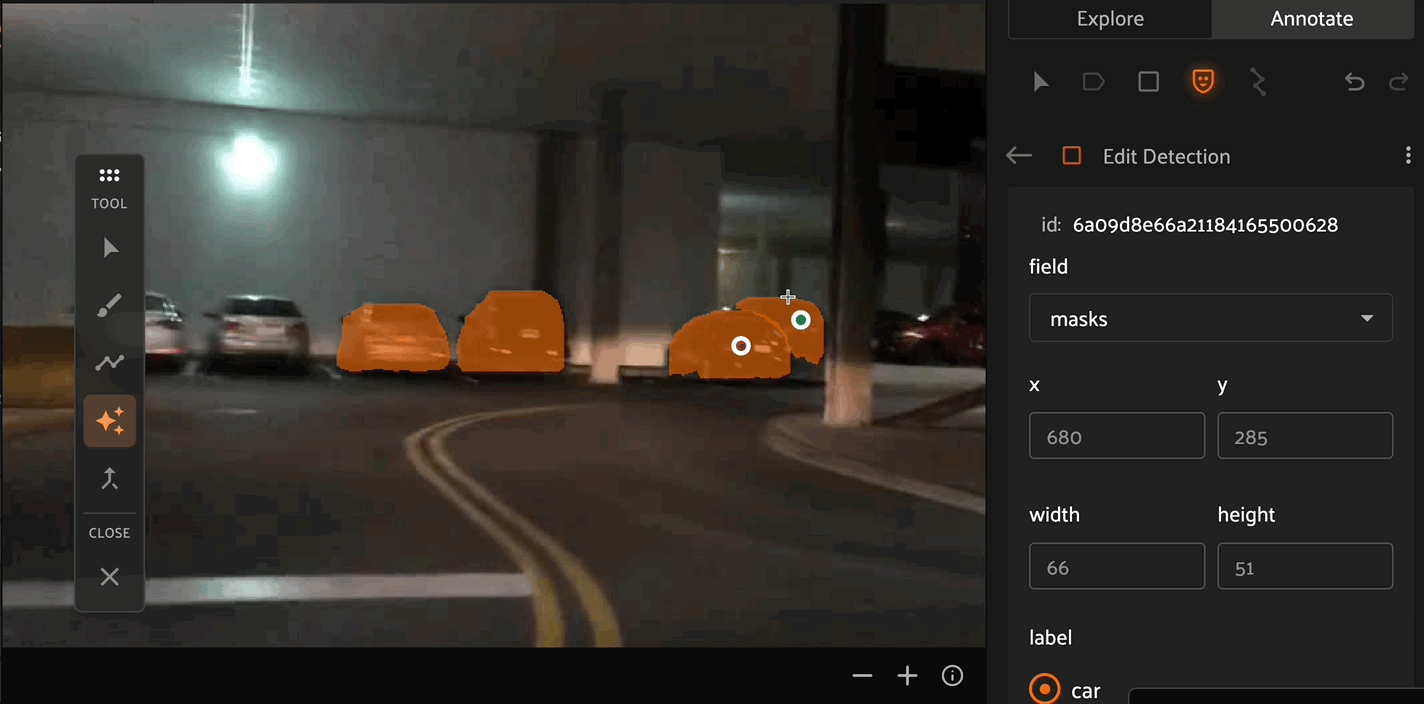
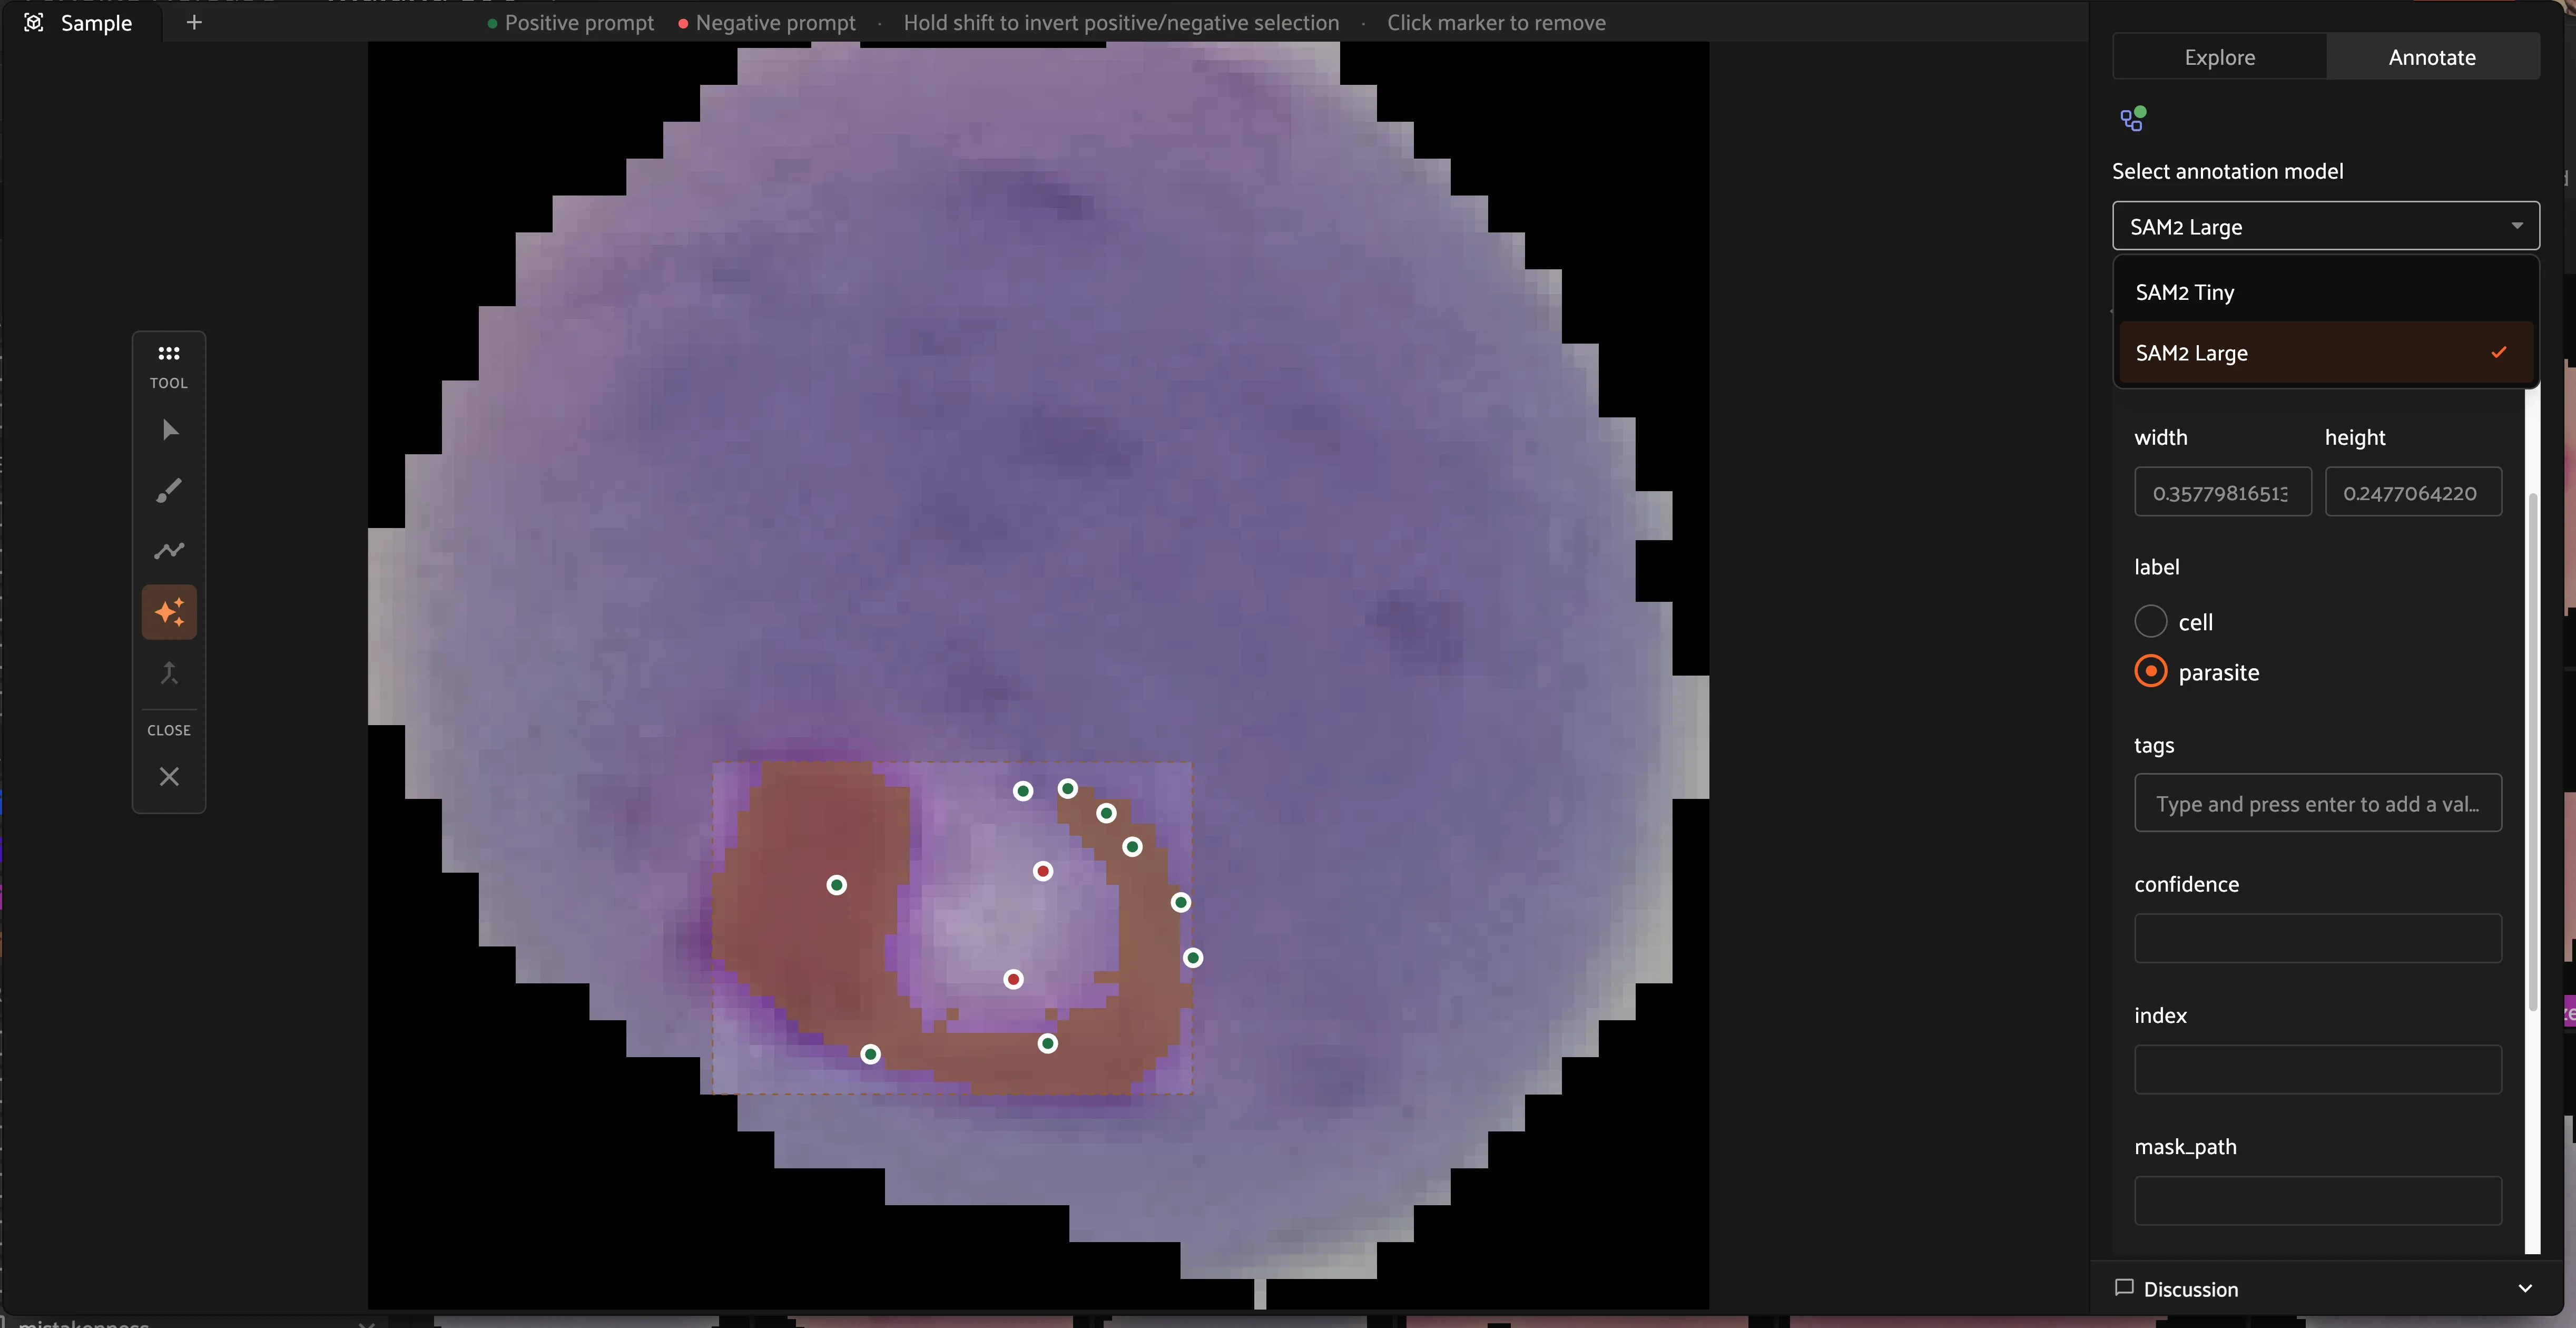
The AI assistance tool allows you to use mask segmentation models to draw masks. This tool allows you to click any number of positive and negative points per object as prompts to the model to refine the mask boundaries. For Voxel51 customers, ask your Voxel51 Customer Success representative about bringing your own finetuned models for AI assisted segmentation.
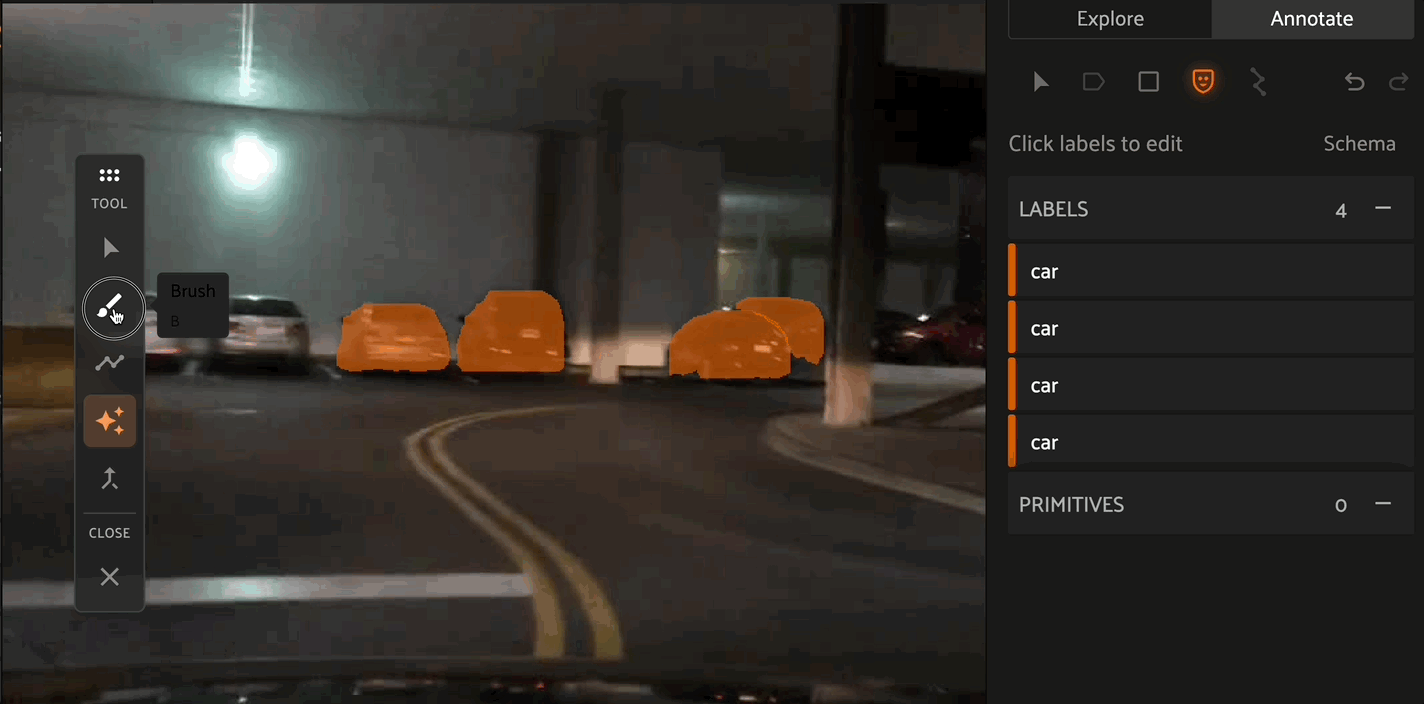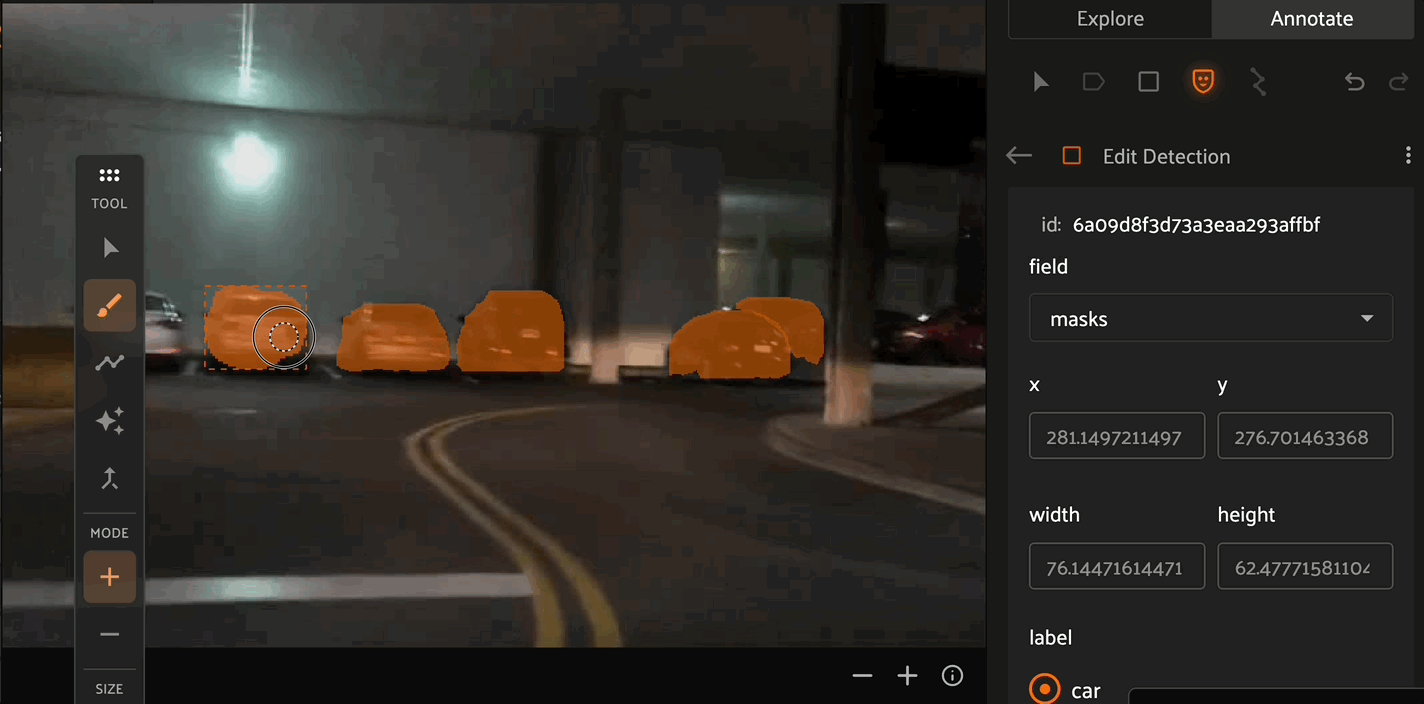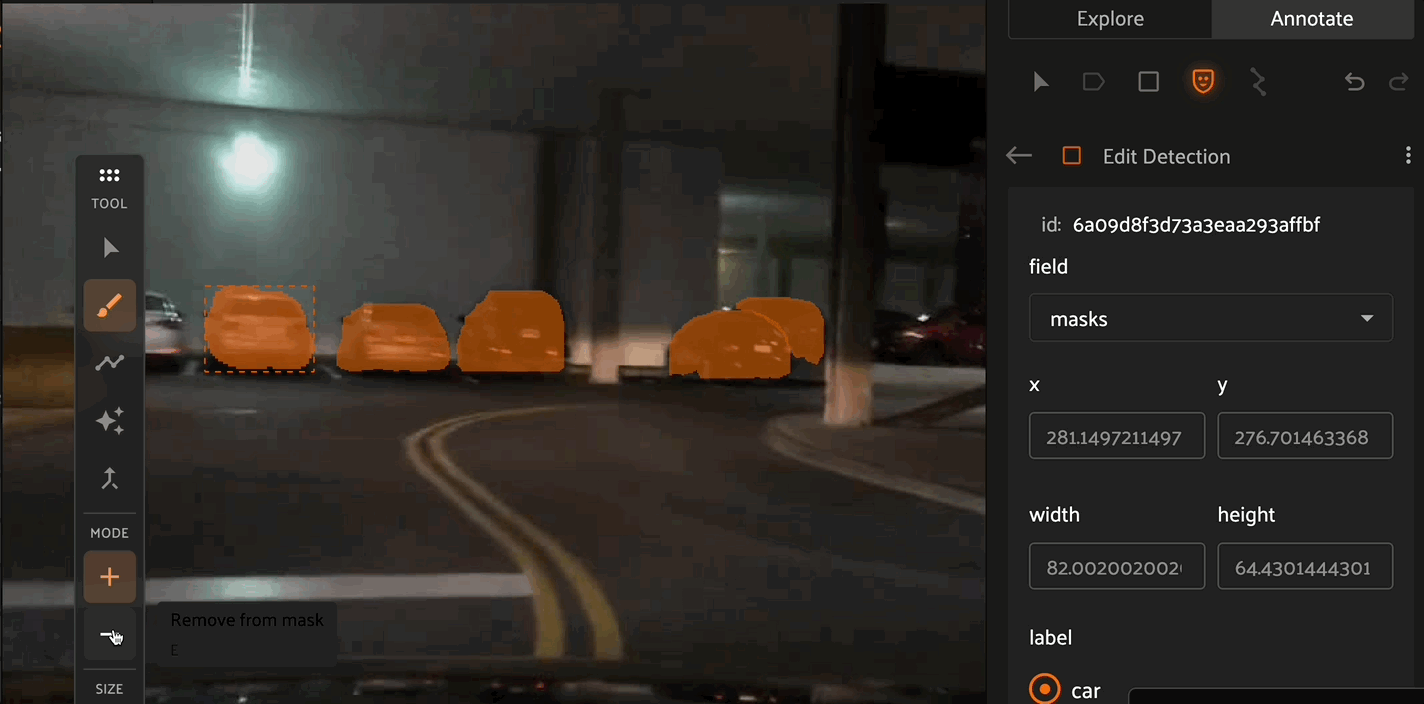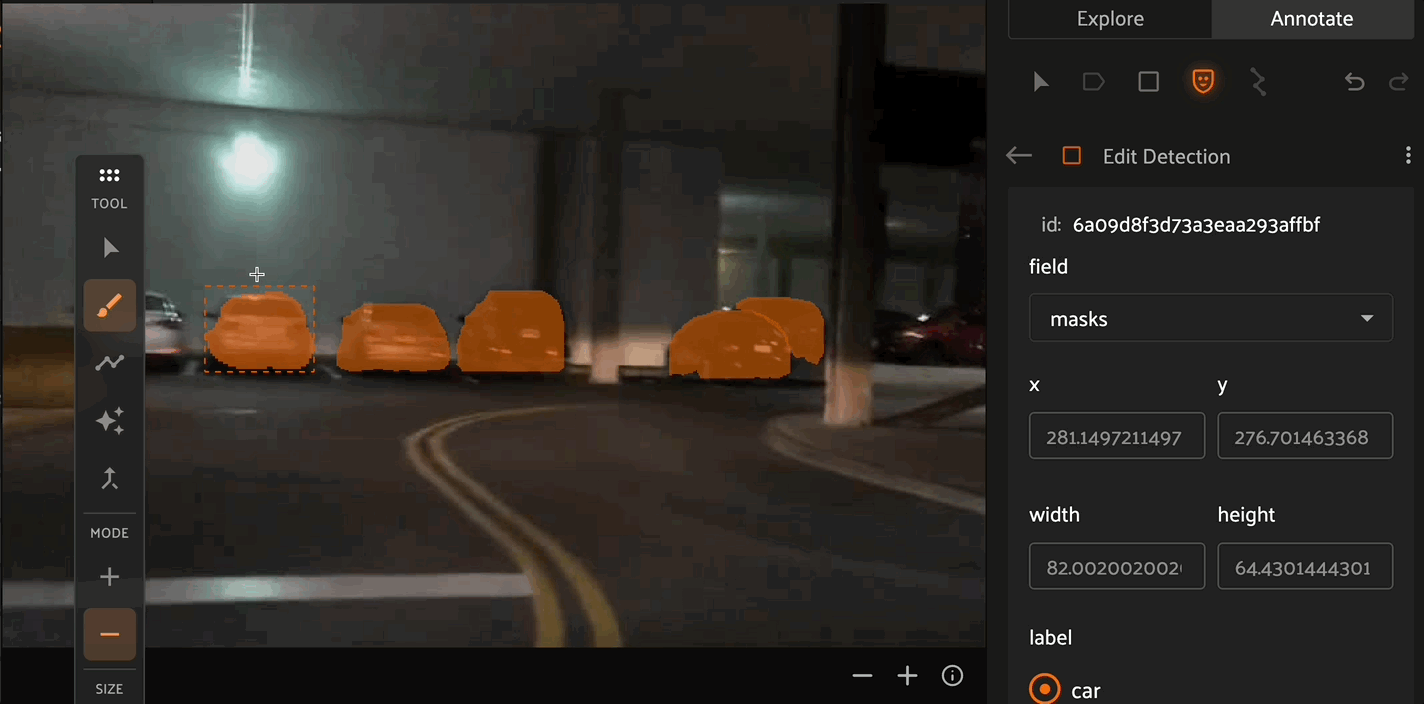
The Brush tool allows for pixel-level precision to create masks. By selecting the - Mode, you can use the brush tool to remove pixels from existing masks. The Brush tool also allows you to configure the size and shape of the brush.
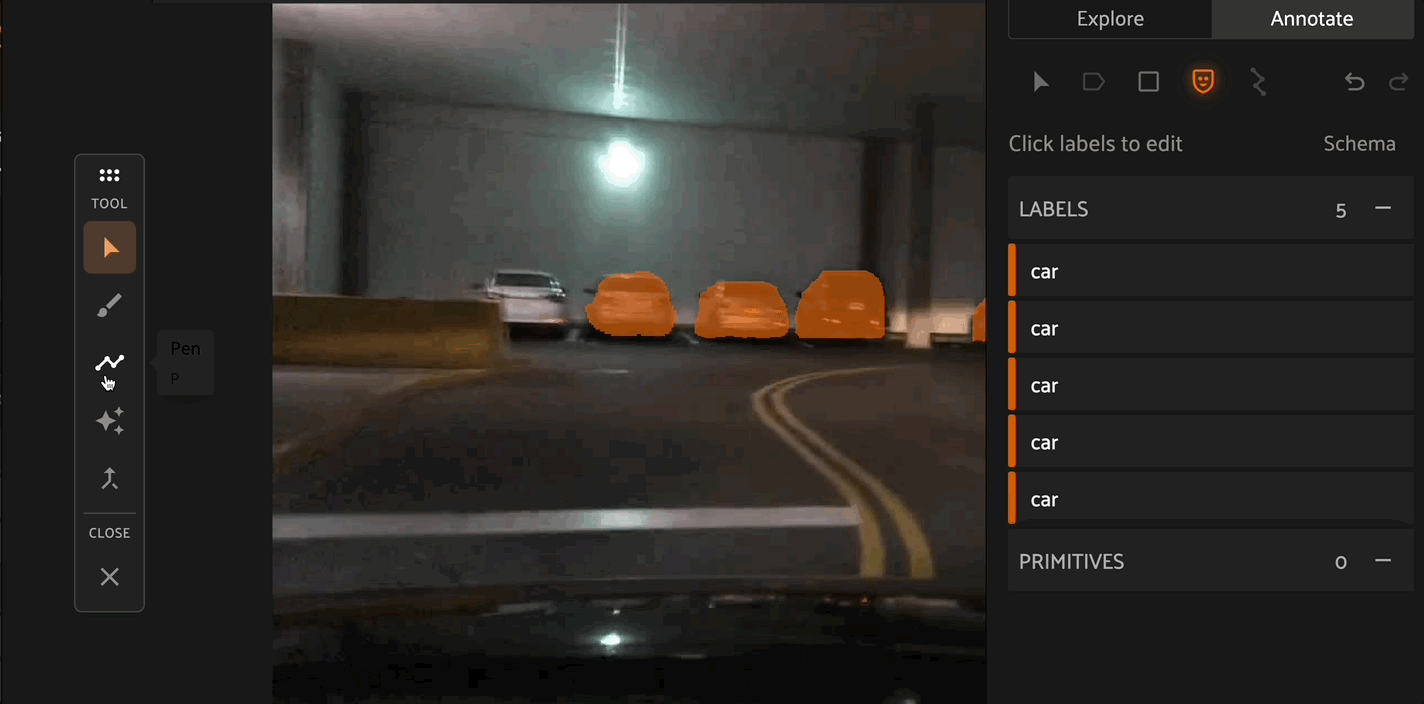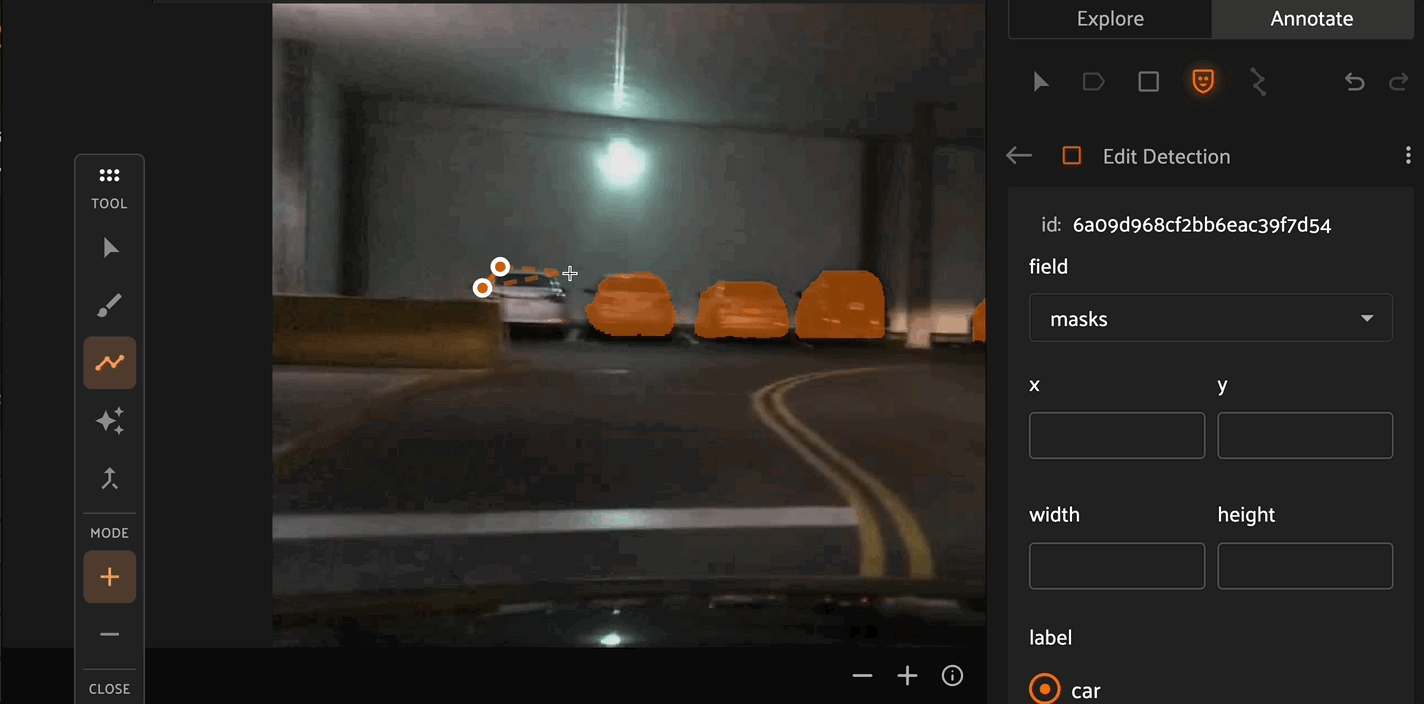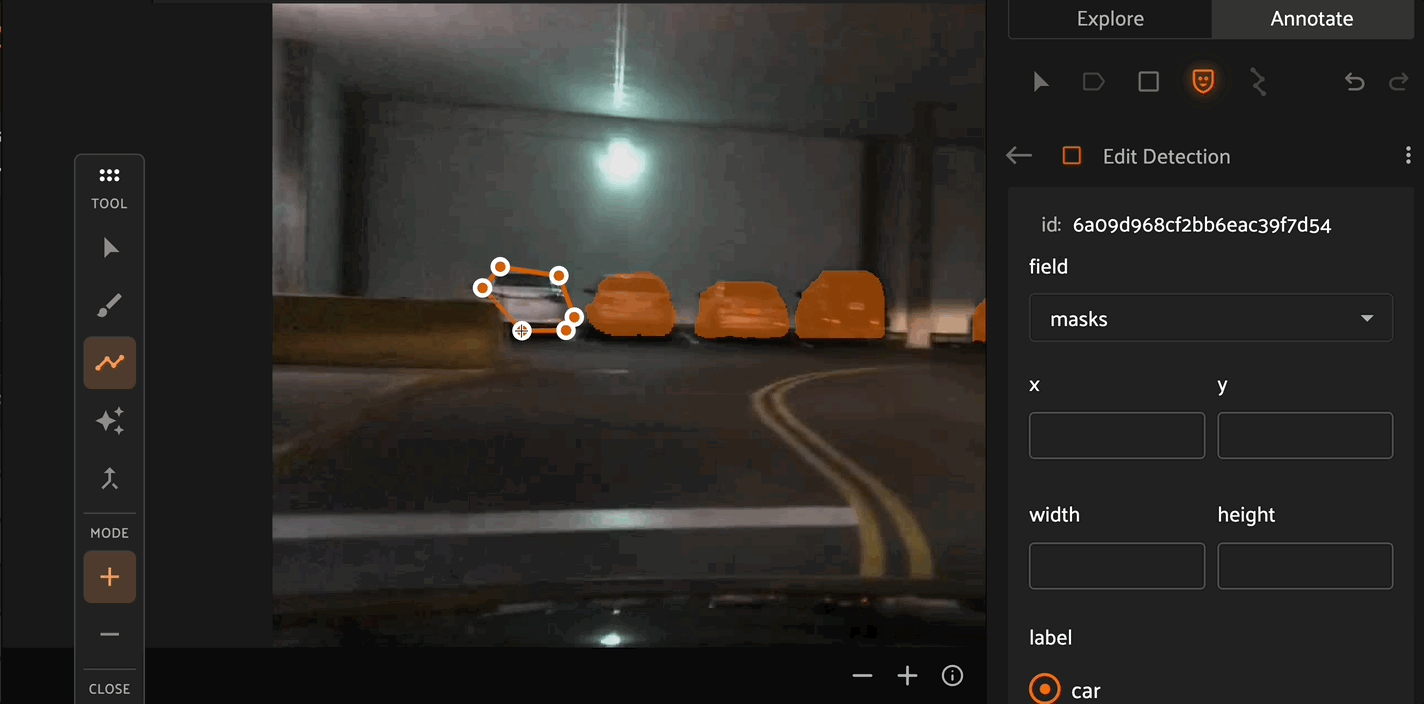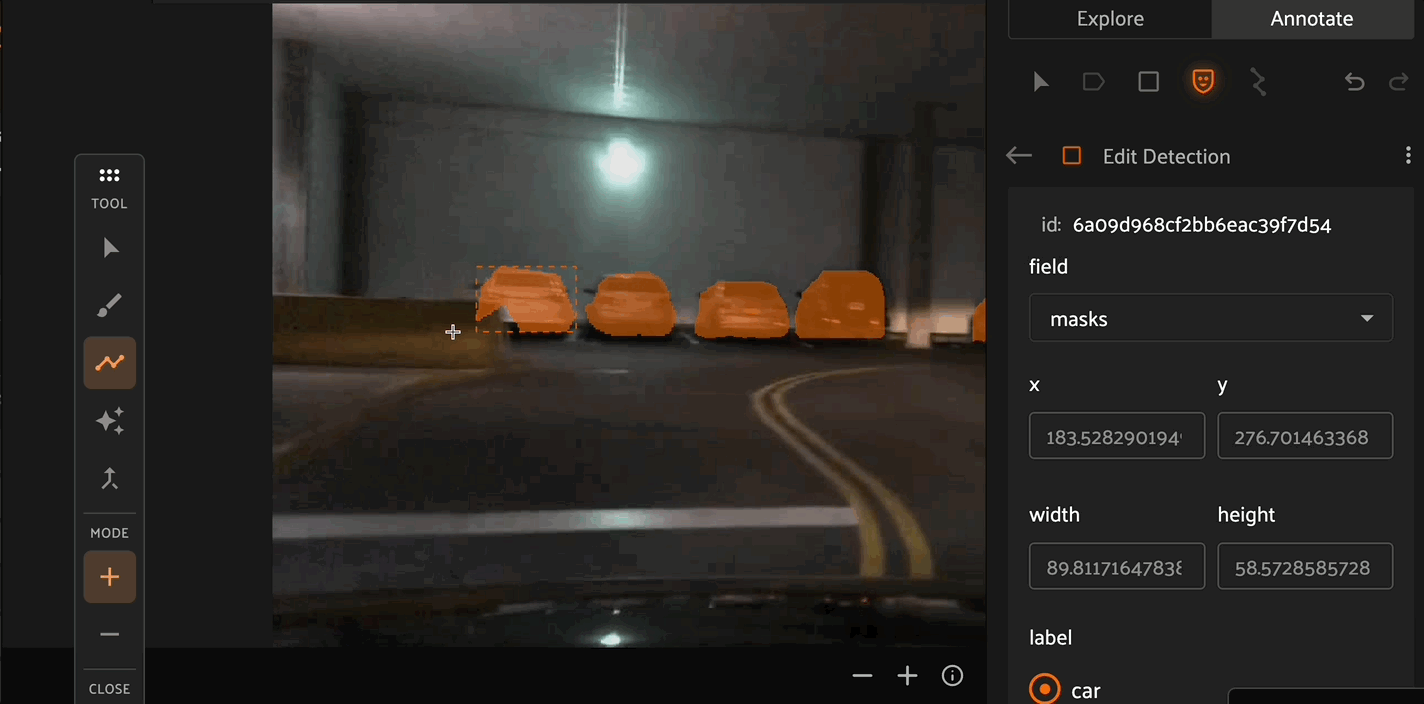
Similar to the brush tool, the Polygon tool allows you to create or remove masks from detection instances. Click the canvas to place points on the polygon, then right click to confirm your selection.
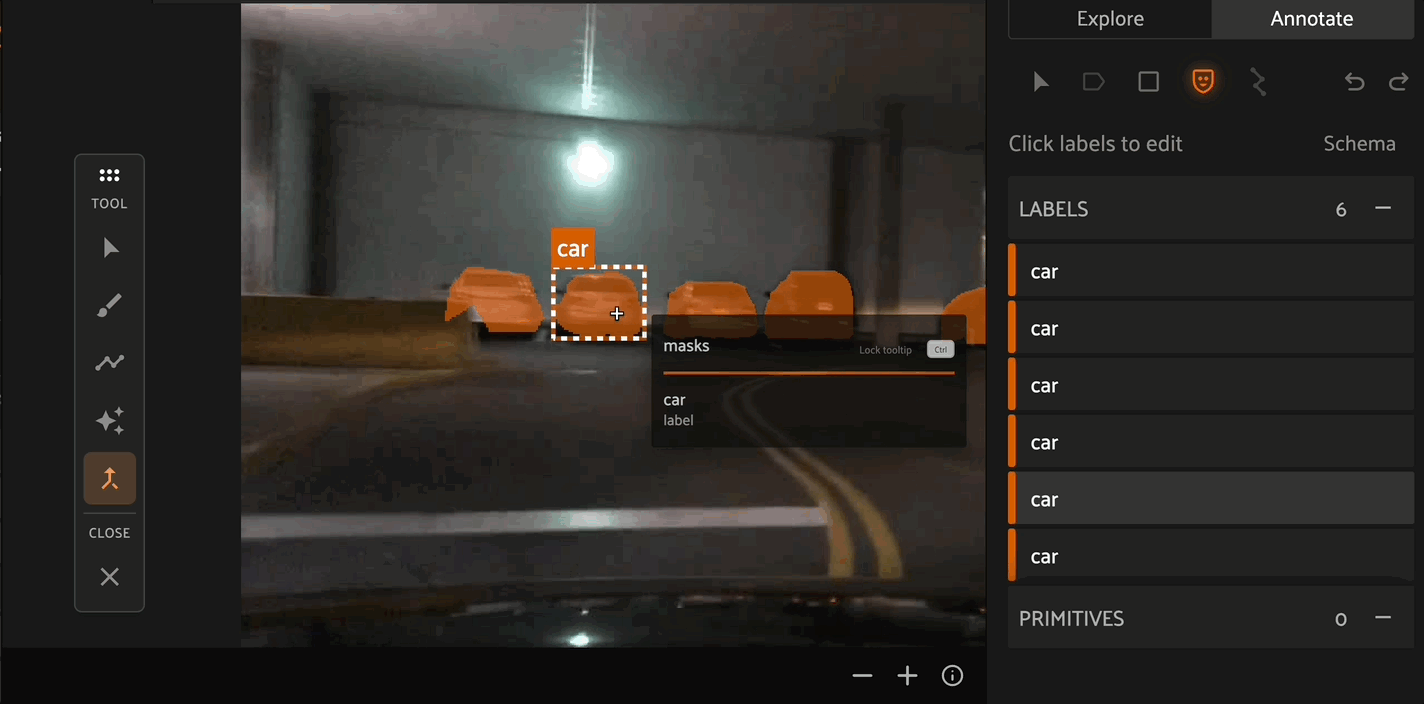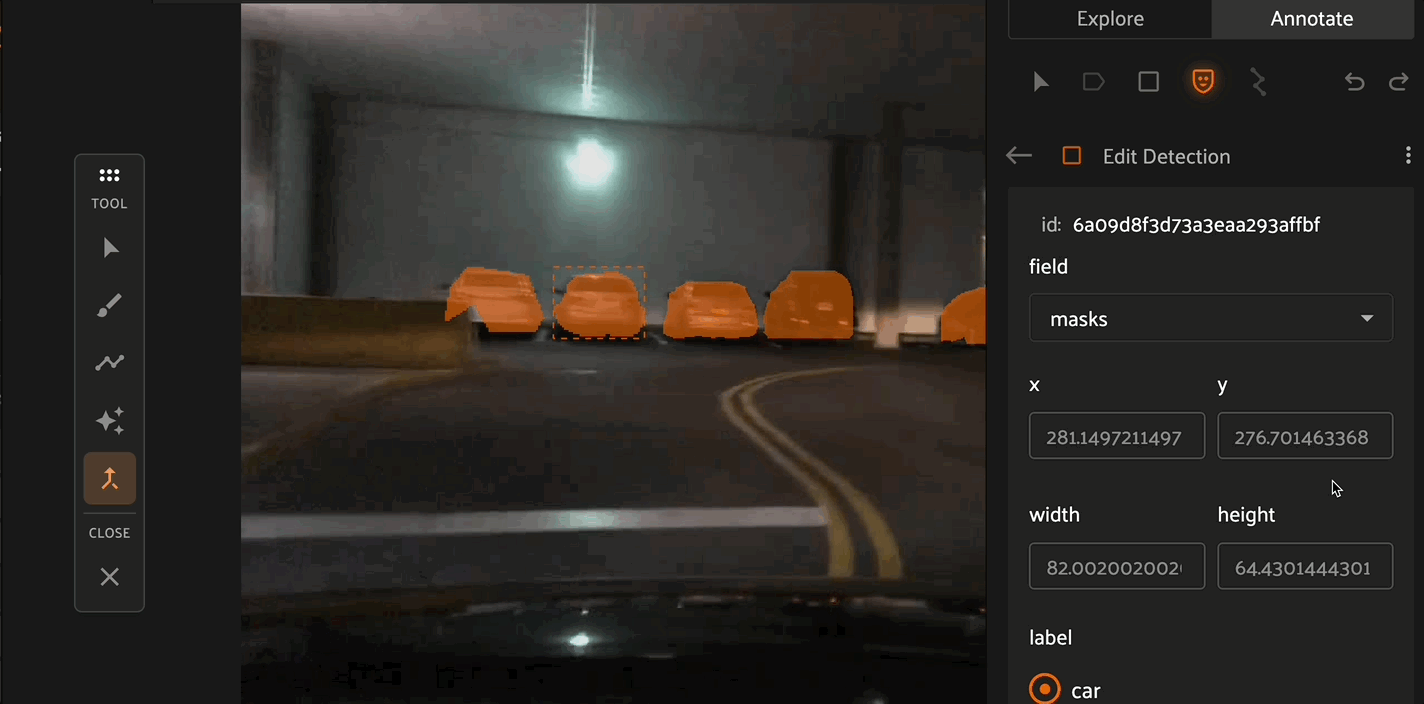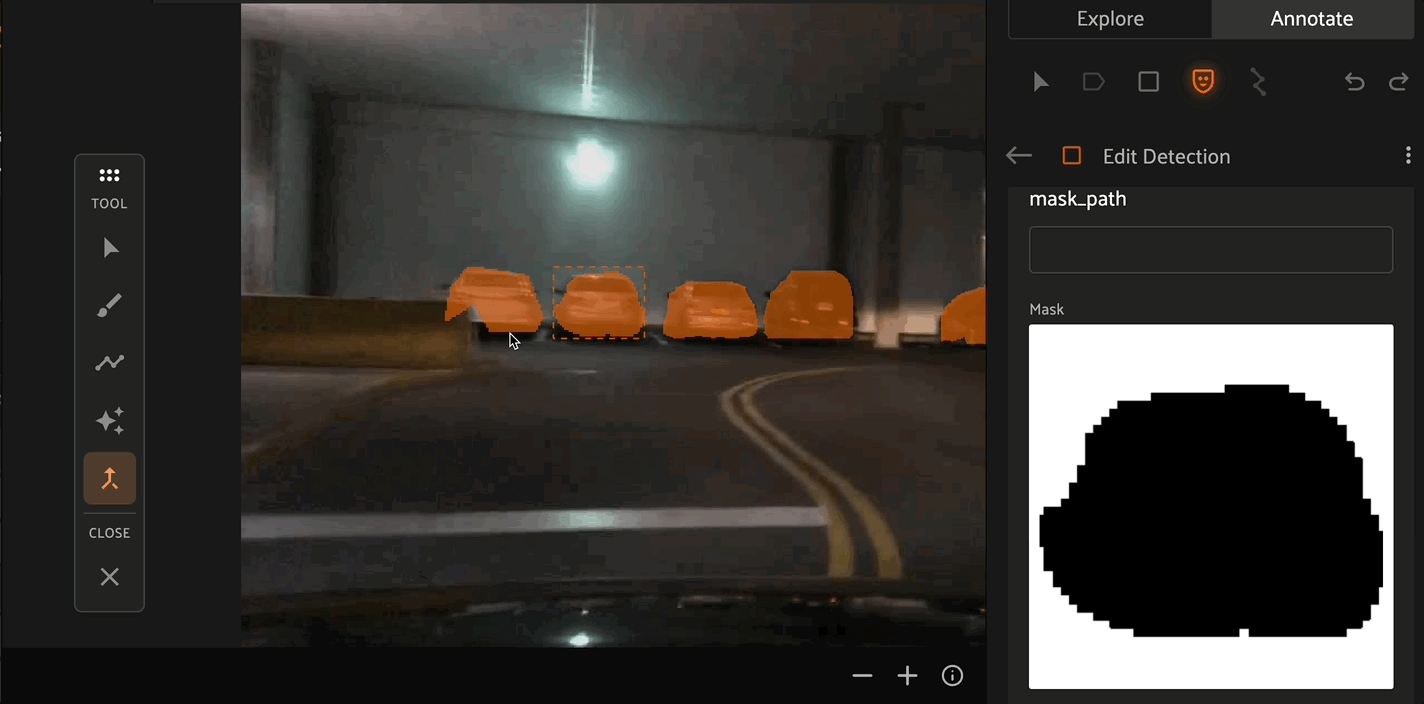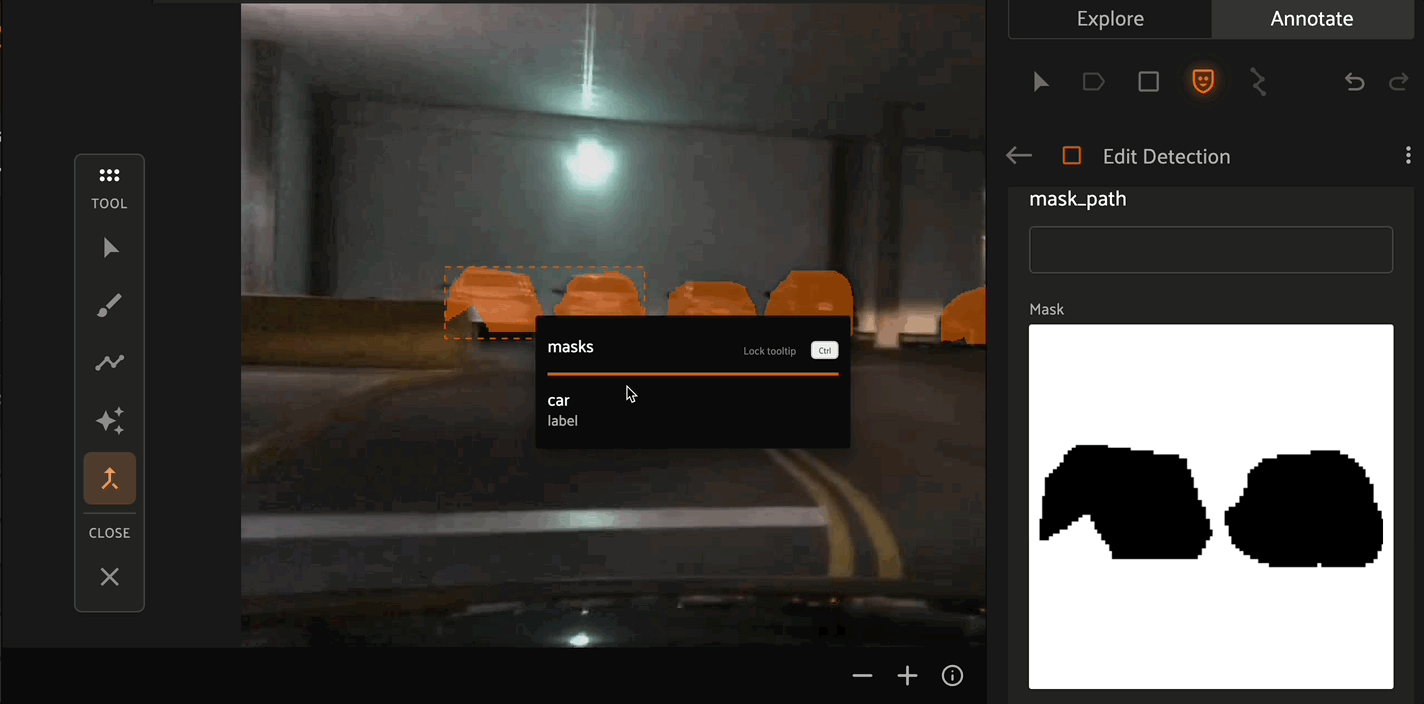
If multiple masks have been created for the same object, the Merge tool allows you to select one object instance and merge the mask of another instance into it.
Creating Polyline and Polygon labels#
Click the “Create new polylines” icon in the annotation actions toolbar to enable the crosshair mouse cursor on the Annotation Canvas and display the polylines editor in the right sidebar.
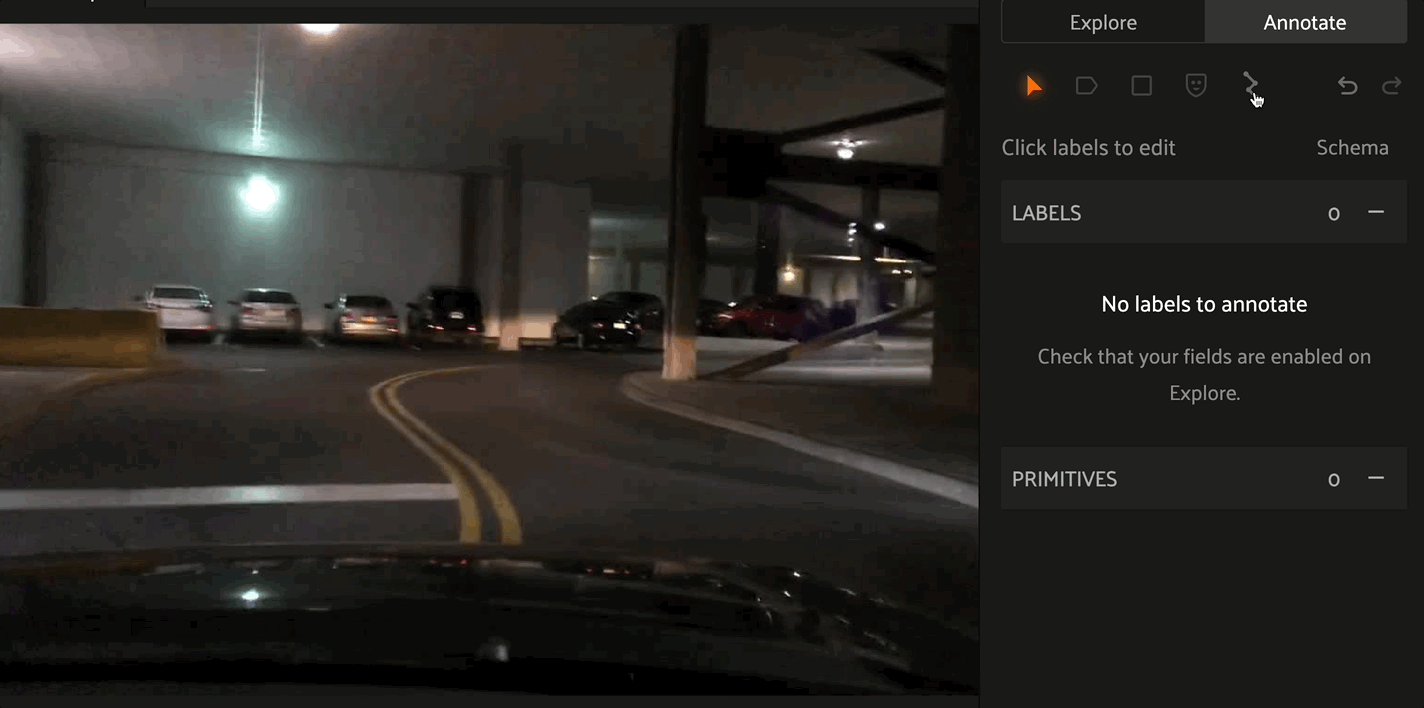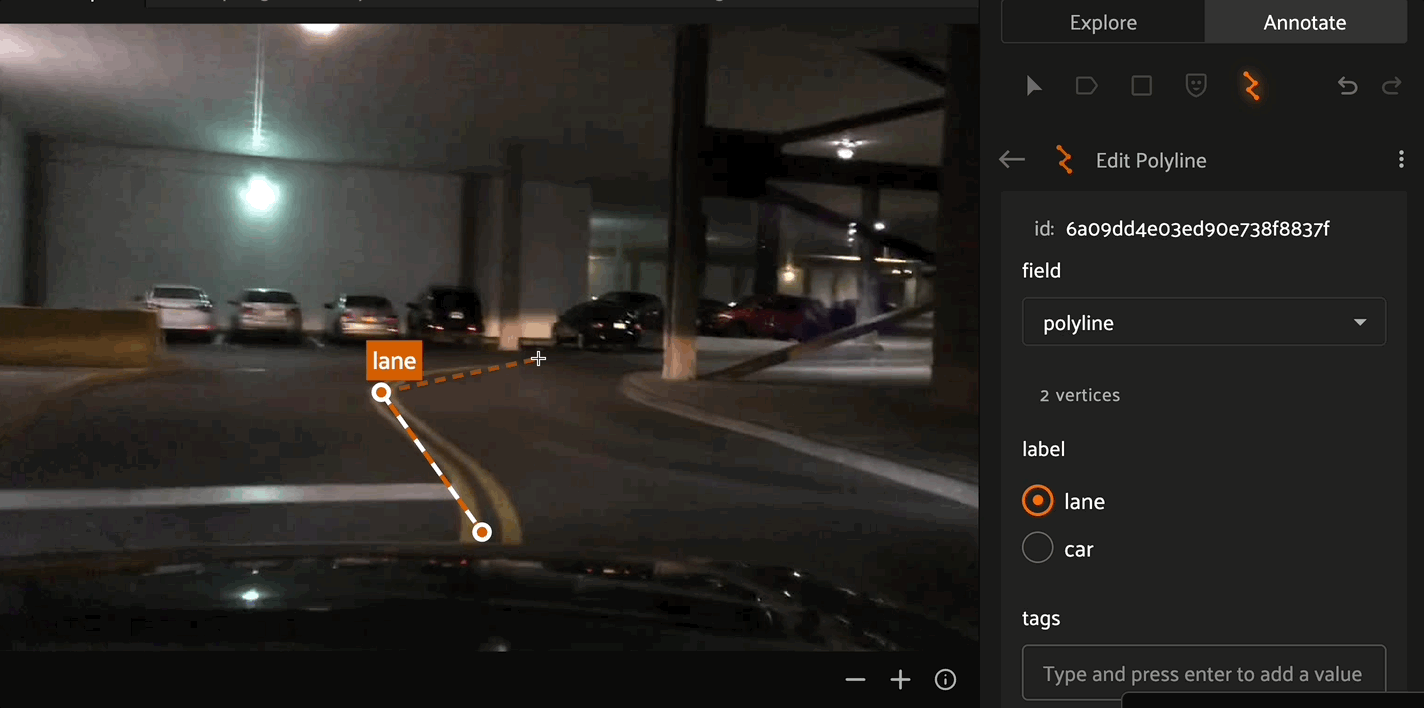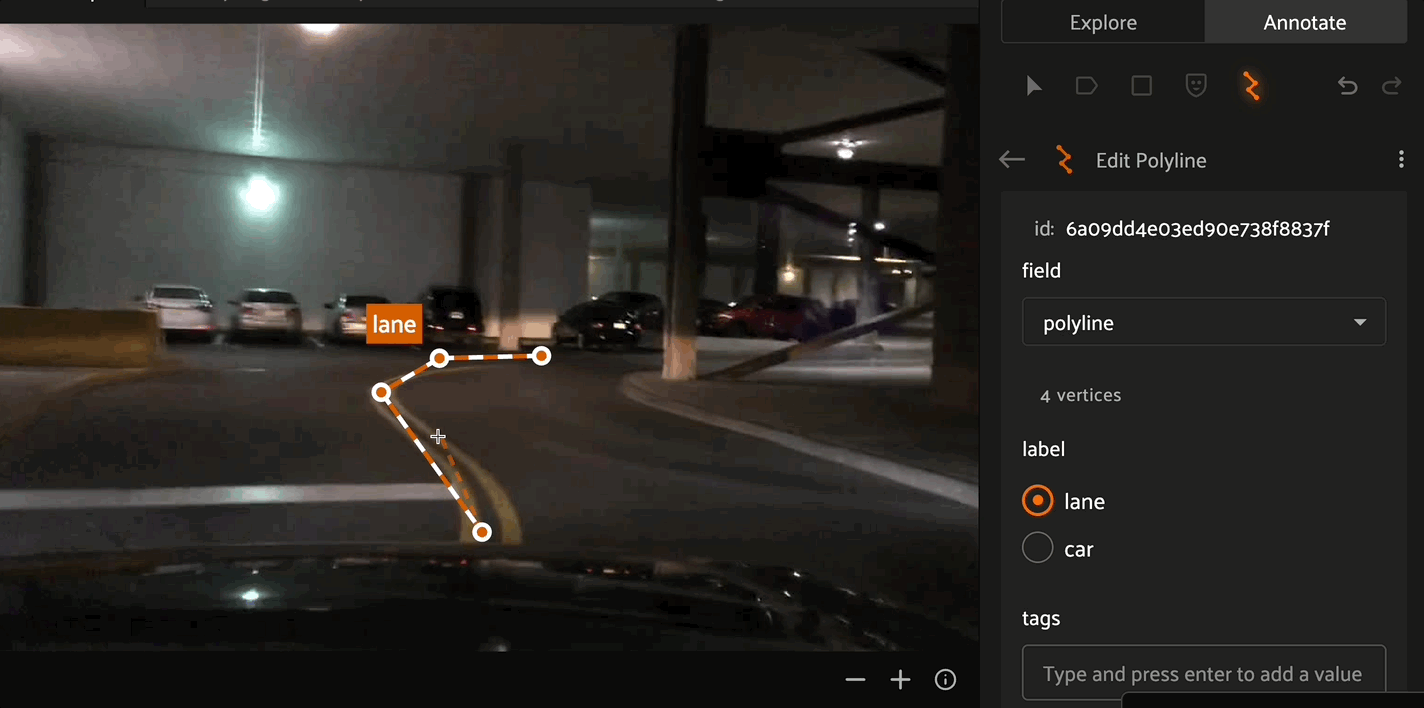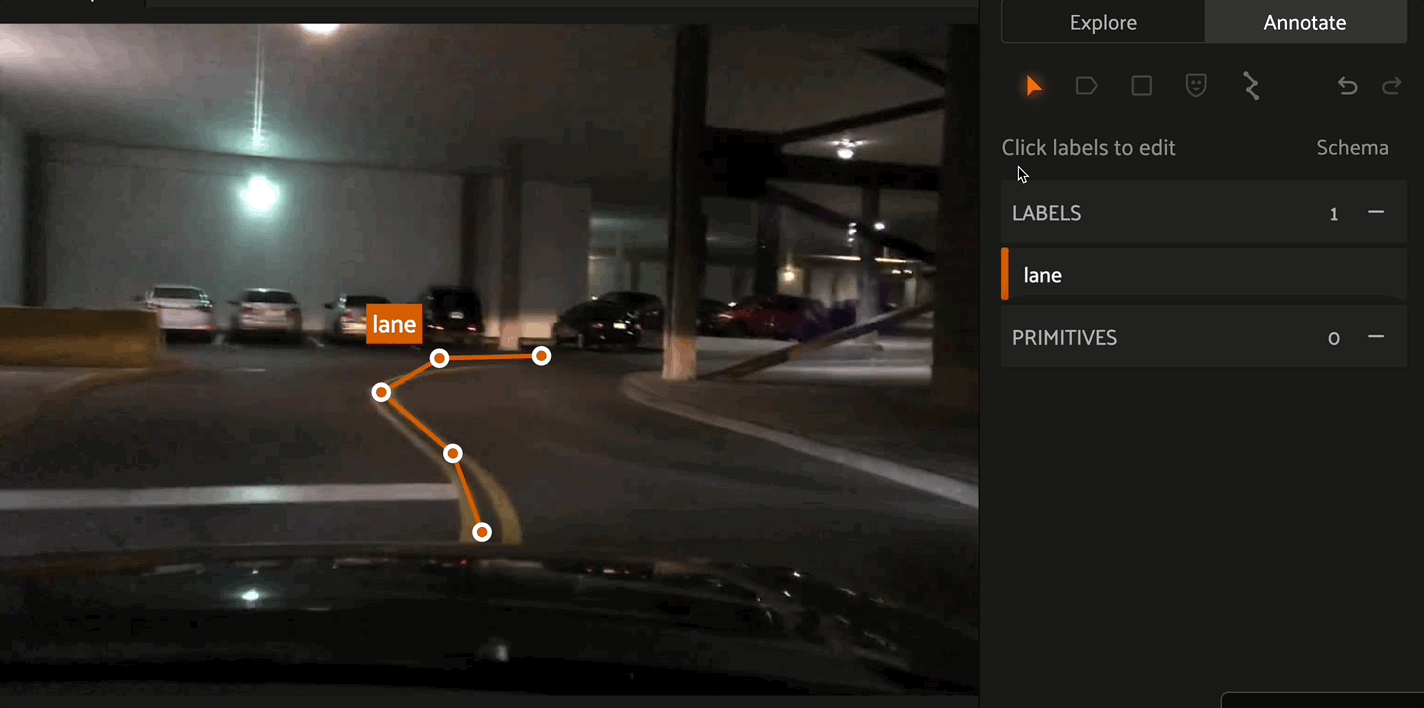
Click the canvas to begin placing vertices of the new polyline, with successive clicks connecting the vertices with line segments. Right click to finish editing the current polyline label instance. To add additional vertices onto an existing polyline, click the polyline segment at the desired location to place the new vertex.
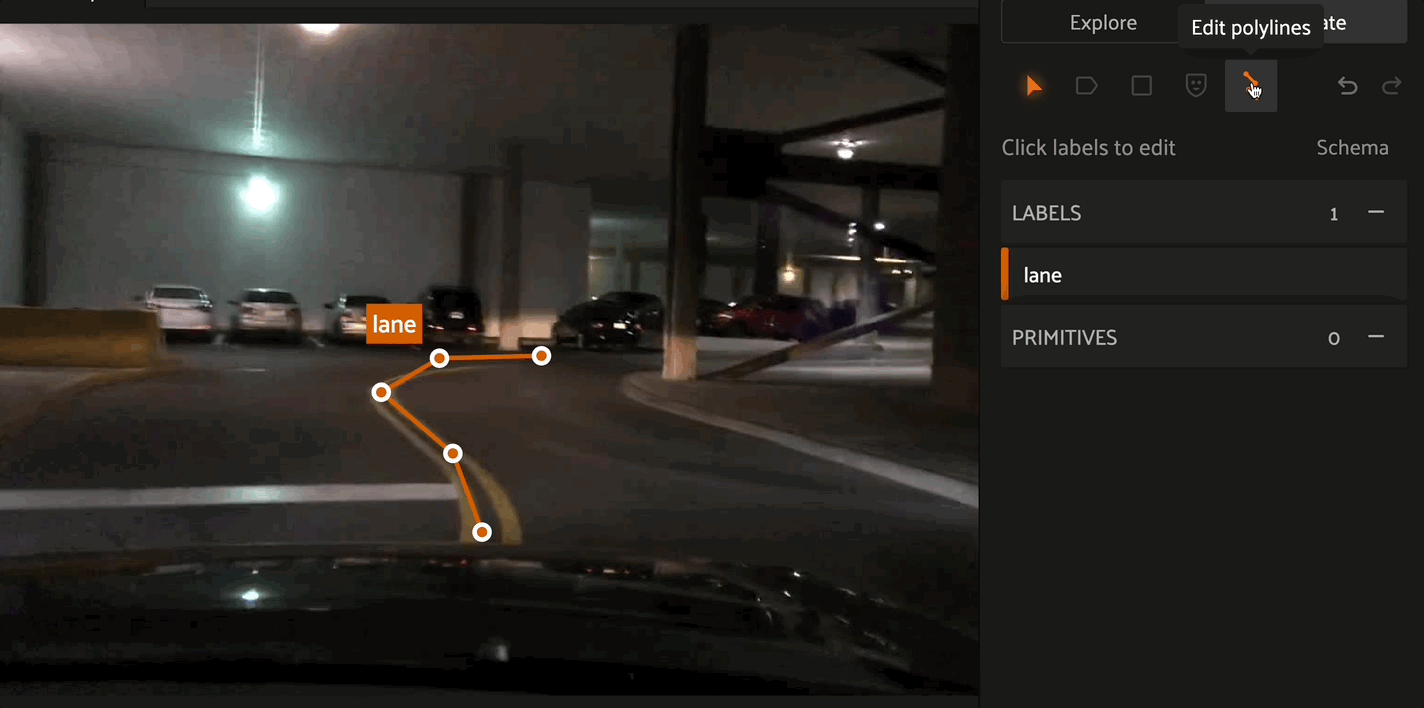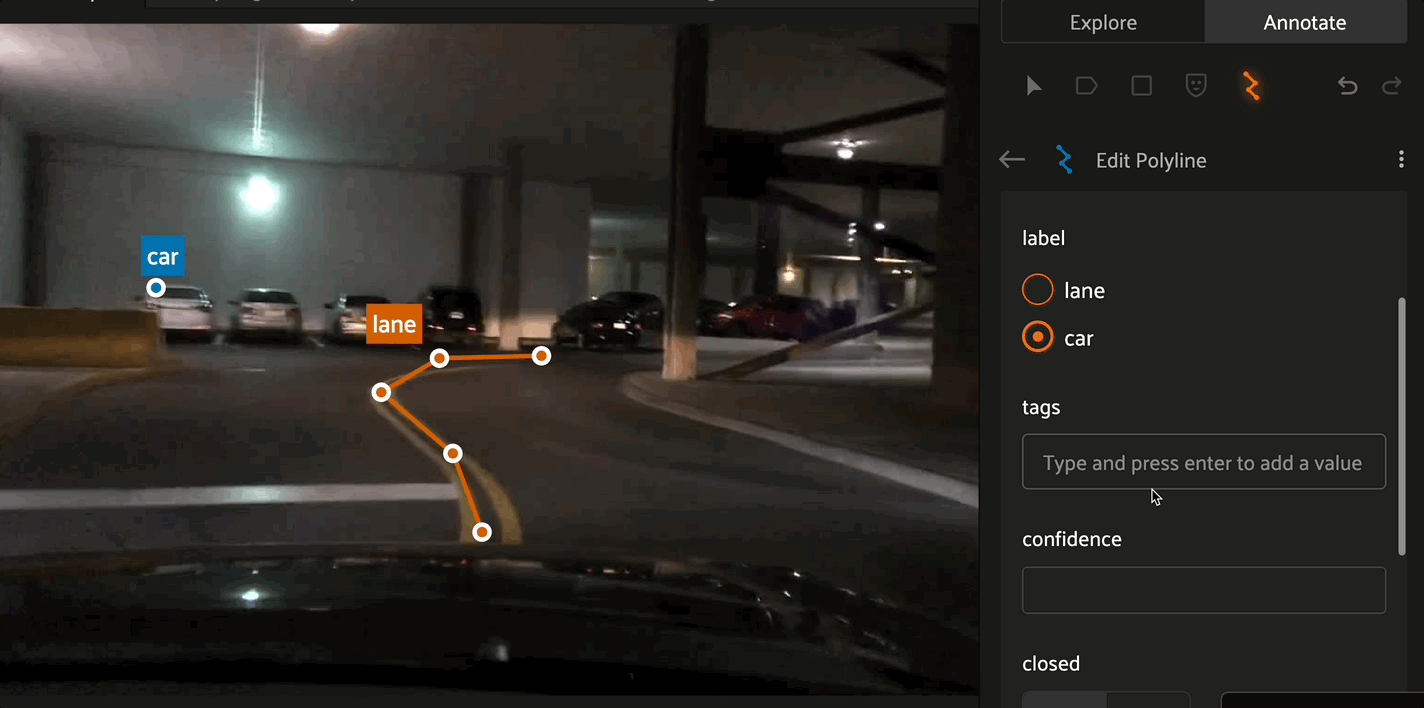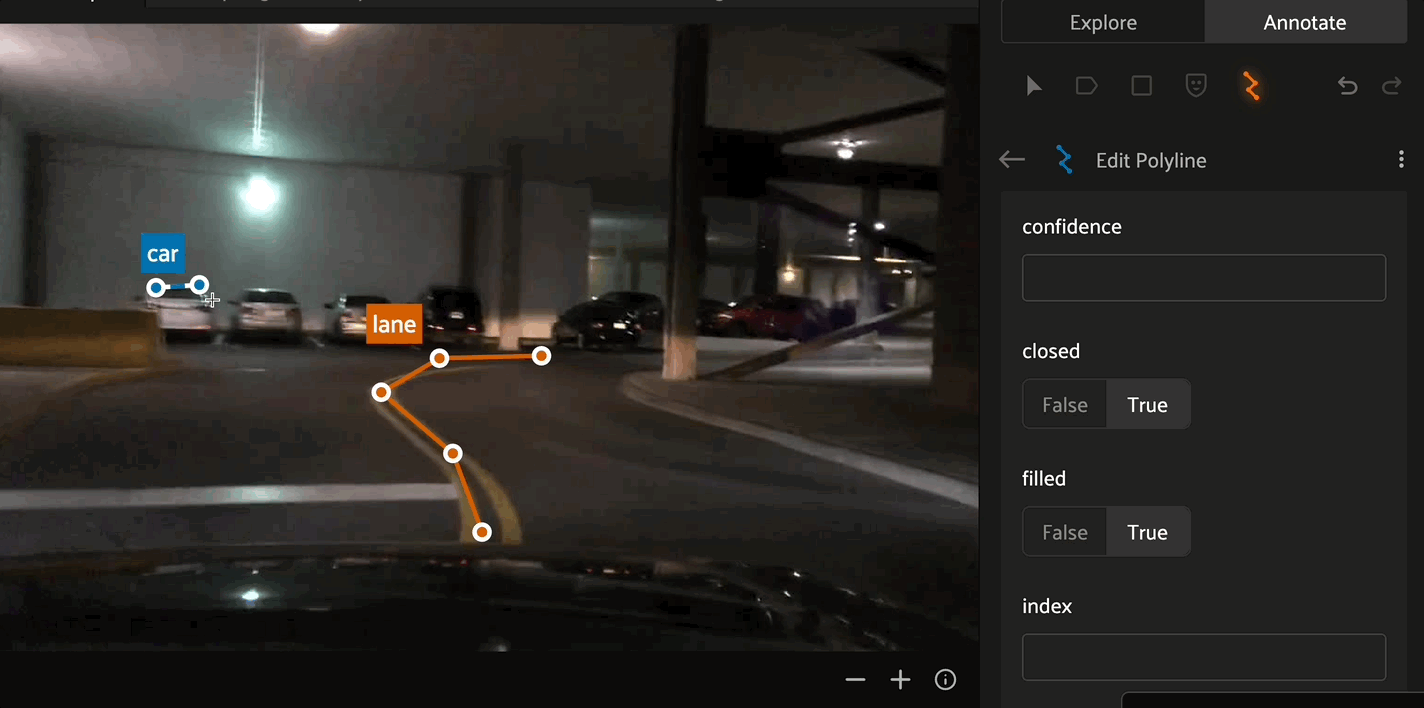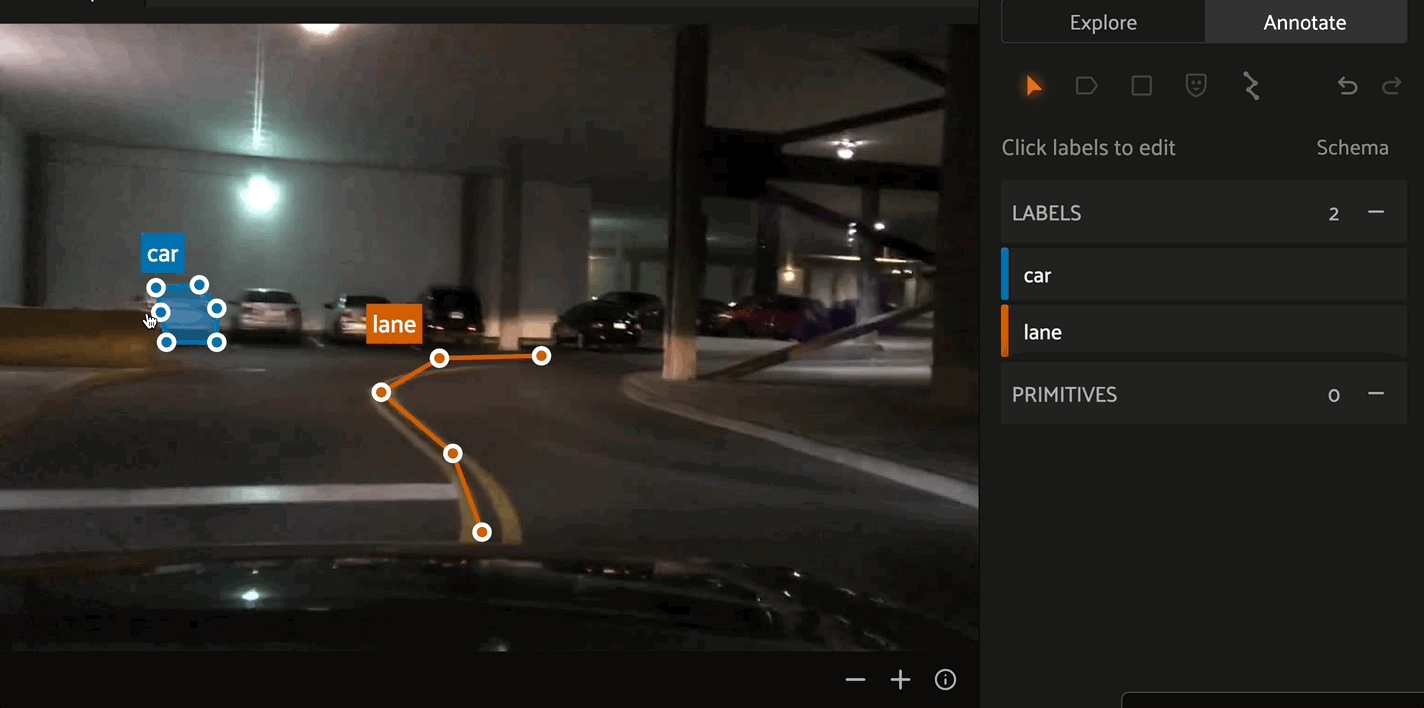
Polygon labels in FiftyOne are simply polylines with the closed and filled attributes set to True. Configure the label schema to use default values for these attributes if desired, or configure these values for each label instance. Similar to polylines, edit polygons by clicking the canvas to place vertices defining the boundary of the polygon. Clicking an existing boundary segment allows you to add new vertices into an existing polygon. Right click the canvas to finish editing the current polygon.
Editing in the Right Sidebar#
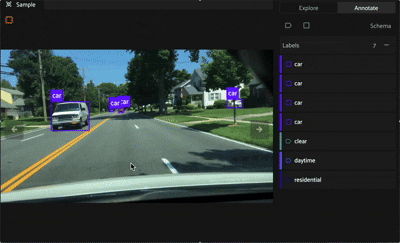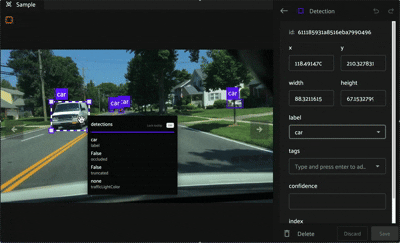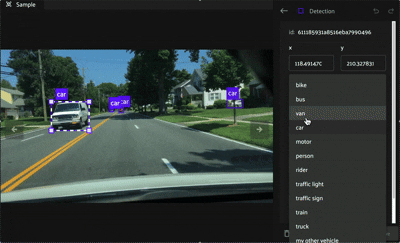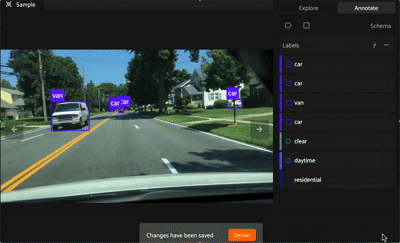
Labels can be selected by clicking on its bounding box or on the item in the list in the right sidebar, which will highlight the associated bounding box on the annotation canvas if the label is a detection, then clicking the chosen row. This will open the editing panel in the right sidebar.
Spatial Properties#
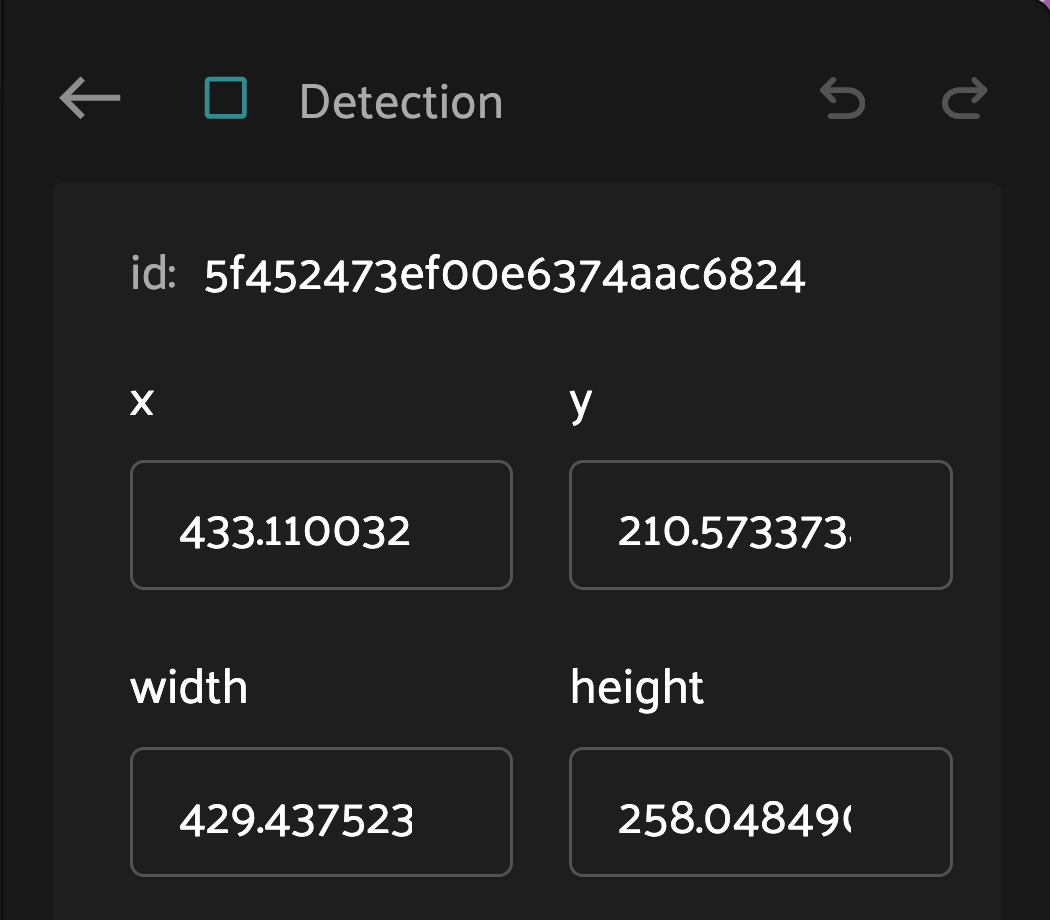
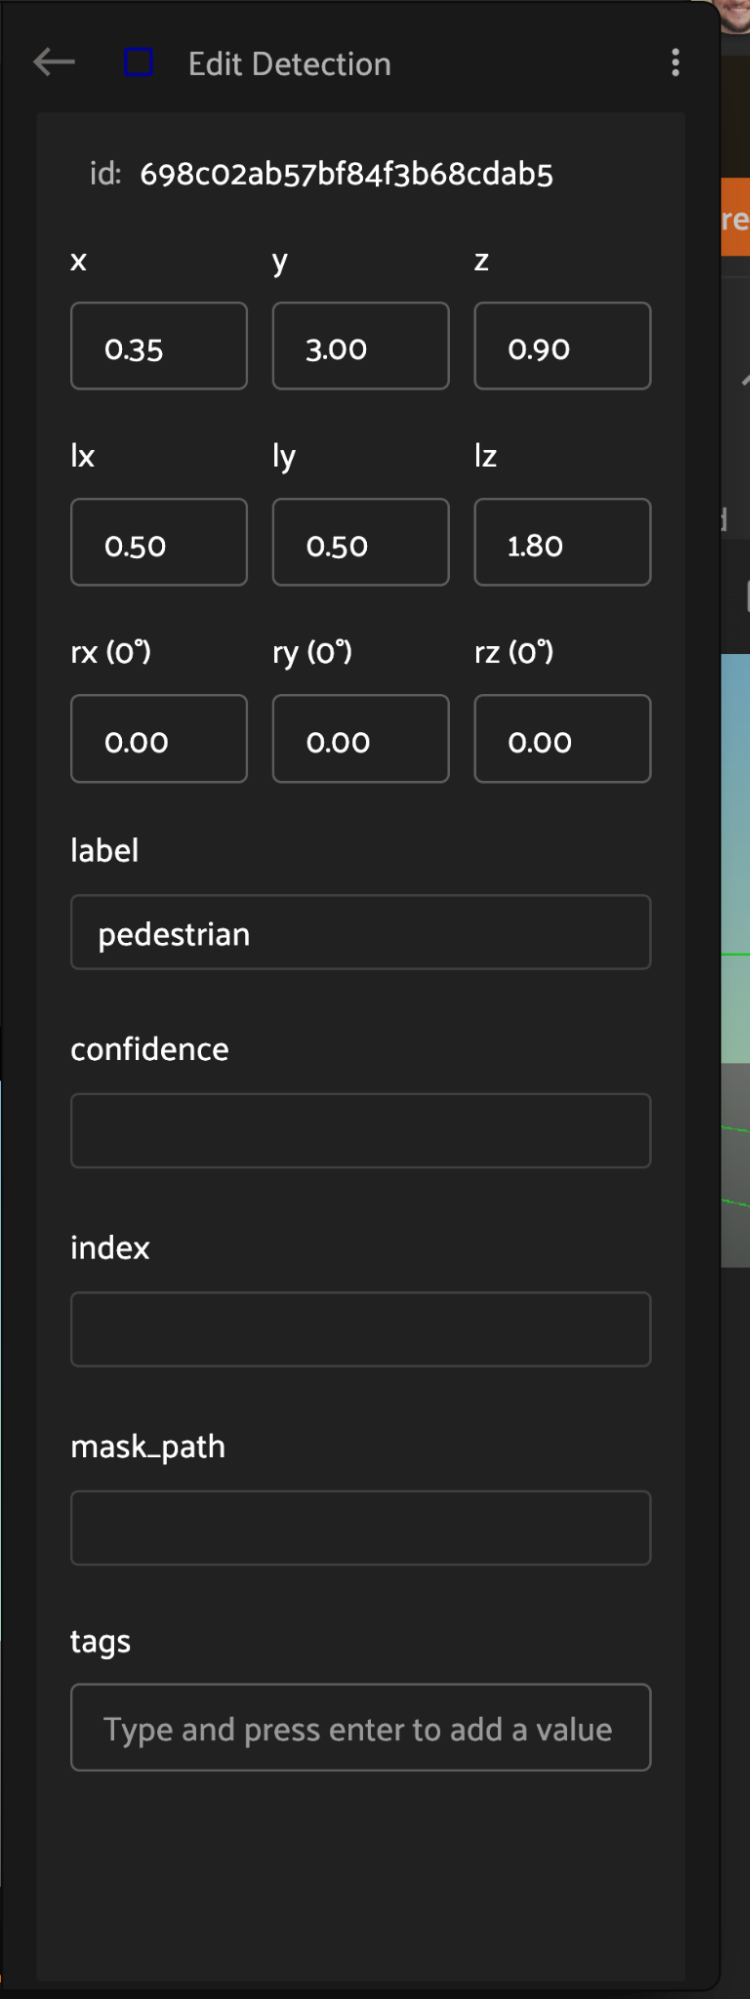
Within the editing panel spatial coordinates of the label are displayed. For example, for detection type labels the x/y coordinates, width, and height can be adjusted. Editing the x/y coordinates and/or the width/height will display the changes in the annotation canvas. This allows finite adjustments that could be difficult with a mouse.
Attributes#
The editing panel also enables editing the label, tags, confidence, index properties, and custom properties depending on the configured annotation schema.
How to: Video Annotation#
Label faster with AI
Track an object’s mask across frames automatically with AI-assisted video tracking.
In-App video annotation lets you draw object tracks and timeline events on video samples. The Annotation Schema and right-sidebar editing behavior on the Annotate tab are the same as for image annotation, and edits auto-save through the database the same way. The video annotation surface adds a timeline below the canvas for scrubbing and to visualize tracks that maintain object identities and events across frames.
Requirements#
Video annotation requires:
A
videotype datasetImages sampled from the video and stored on the frames (see frame views)
Metadata computed on the samples
import fiftyone as fo

dataset = fo.load_dataset("my-video-dataset")
assert dataset.media_type == "video"
dataset.compute_metadata()
dataset.to_frames(sample_frames=True)
Creating Object Tracks#
Track objects with AI
Instead of annotating each frame, you can prompt an object’s mask on one frame and track it across the rest — see AI-assisted video tracking.
To create an object track, the
Annotation Schema needs to contain a
compatible field. Create a new field in the
Schema Manager that is prefixed with frames.
indicating that the field will have frame-level labels of the object — for
example per-frame Detections for
the bounding box of the object per frame.
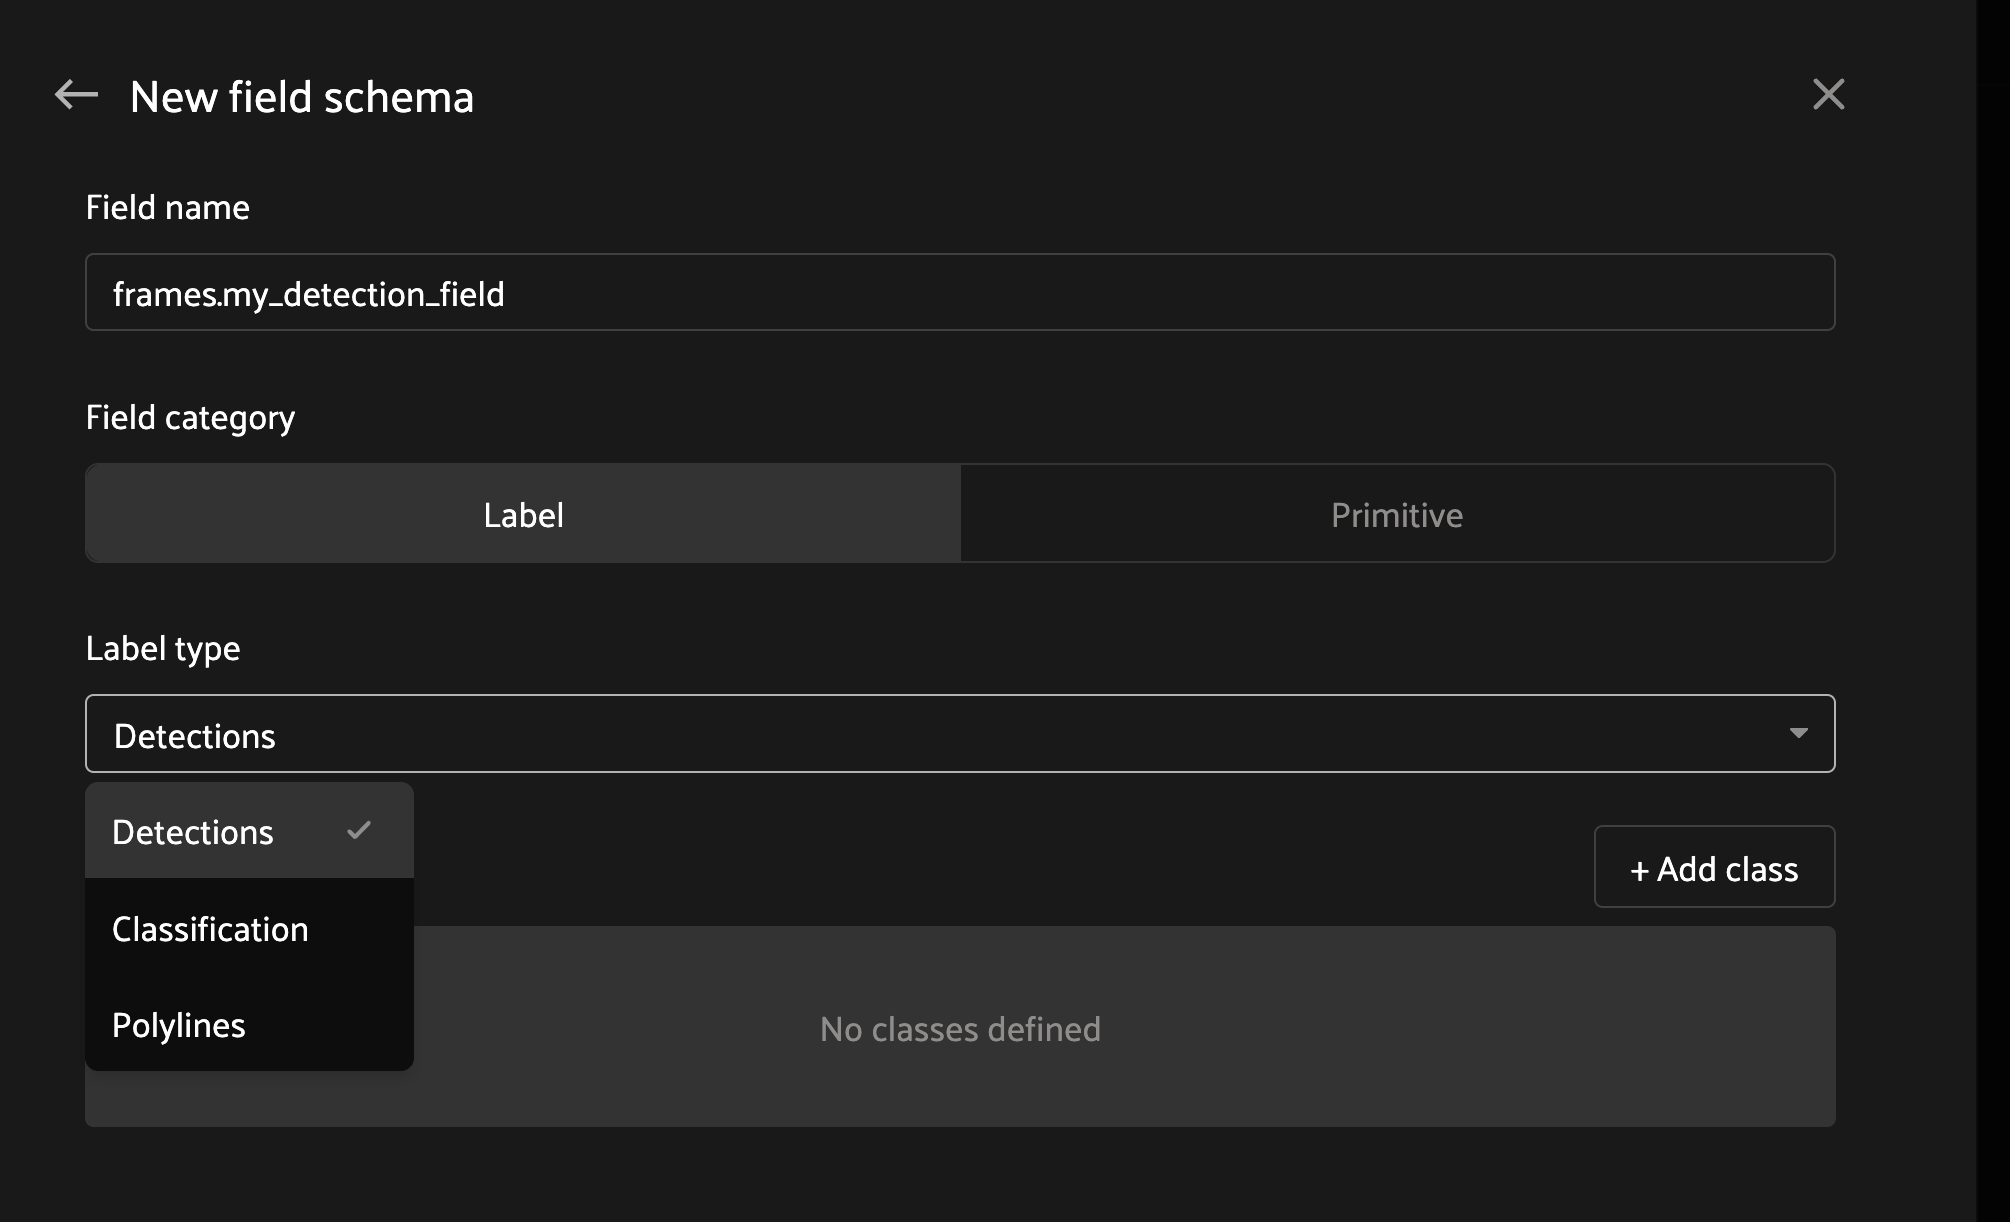
To start a new object, click the bounding box icon in the annotate actions
toolbar and draw a box on the current frame. The first box creates a new
Instance and marks a keyframe for
the object at that frame. Scrub the playhead forward and adjust the box on a
second frame to add the next keyframe. FiftyOne linearly interpolates the
bounding box between adjacent keyframes and updates the intermediate labels.
Polylines and mask labels are not
interpolated, simply propagated forward.
The start and end frames of an object track can be adjusted by dragging the handles on the ends of the track segment in the timeline. Track segments can also be dragged in their entirety to a new frame.
Static and Dynamic Attributes#
Tracks support two kinds of attributes, configured per-attribute in the Annotation Schema:
Static attributes apply to the whole track. Their value is the same on every frame. Use these for properties that don’t change across the track’s lifetime (e.g. a vehicle’s
makeorcolor).Dynamic attributes can change value across a track. Use these for properties that vary mid-track (e.g.
occluded,turn_signal). Each dynamic attribute has its own nested track under the parent object track.
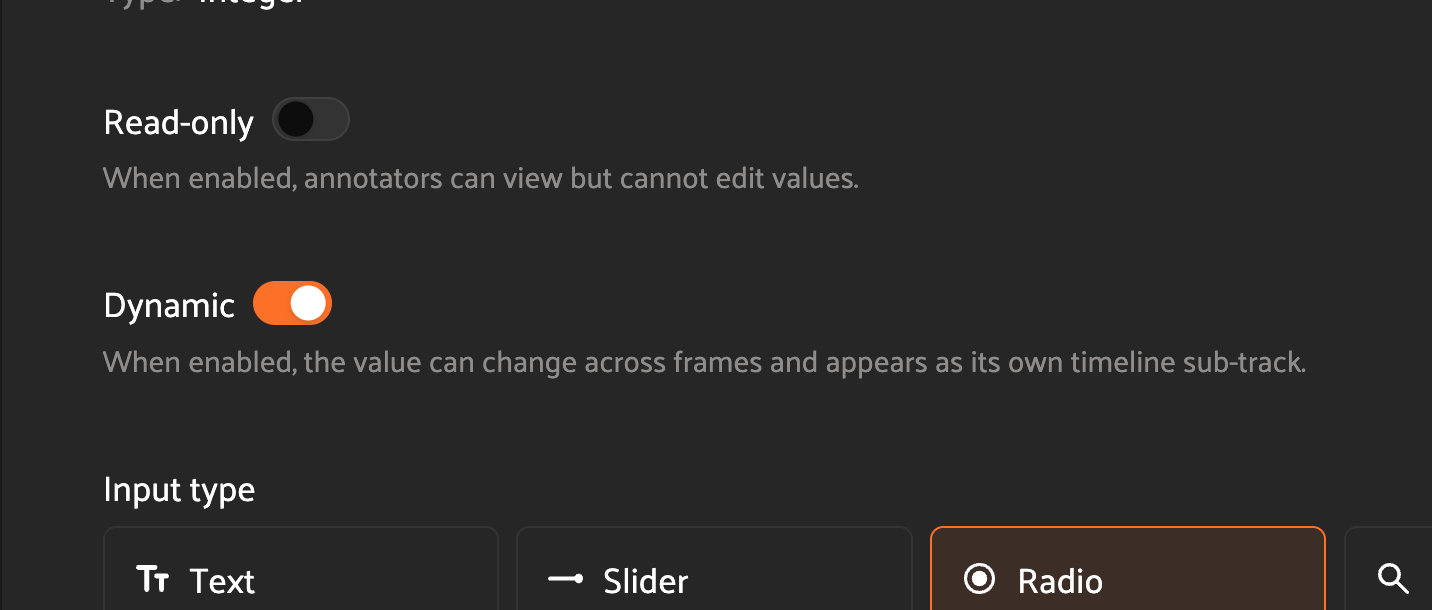
Static and dynamic attributes are both edited in the right sidebar. Static attribute updates apply to every frame in the track. Dynamic attribute updates propagate forward from the playhead until the next attribute value change. Note that dynamic attributes do not have explicit keyframes.
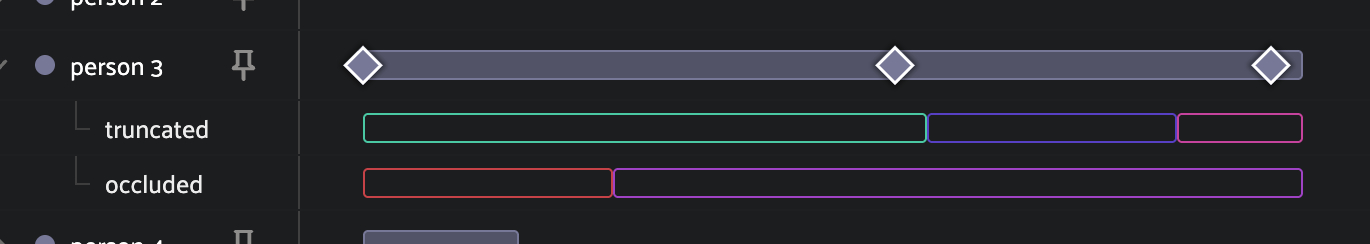
Keyframes#
A keyframe is a frame at which a track’s value is explicitly set, as opposed to interpolated from neighboring frames. Each object track row in the timeline shows its keyframes as diamonds.
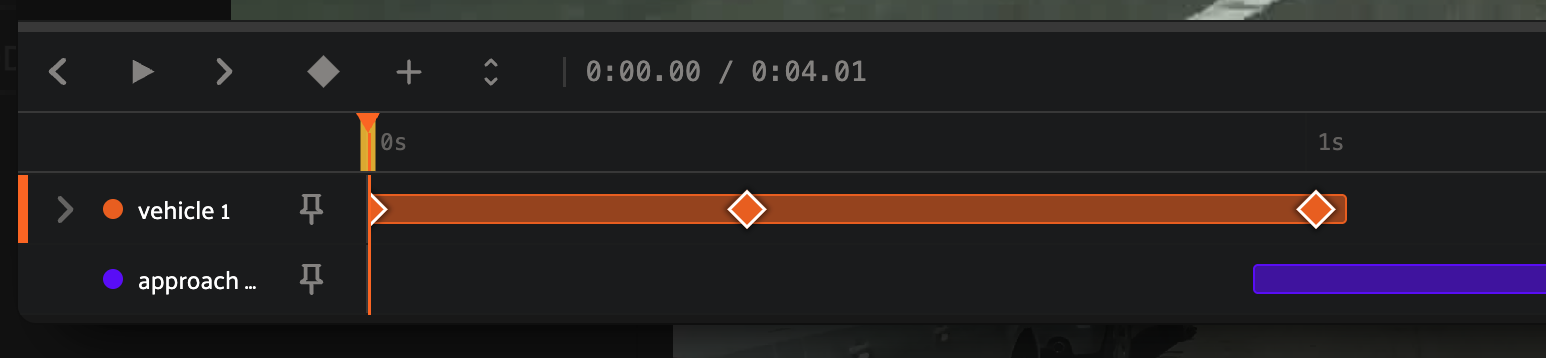
There are two ways a track’s value can vary over time:
Geometry keyframes record an explicit bounding box, mask, or polyline position. They are created automatically when you draw or resize an object, or by pressing K at the playhead to commit the current geometry without resizing. Between adjacent bounding box keyframes, FiftyOne linearly interpolates the bounding box on edits. These keyframes are indicated by diamonds.
Dynamic attribute changes are propagated forward in time rather than interpolated. When you change a dynamic attribute’s value from the right sidebar, the new value is held forward until the next attribute change. These changes are not explicit keyframes; they are indicated by differently colored segments in the attribute sub-tracks.
The first frame of a track is always a keyframe. Press K with a track
selected, or click the  toolbar button, to manually mark a
geometry keyframe at the playhead without resizing the box. The same action
also removes an existing keyframe at the playhead, which triggers a new
interpolation/propagation between the adjacent keyframes.
Temporal Events#
Sample-level events (also known as
Temporal Detections) are rendered as horizontal
bars in the Events lane at the bottom of the video timeline. Each event
has a label, a support=[start_frame, end_frame], and user-defined custom
attributes.
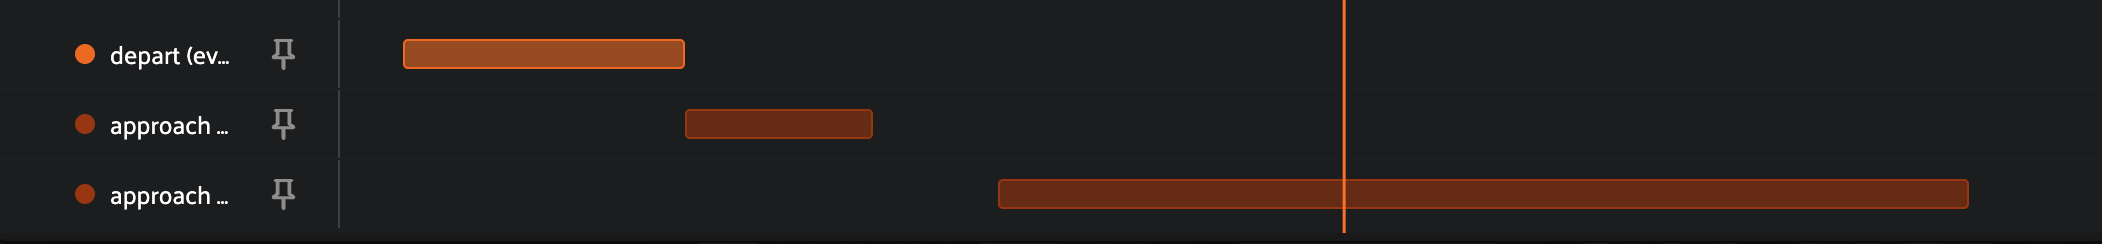
To create an event, click the  button in the timeline
toolbar to create a new event at the current playhead position. Drag either
edge of an event bar in the timeline to adjust
support. Select an event
to edit its label and attributes in the right sidebar.
Timeline Operations#
Drag-to-retime. Click and drag an event or object track horizontally to move it to a new start and end time.
Split. With the playhead on the desired frame and a track selected,
click the  button in the toolbar to split the track into
two tracks at the playhead. The segment before the playhead retains the
original
Instance; the segment after the playhead is assigned a new
Instance. Static attributes are copied to both tracks and dynamic
attributes are split at the playhead.
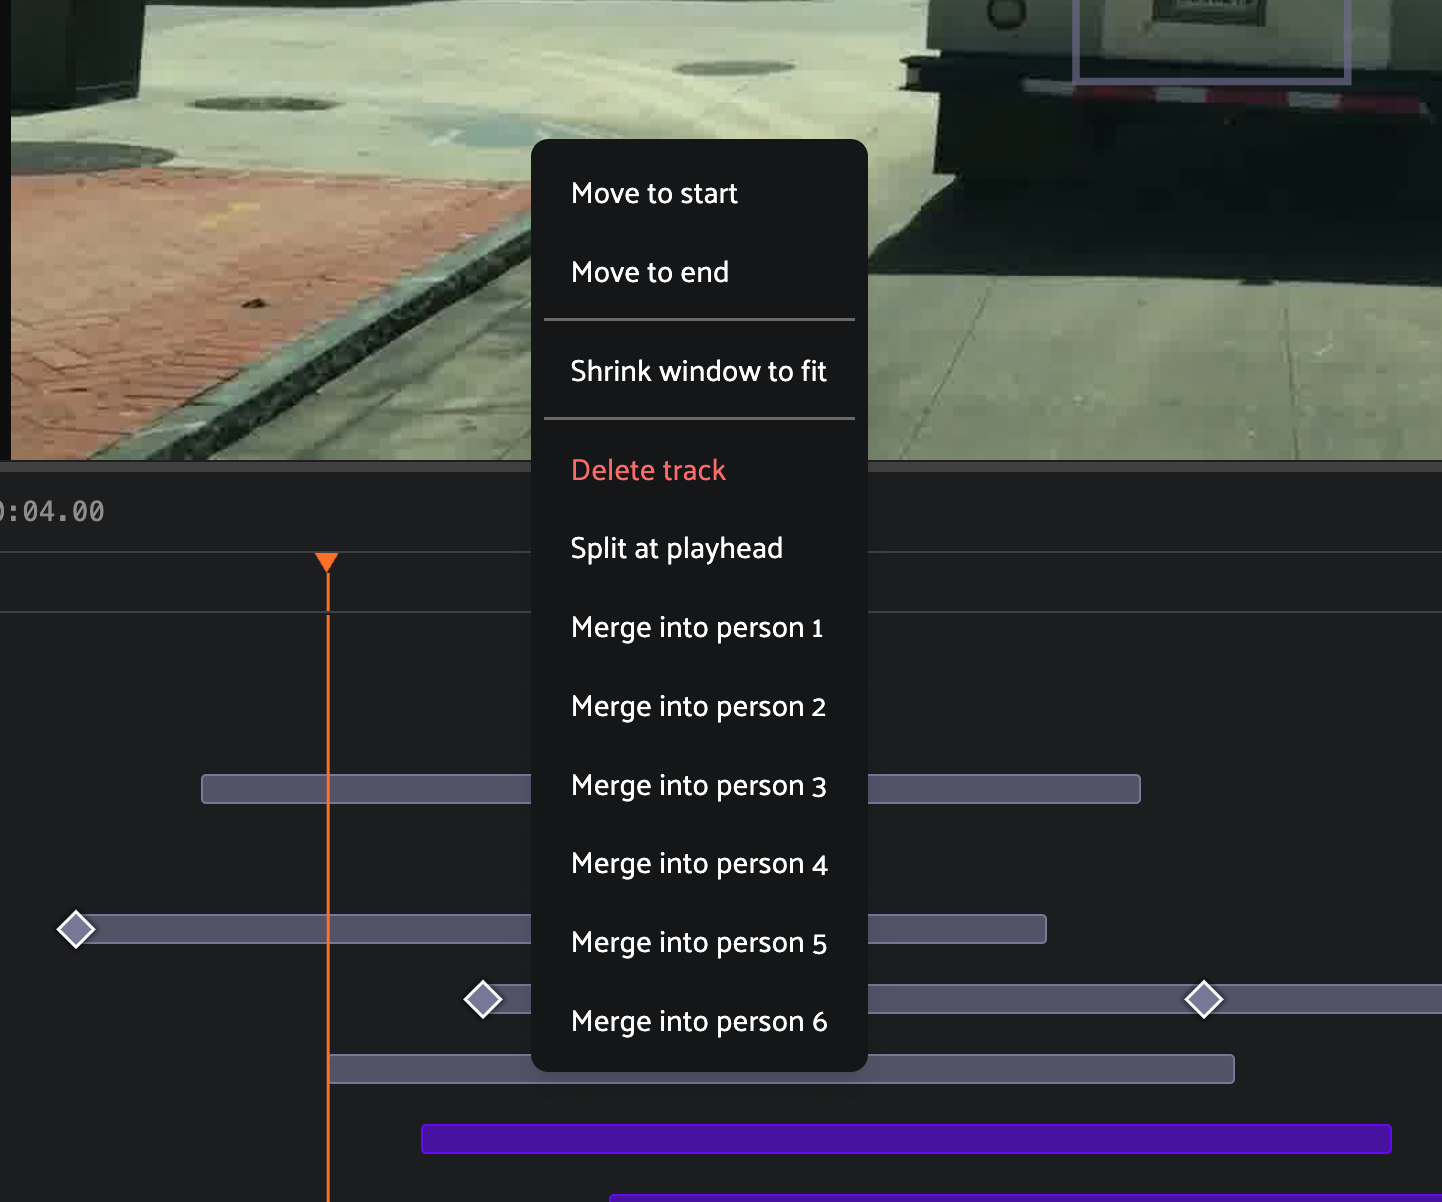
Merge. Right click an object track to merge it into another track of
the same class label. The two tracks combine into a single Instance
with the union of their keyframes. On conflict, attribute values from the
track being merged into take priority.
Delete a track by right clicking the track row and choosing Delete track.
Loop a track by right clicking the track and choosing Shrink window to fit. This loops playback over the track’s duration, letting you focus on a specific object or event.
Annotating Dynamic Groups as Video#
An image dataset dynamically grouped into ordered
groups can be annotated as a video. Each frame is one sample of the group, in
order_by order, so object tracks, keyframes, dynamic attributes and events
span the group’s samples, and every edit is written to the sample it lands on.
The view must be an ordered dynamic group of images played on the timeline.
An ordered group plays on the timeline only when the dataset has a compound
index that starts with the group_by field(s) followed by the order_by
field, and opens on it by default. Without that index the group is shown with
pagination, and the timeline option in the display options (cog icon) above
the sample is disabled and names the index to create:
import fiftyone as fo

dataset = fo.load_dataset("my-image-dataset")
dataset.create_index([("scene", 1), ("timestamp", 1)])

view = dataset.group_by("scene", order_by="timestamp", order_by_key=0.0)
session = fo.launch_app(view)
Open a group in the modal and switch to the Annotate tab.
The group opens in the video annotation surface with the same tools as a video
sample. The timeline clock counts frames from 1 and shows the order_by
value of the sample under the playhead beside it, for example
#3 / #12 (30).
The right sidebar shows the fields of the sample under the playhead and
updates as you scrub. The order_by field is read-only in this view because
changing it would reorder the frames; edit it from the ungrouped view. Fields
are the samples’ own fields, so there is no frames. prefix.
A dynamic group shown with pagination, which is every unordered group, is annotated one sample at a time. The Annotate tab edits the group element on screen as an ordinary sample, and the paginator below it moves between the group’s elements.
How to: 3D Label Annotation#
Cuboids, 3D polylines and their tracks are annotated in the 3D tile, with camera views, World and Ego fill, and keyframes. See 3D Annotation.
How to: Editing Primitives#
Editing in the Right Sidebar#
Clicking on a primitive field in the “Annotate” tab will open the editing panel in the right sidebar. Like editing a label’s attributes, you can edit the primitive’s values per the Annotation Schema.
How to: AI assisted annotation 🚀 NEW#
FiftyOne can put models to work in the annotation editor so you spend less time labeling by hand. Prompt masks with a segmentation model, track objects across video frames, or auto-label a whole dataset from a few examples with Agentic Labeling. These features run on your own GPU infrastructure as services started by an administrator.
Image segmentation#
Instead of drawing a mask by hand, you can prompt one with a segmentation model. Select the AI assistance tool in the mask toolbar, then click positive points on the object and negative points on regions to exclude; the model returns a mask after each click, so you can add points to refine it before saving. A built-in model works out of the box, and Voxel51 deployments can run larger, finetuned models as a service on their own GPUs.
See Creating a Segmentation label for the mask toolbar and drawing basics.
Video object tracking#
On video, prompt an object’s mask on one frame and track it across the remaining frames automatically. Review the tracked masks and add prompts on any frame to correct them. Video tracking is a Voxel51 feature powered by a segmentation model running as a service.
See How to: Video Annotation for the video annotation basics.
Agentic Labeling#
Agentic Labeling uses a prompt-driven vision-language model to label an image dataset from a few examples: describe what you want, optionally add positive and negative example samples, preview the results, then apply the agent across your dataset for review. It runs as a Voxel51 service that an administrator starts.
See the Agentic Labeling guide for the full workflow, supported tasks, and prompting tips.