#### NOTE
This is a **community plugin**, an external project maintained by its respective author.
Community plugins are not part of FiftyOne core and may change independently.
Please review each plugin’s documentation and license before use.

# fo-vllm
[FiftyOne](https://voxel51.com/fiftyone/) plugin for VLM inference via [vLLM](https://github.com/vllm-project/vllm). One operator, any model, any numerous tasks.
## Installation
```shell
fiftyone plugins download https://github.com/Burhan-Q/fiftyone-vllm
```
Or install locally:
```shell
fiftyone plugins create /path/to/fiftyone-vllm
```
Reference vLLM
The `compose.yml` Docker Compose file is included as a reference for launching a local online vLLM server. Uses latest vLLM tag, was tested originally with `vllm==0.16.0` tag.
## Tasks
| Task | FiftyOne Type | Structured Output |
|-----------------------------------------------------------------------------------------------------------------------------------------------------|----------------------|----------------------------------|
| `caption` | `fo.Classification` | `{"text": string}` |
| `classify` | `fo.Classification` | `choice: [classes]` |
| `tag` | `fo.Classifications` | `{"labels": [string]}` |
| `detect` | `fo.Detections` | `{"detections": [{label, box}]}` |
| `vqa` | `fo.Classification` | `{"answer": string}` |
| `ocr` | `fo.Classification` | `{"text": string}` |
| All responses are constrained via [vLLM structured output](https://docs.vllm.ai/en/stable/features/structured_outputs.html) — no free-text parsing. | | |
## Usage
### FiftyOne App
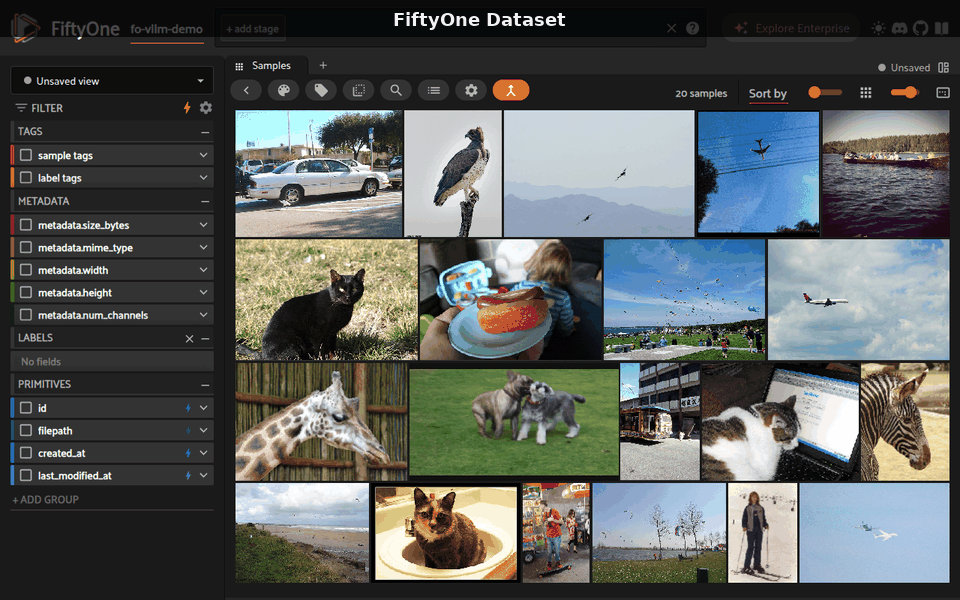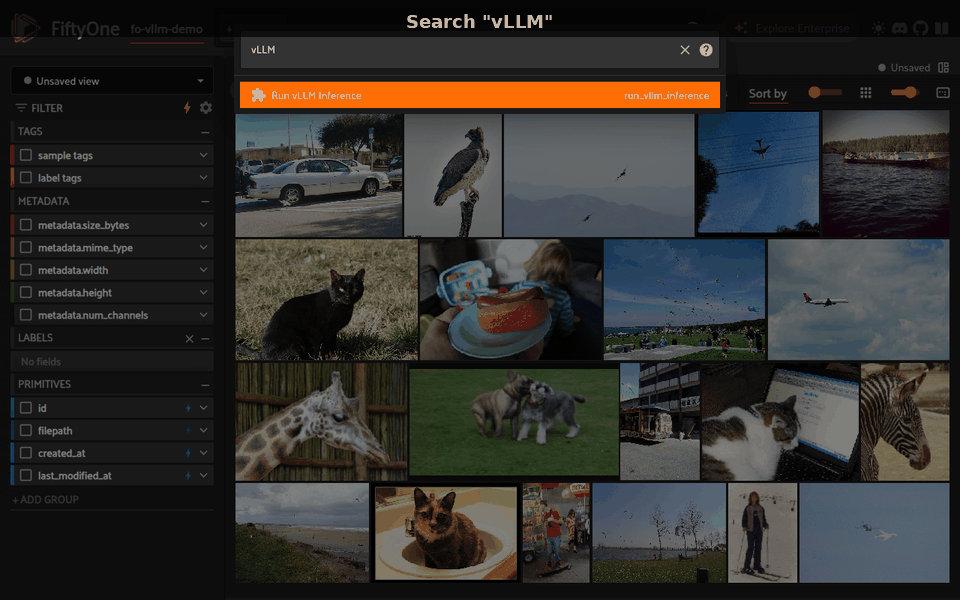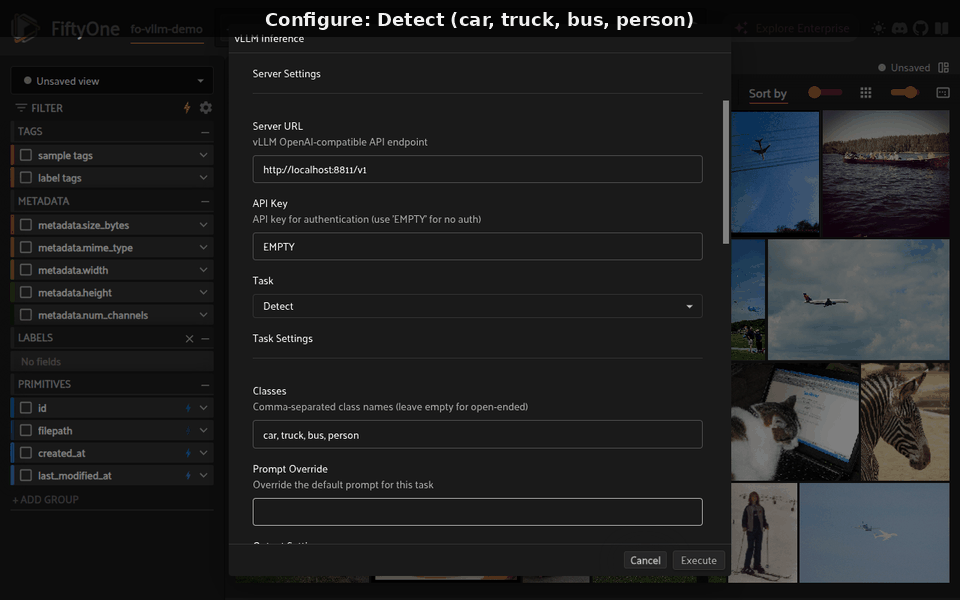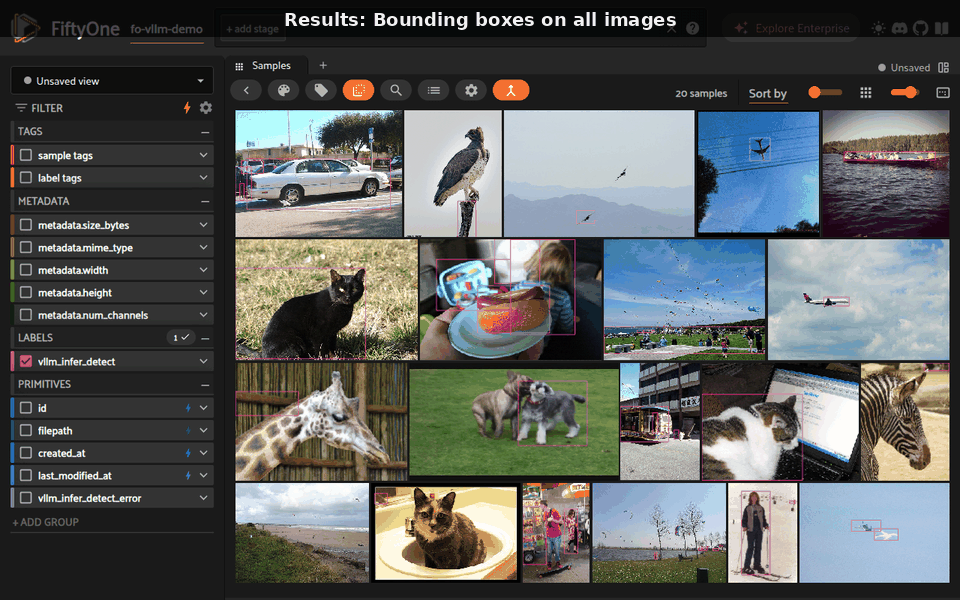
Open the operator browser (``` shortcut), search **Run vLLM Inference**, and fill in the form.
### Python SDK
```python
import fiftyone as fo
import fiftyone.operators as foo
dataset = fo.load_dataset("my-images")
# Caption
foo.execute_operator(
"@Burhan-Q/fo-vllm/run_vllm_inference",
params={
"model": "Qwen/Qwen2.5-VL-7B-Instruct",
"base_url": "http://localhost:8000/v1", # usually will be a remote deployment
"task": "caption",
},
dataset_name=dataset.name,
)
print(dataset.first().vllm_infer_caption.label)
# Classify (with class constraint)
foo.execute_operator(
"@Burhan-Q/fo-vllm/run_vllm_inference",
params={
"model": "Qwen/Qwen2.5-VL-7B-Instruct",
"base_url": "http://localhost:8000/v1",
"task": "classify",
"classes": "indoor, outdoor, aerial",
},
dataset_name=dataset.name,
)
# Detect (with optional class constraint)
foo.execute_operator(
"@Burhan-Q/fo-vllm/run_vllm_inference",
params={
"model": "Qwen/Qwen2.5-VL-7B-Instruct",
"base_url": "http://localhost:8000/v1",
"task": "detect",
"classes": "car, truck, bus",
},
dataset_name=dataset.name,
)
# VQA
foo.execute_operator(
"@Burhan-Q/fo-vllm/run_vllm_inference",
params={
"model": "Qwen/Qwen2.5-VL-7B-Instruct",
"base_url": "http://localhost:8000/v1",
"task": "vqa",
"question": "How many people are in this image?",
},
dataset_name=dataset.name,
)
```
Other tasks (`tag`, `ocr`) follow the same pattern. Use `prompt_override` to replace any task’s default prompt, or `system_prompt` for custom system instructions.
### Additional options
```python
foo.execute_operator(
"@Burhan-Q/fo-vllm/run_vllm_inference",
params={
"model": "Qwen/Qwen2.5-VL-7B-Instruct",
"base_url": "http://localhost:8000/v1",
"task": "caption",
"log_metadata": True, # attach model_name, prompt, infer_cfg to each label
"overwrite_last": True, # overwrite previous result instead of creating new field
},
dataset_name=dataset.name,
)
```
## Output fields
Results are stored as `vllm_infer_{task_default}` (e.g., `vllm_infer_caption`, `vllm_infer_detections`). Subsequent runs auto-increment the suffix unless `overwrite_last` is enabled.
Per-sample errors go to `{field_name}_error`.
## Configuration
### Server
| Parameter | Default | Description |
|-------------|----------------------------|-------------------------------------|
| `model` | (required) | HuggingFace model ID served by vLLM |
| `base_url` | `http://localhost:8000/v1` | vLLM OpenAI-compatible endpoint |
| `api_key` | `EMPTY` | API key |
Also configurable via [FiftyOne secrets](https://docs.voxel51.com/plugins/using_plugins.html#secrets): `FIFTYONE_VLLM_BASE_URL`, `FIFTYONE_VLLM_API_KEY`.
All settings persist across sessions (global + per-dataset). Use “Paste JSON config” mode to import/export configurations.
### Advanced
| Parameter | Default | Description |
|---------------------|---------------|-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
| `temperature` | task-specific | 0.0 for deterministic tasks, 0.2 for generative |
| `max_tokens` | 512 | Max tokens per response |
| `top_p` | 1.0 | Nucleus sampling |
| `batch_size` | 8 | Samples per batch |
| `max_concurrent` | 16 | Parallel requests to vLLM |
| `max_workers` | 4 | Threads for image encoding |
| `image_mode` | `auto` | `auto` (base64) or `filepath` (file:// URLs for local servers, not Docker, with [`--allowed-local-media-path`](https://docs.vllm.ai/en/stable/serving/openai_compatible_server.html#cli-reference)) |
| `coordinate_format` | `pixel` | Detection coordinates: `pixel`, `normalized_1000` (Qwen), or `normalized_1` |
| `box_format` | `xyxy` | Detection box format: `xyxy`, `xywh`, or `cxcywh` |
## Compatible models
Any multi-modal VLM that vLLM can serve, see the [vLLM docs for supported models](https://docs.vllm.ai/en/stable/models/supported_models/#list-of-multimodal-language-models). Tested: Qwen2.5-VL & Gemma3.
## Requirements
- Python >= 3.11, FiftyOne >= 1.13.2
- `openai >= 1.0`, `pillow >= 9.0`
- vLLM >= 0.16 (server-side)
No GPU dependencies on the client.